AI Infrastructure to Power Telecommunications Networks
NeuralMesh™ supports major shifts in telecom: AI moving inside the network and GPU infrastructure as a revenue stream.
USE CASES
One Data Layer for Every AI Workload in Telecommunications
Network telemetry, GPU training, and inference all hit the same storage at once. NeuralMesh serves every tier from one architecture, so speed for one workload never comes at the cost of another.
AI-Native Network Operations
Feed near real time RIC (Radio Access Network (RAN) Intelligent Controller) decisions and edge inference at the speed a 10-millisecond control loop demands.
AI Infrastructure & GPU Monetization
Turning fiber, spectrum, and data center footprint into GPU-as-a-service infrastructure takes isolation and SLAs every tenant can trust. NeuralMesh delivers both.
AI-Powered Customer & Network Operations
Give field technicians instant, grounded answers from technical documentation, network topology, and vendor manuals during tower and edge deployments.
Agentic Customer Care
Let AI agents read subscriber tickets, check networking diagnostics, confirm billing history, and resolve or escalate, without storage lag slowing every step.
Fraud, Churn & Account Takeover
Run fraud, churn, and SIM-swap account takeover models on real time network and subscriber account data, not a stale batch export.
Telecom AI Factory Performance, Proven at Scale
From GPU utilization to decreased costs, these are NeuralMesh benchmarks from WEKA customer AI workload deployments.
0%
GPU utilization achieved
Drives GPU utilization to over 95%, versus roughly 30% on legacy protocols, on comparable AI factory infrastructure
0x
Faster metadata throughput
10x faster metadata throughput than legacy all-flash NAS for small-file, high-frequency network telemetry.
0%
Lower infrastructure cost
Up to an 86% reduction in infrastructure cost on comparable telecom AI workloads.
<0ms
Latency from edge to core
Sub-millisecond latency sustained across distributed edge-to-core deployments.
WHY WEKA
Get More AI Out of the Network You Already Built
WEKA's NeuralMesh delivers sub-millisecond performance from edge to core to feed real-time network AI and turn shared infrastructure into a GPU revenue platform.
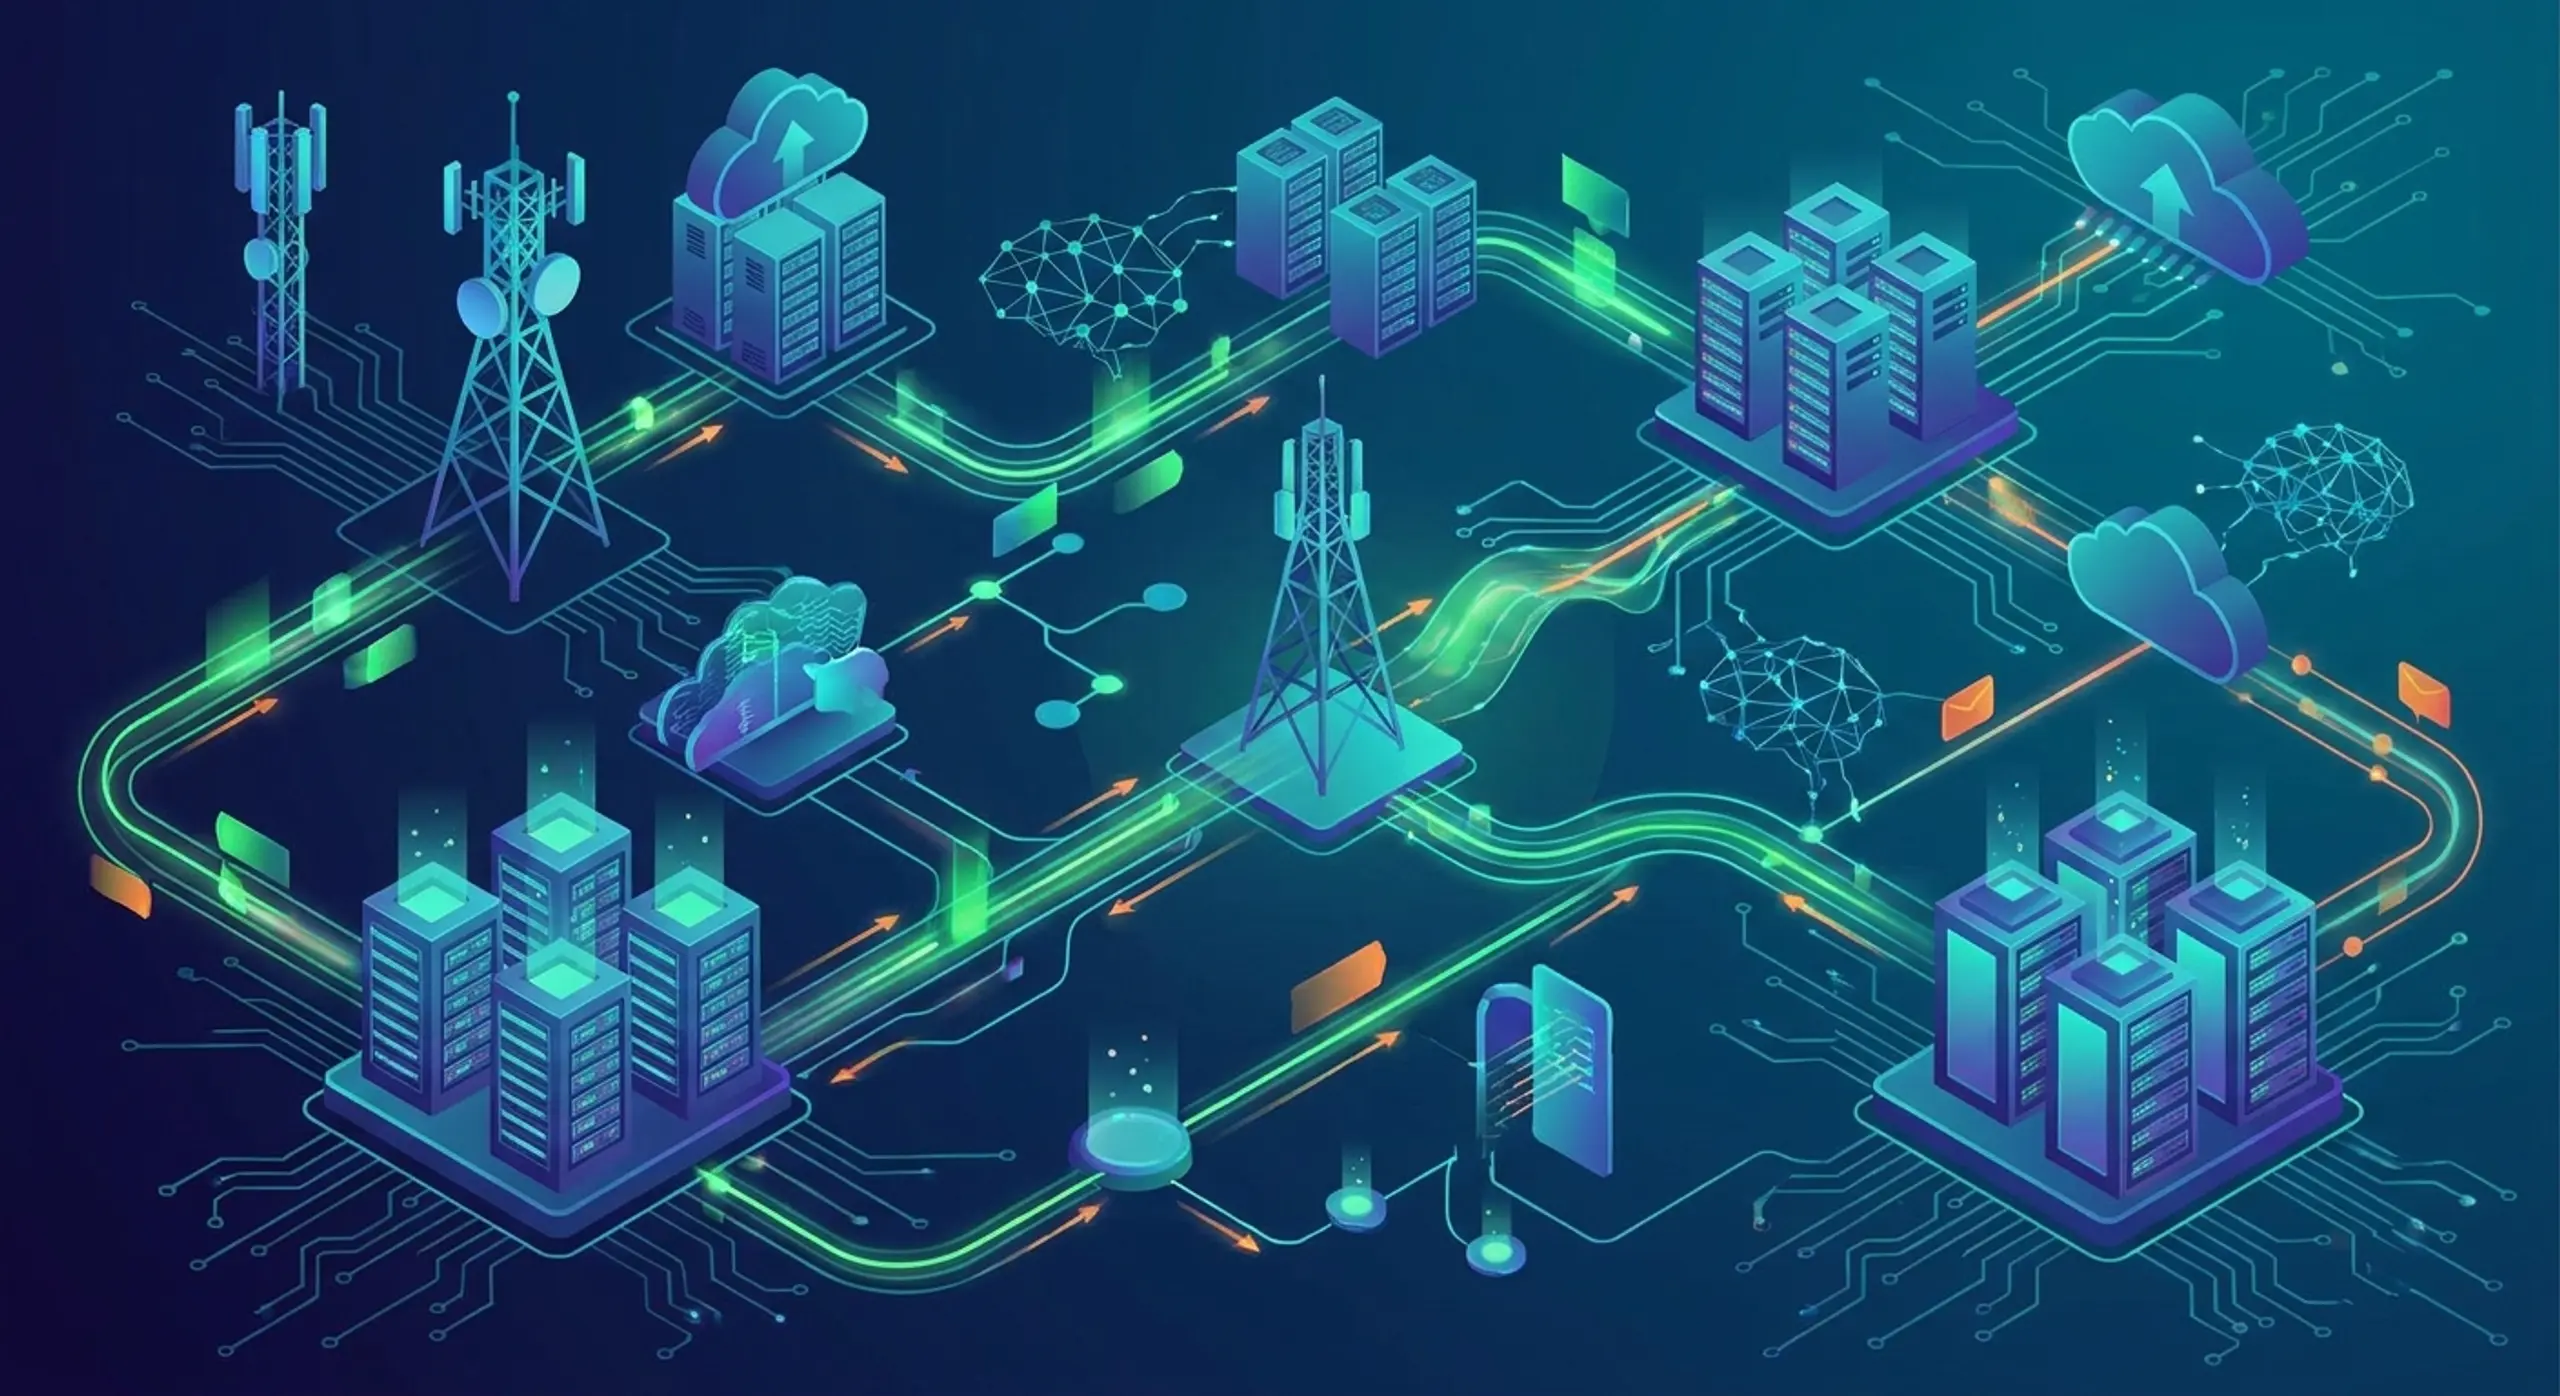
Feed Telecommunication AI at Network Speed
NeuralMesh sustains millions of IOPS at sub-millisecond latency, reacts to signals instantly, resolves decisions in 10ms, and adjusts network signals fast.
1 / 9
Feed Telecommunication AI at Network Speed
NeuralMesh sustains millions of IOPS at sub-millisecond latency, reacts to signals instantly, resolves decisions in 10ms, and adjusts network signals fast.
Unify Telemetry Data From Edge to Core to Cloud
NeuralMesh reads S3 and POSIX as one namespace, skips full-dataset copies, hydrates data only on access, and transfers it zero-copy straight to GPU memory.
Run More AI Without a New Build
NeuralMesh Axon™ tiers TLC and QLC flash automatically, cuts capacity needs by up to 6x, adds compute instead of concrete, and lowers cost per terabyte by up to 40%.
1 / 3


Accelerate Critical AI Without Compromise
Meet strict compliance and sovereign data governance while delivering the extreme throughput your mission-critical models demand.
Frequently Asked Questions
Did this page meet your expectations?