Feed Every GPU. Catch Every Defect. Keep the Line Moving.
WEKA NeuralMesh keeps inspection, simulation, digital twins, and robotics pipelines fed instead of waiting on storage.
Manufacturing and Robotics Using NeuralMesh


USE CASES
One Platform From Chip Design to Factory Floor
Inspection, simulation, and robotics look nothing alike, but they break storage the same way: relentless concurrency and metadata pressure that legacy NAS can't absorb. WEKA® NeuralMesh™ handles all of it from one namespace.
Defect Detection and Predictive Maintenance
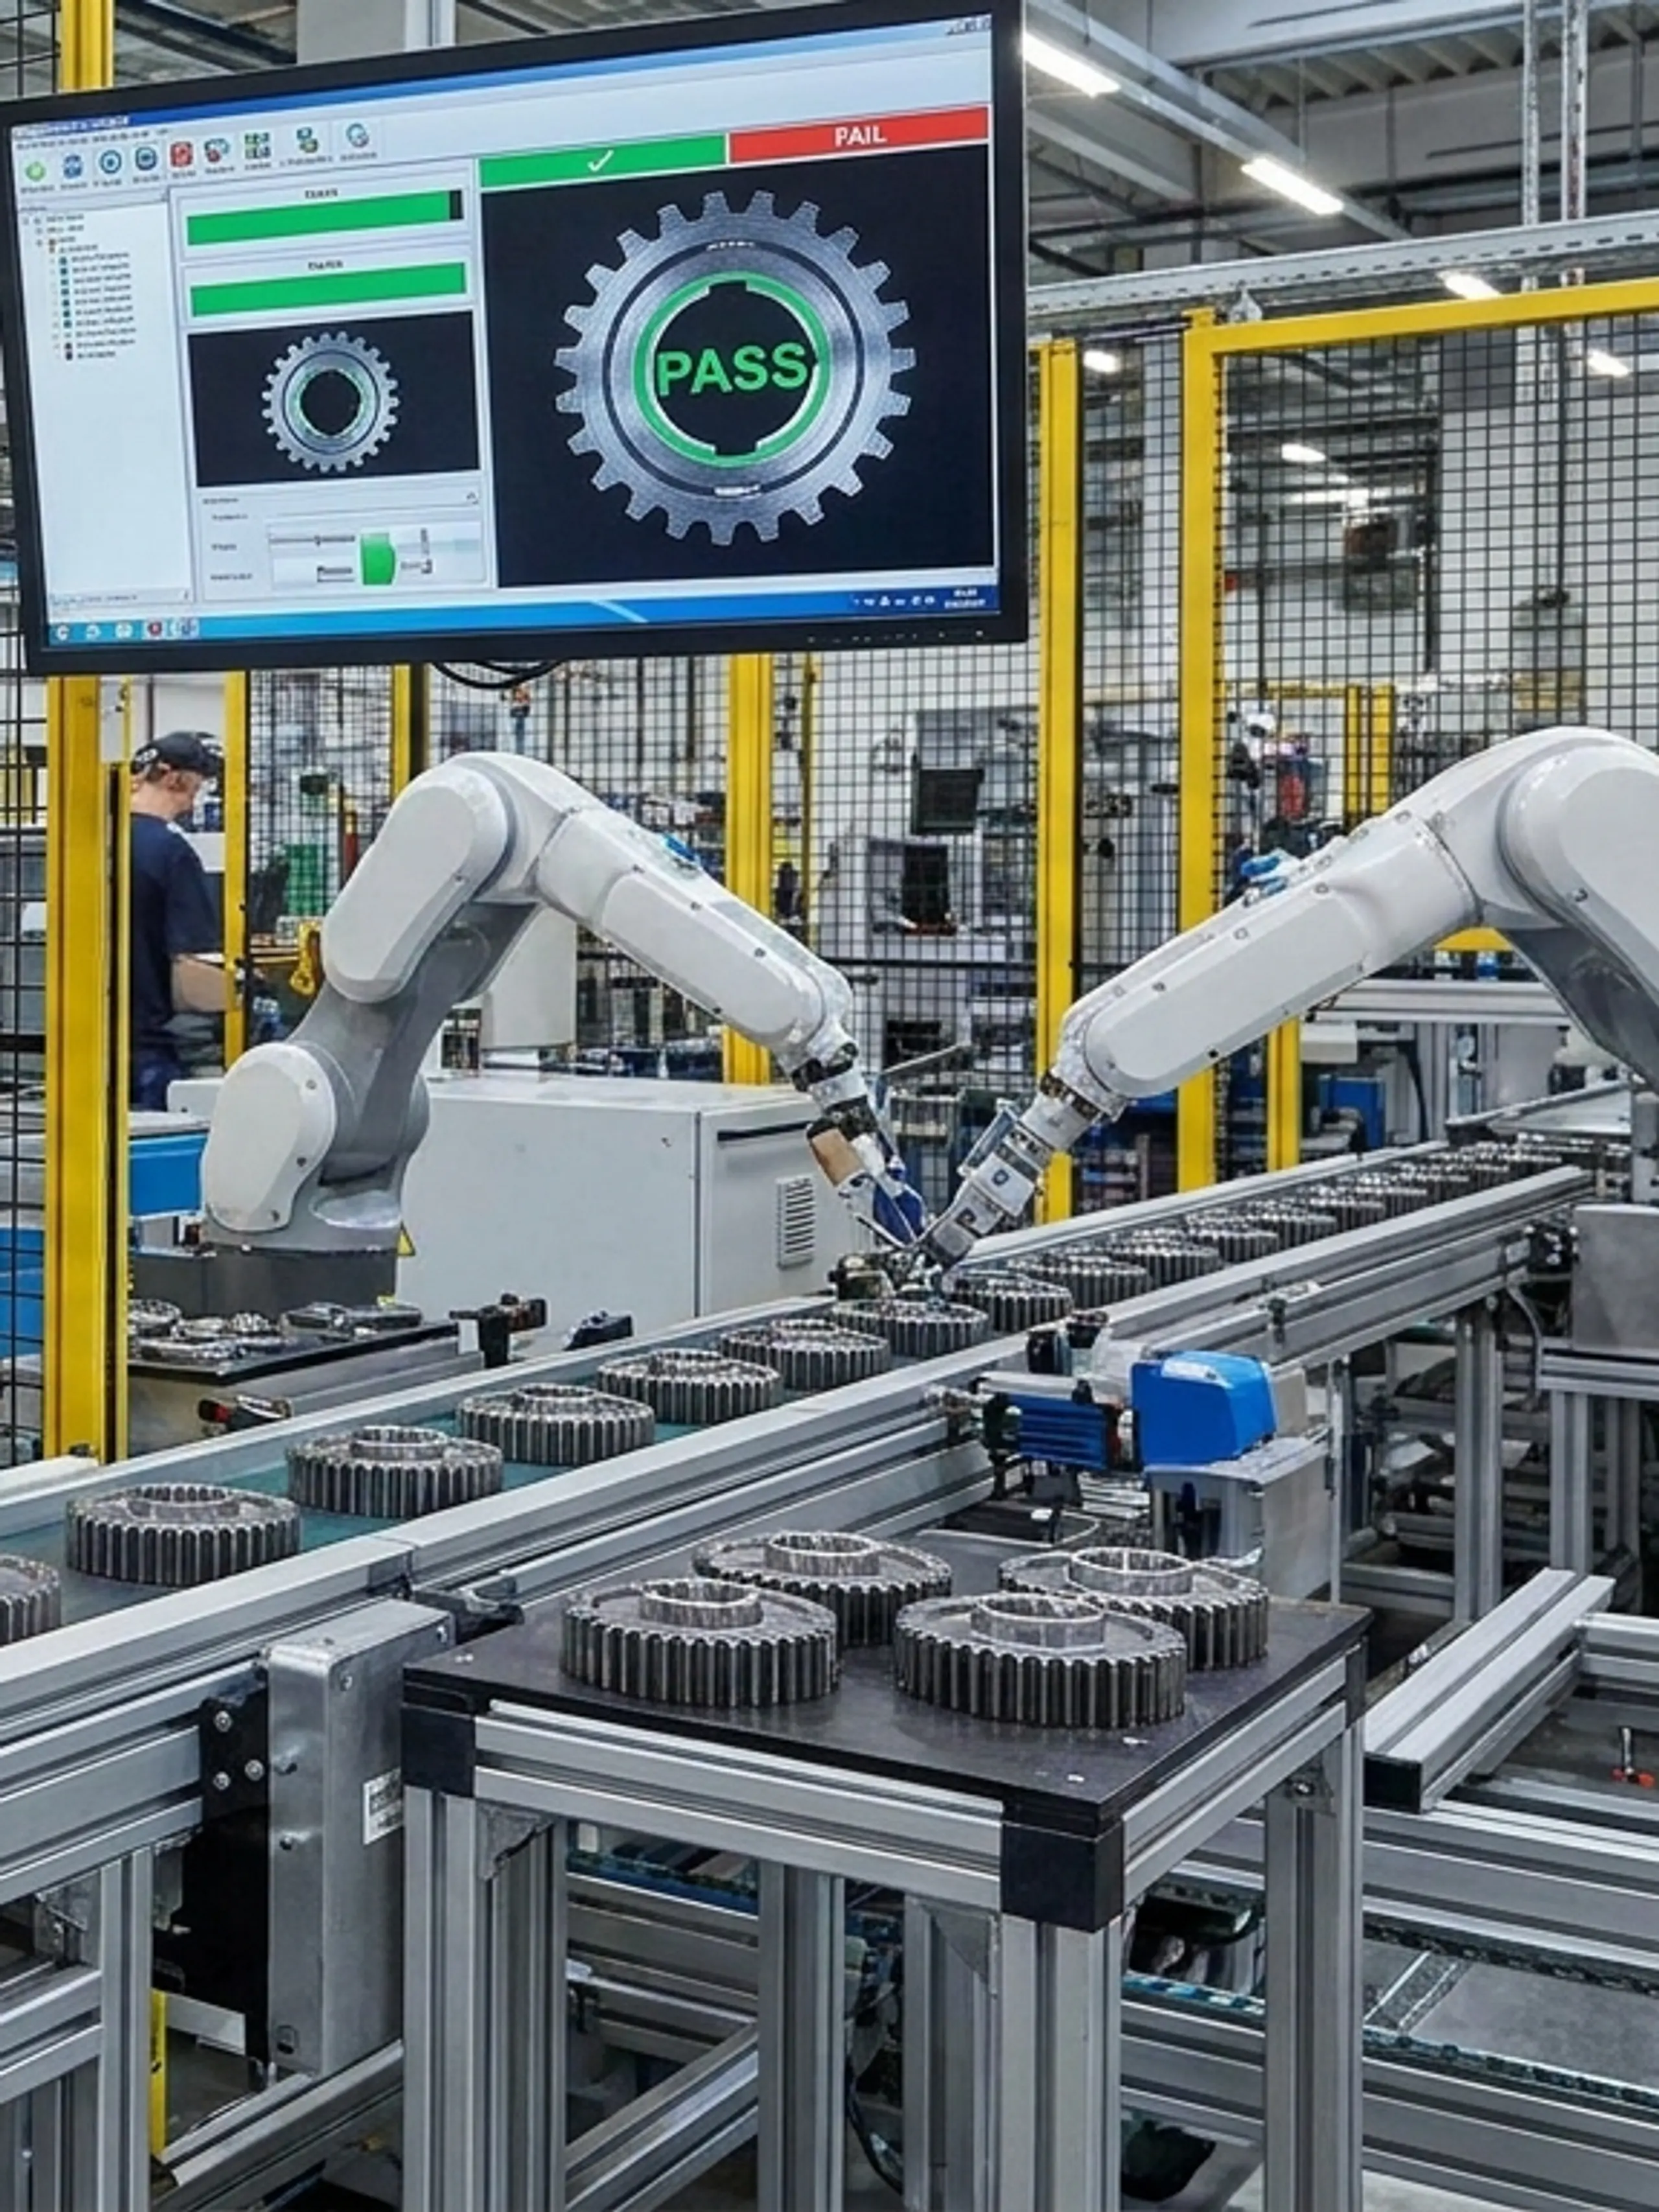
GPU vision systems catch defects at line speed instead of after the batch. NeuralMesh sustains continuous small-file ingest from cameras and sensors without latency drift.
Automotive Manufacturing
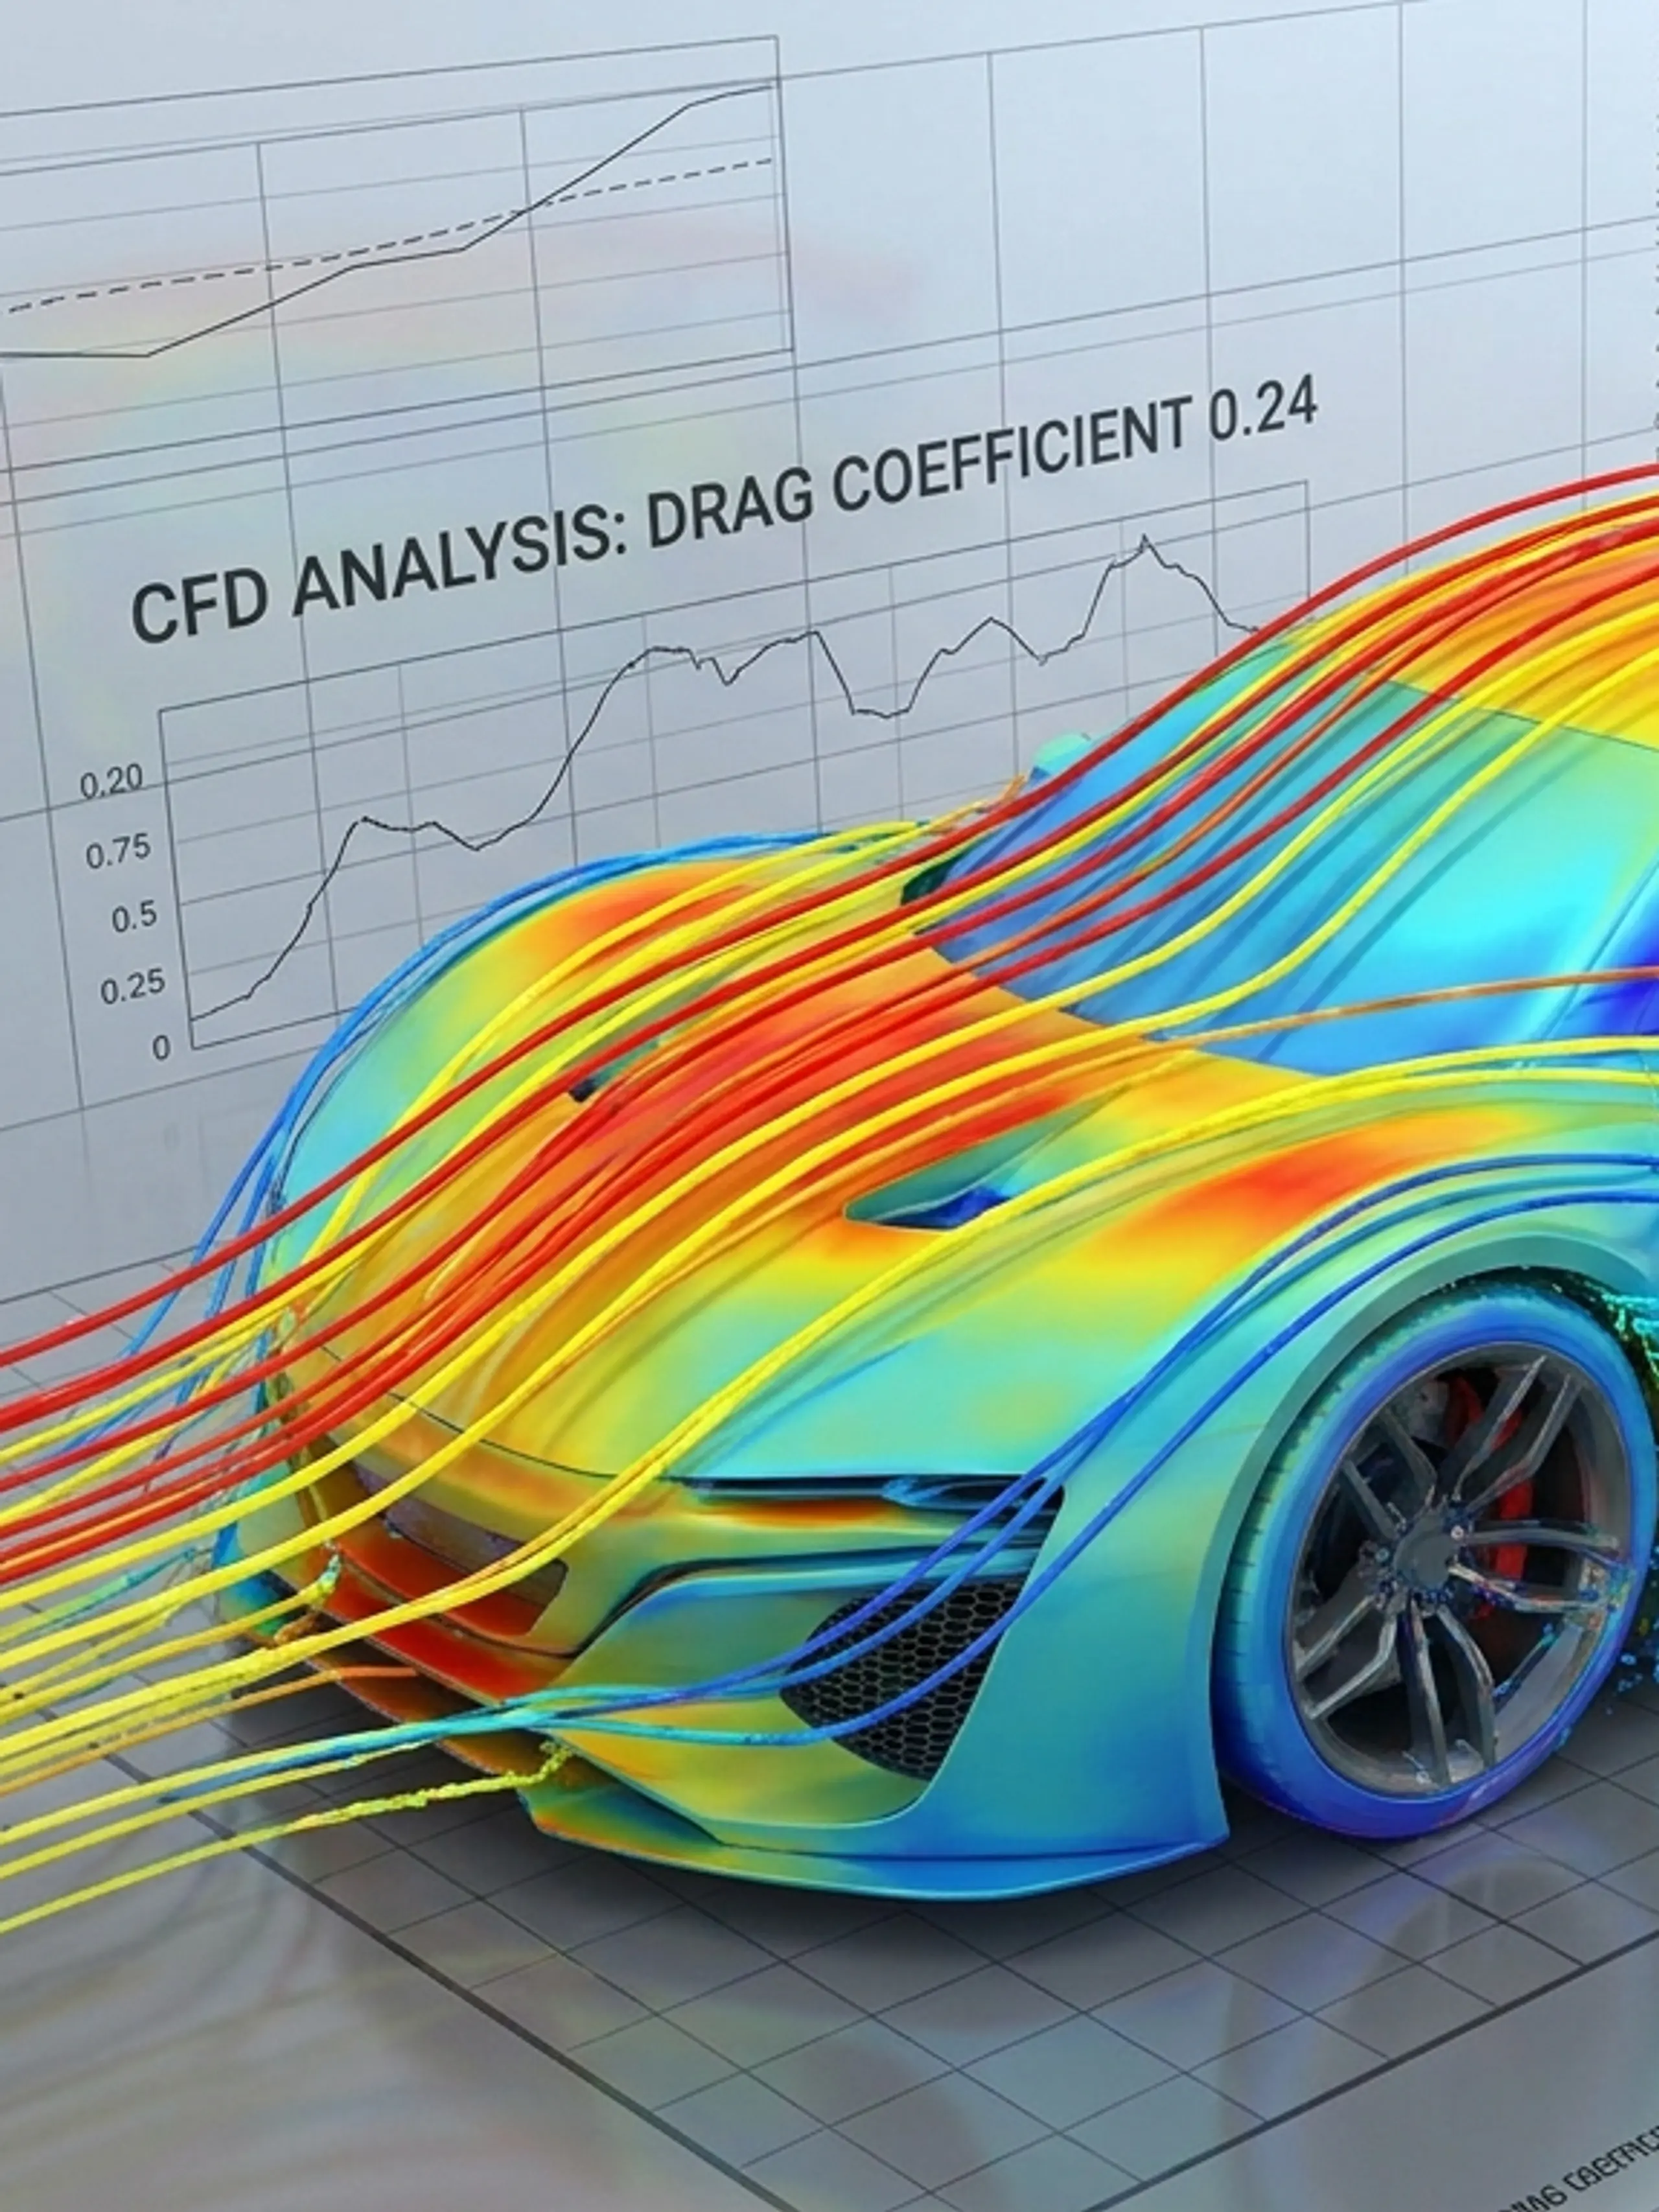
Legacy storage idles expensive GPU farms during vehicle simulation and forces design re-spins. NeuralMesh absorbs concurrent CFD and FEA loads so design cycles keep moving.
Robotics
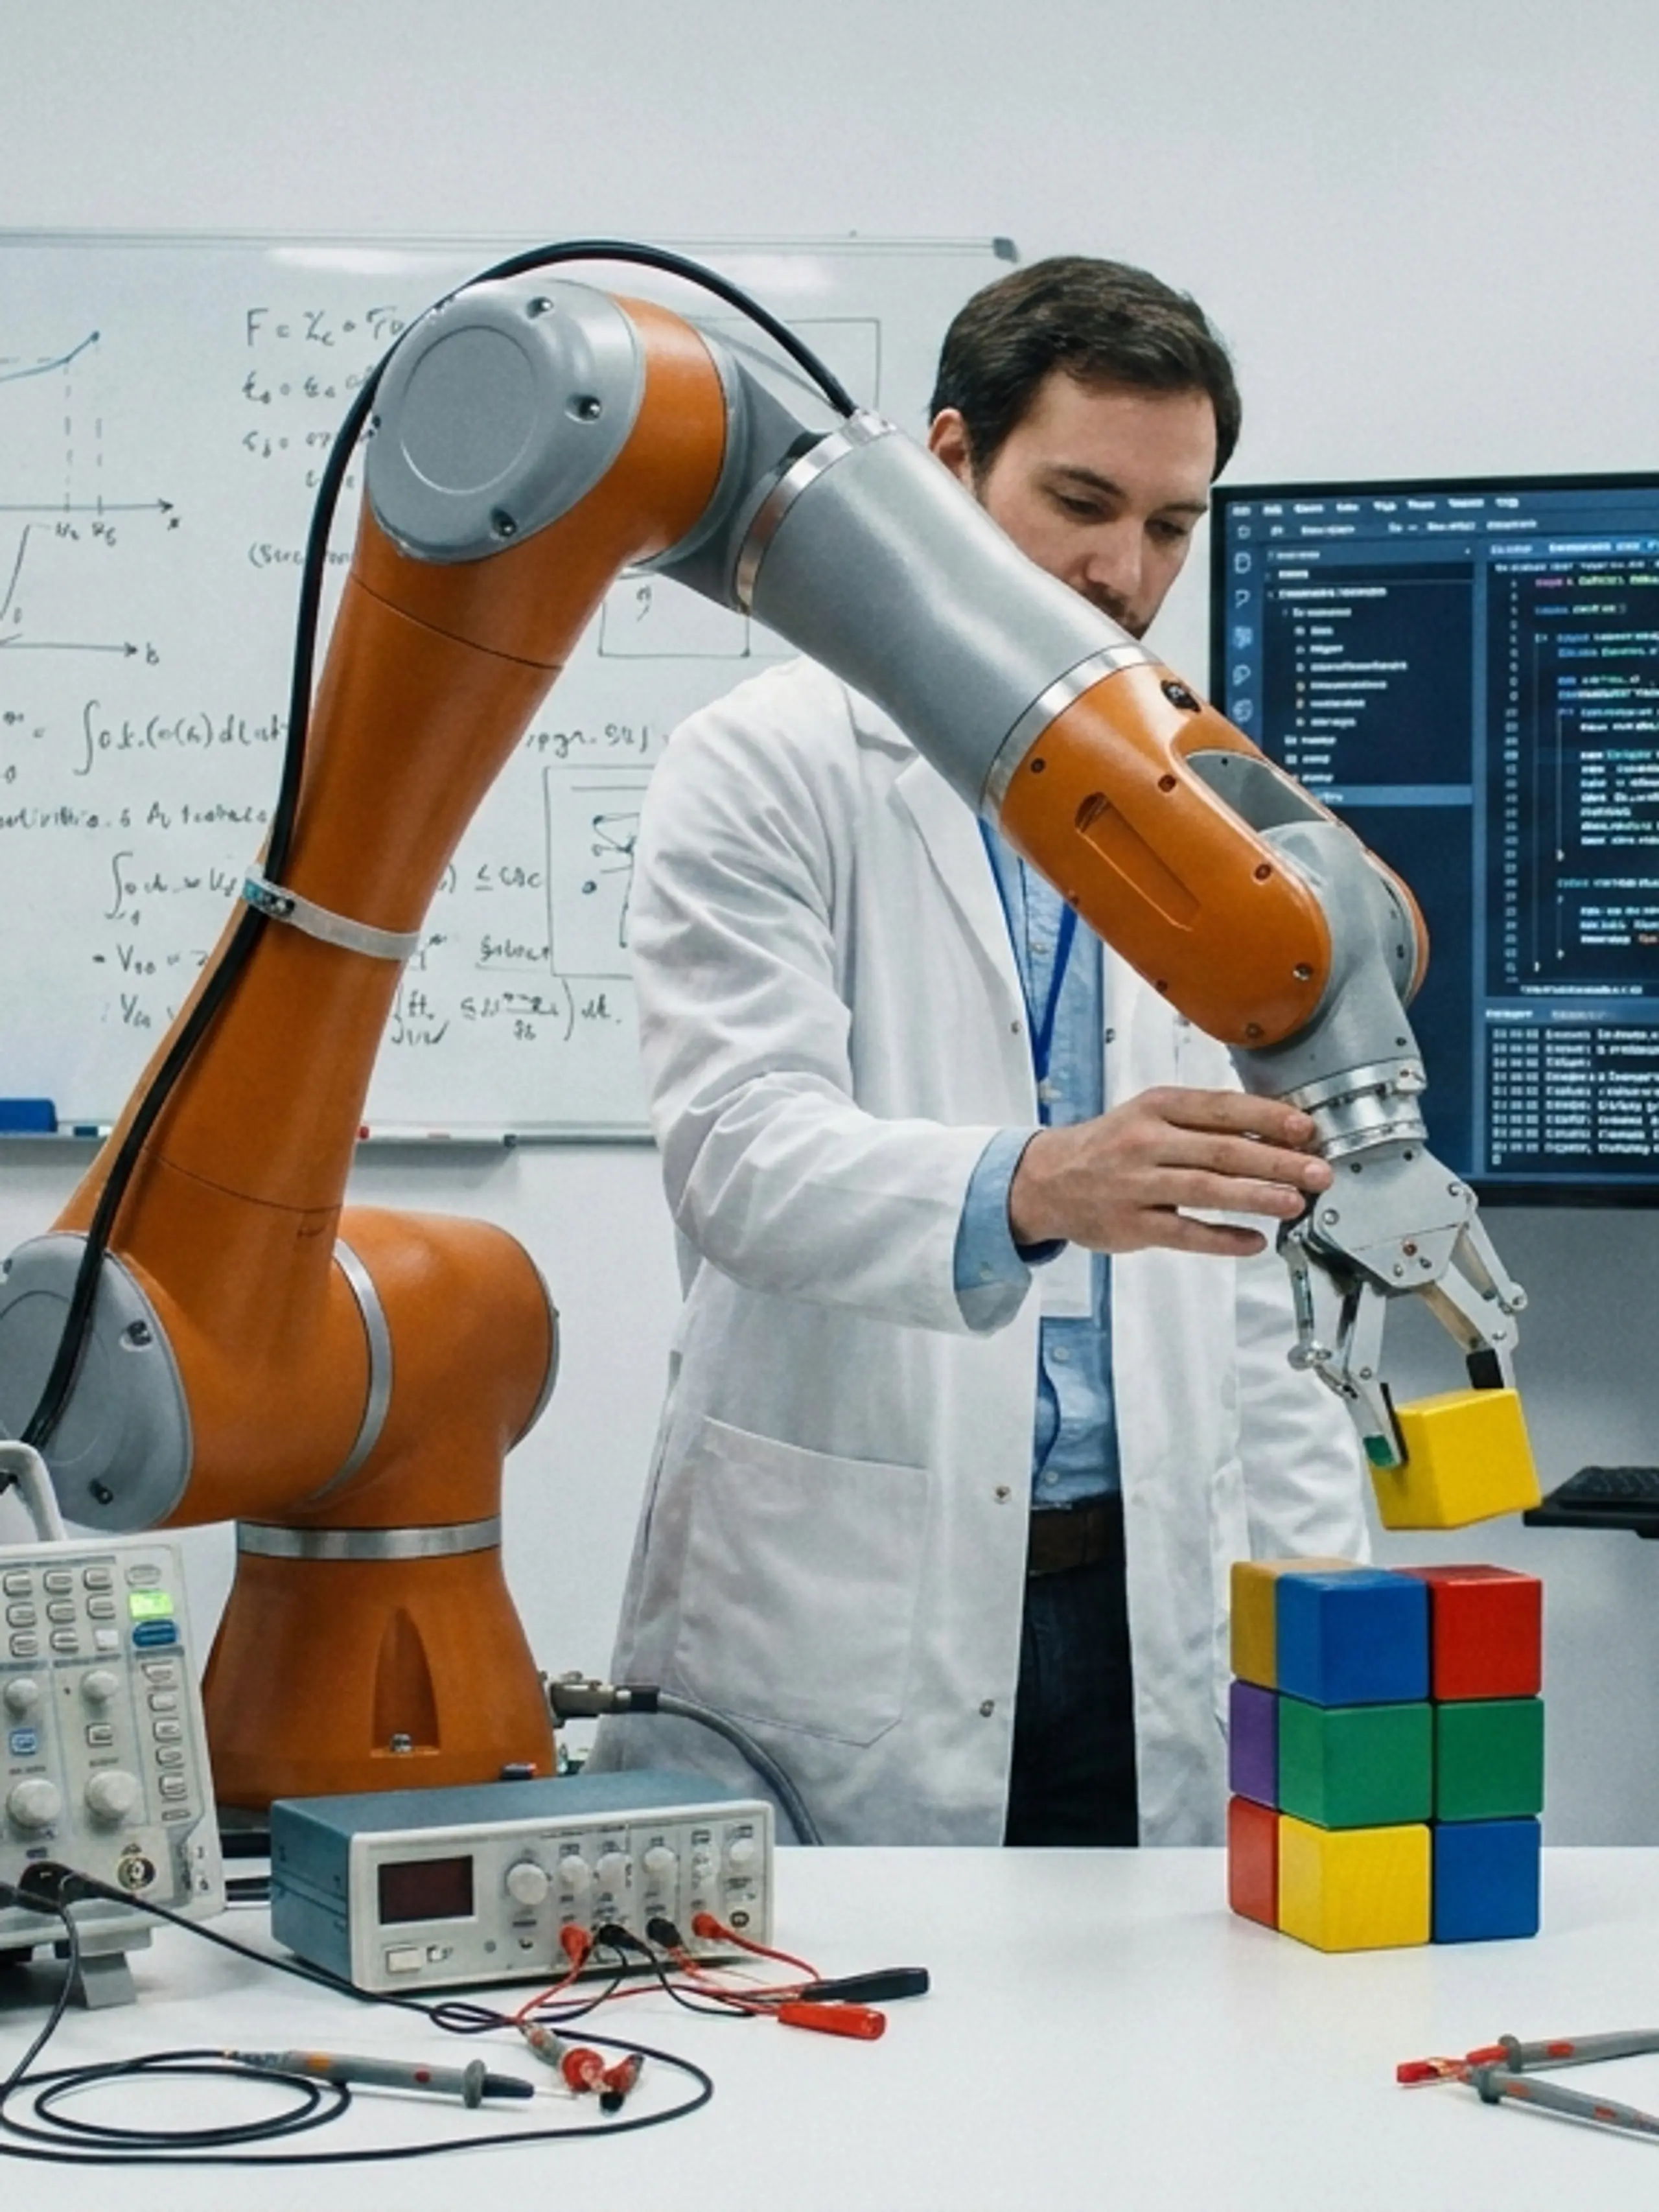
Robotics training pulls LiDAR, camera, and telemetry streams at once, each checkpointing constantly. NeuralMesh closes the edge-to-data-center loop without manual staging.
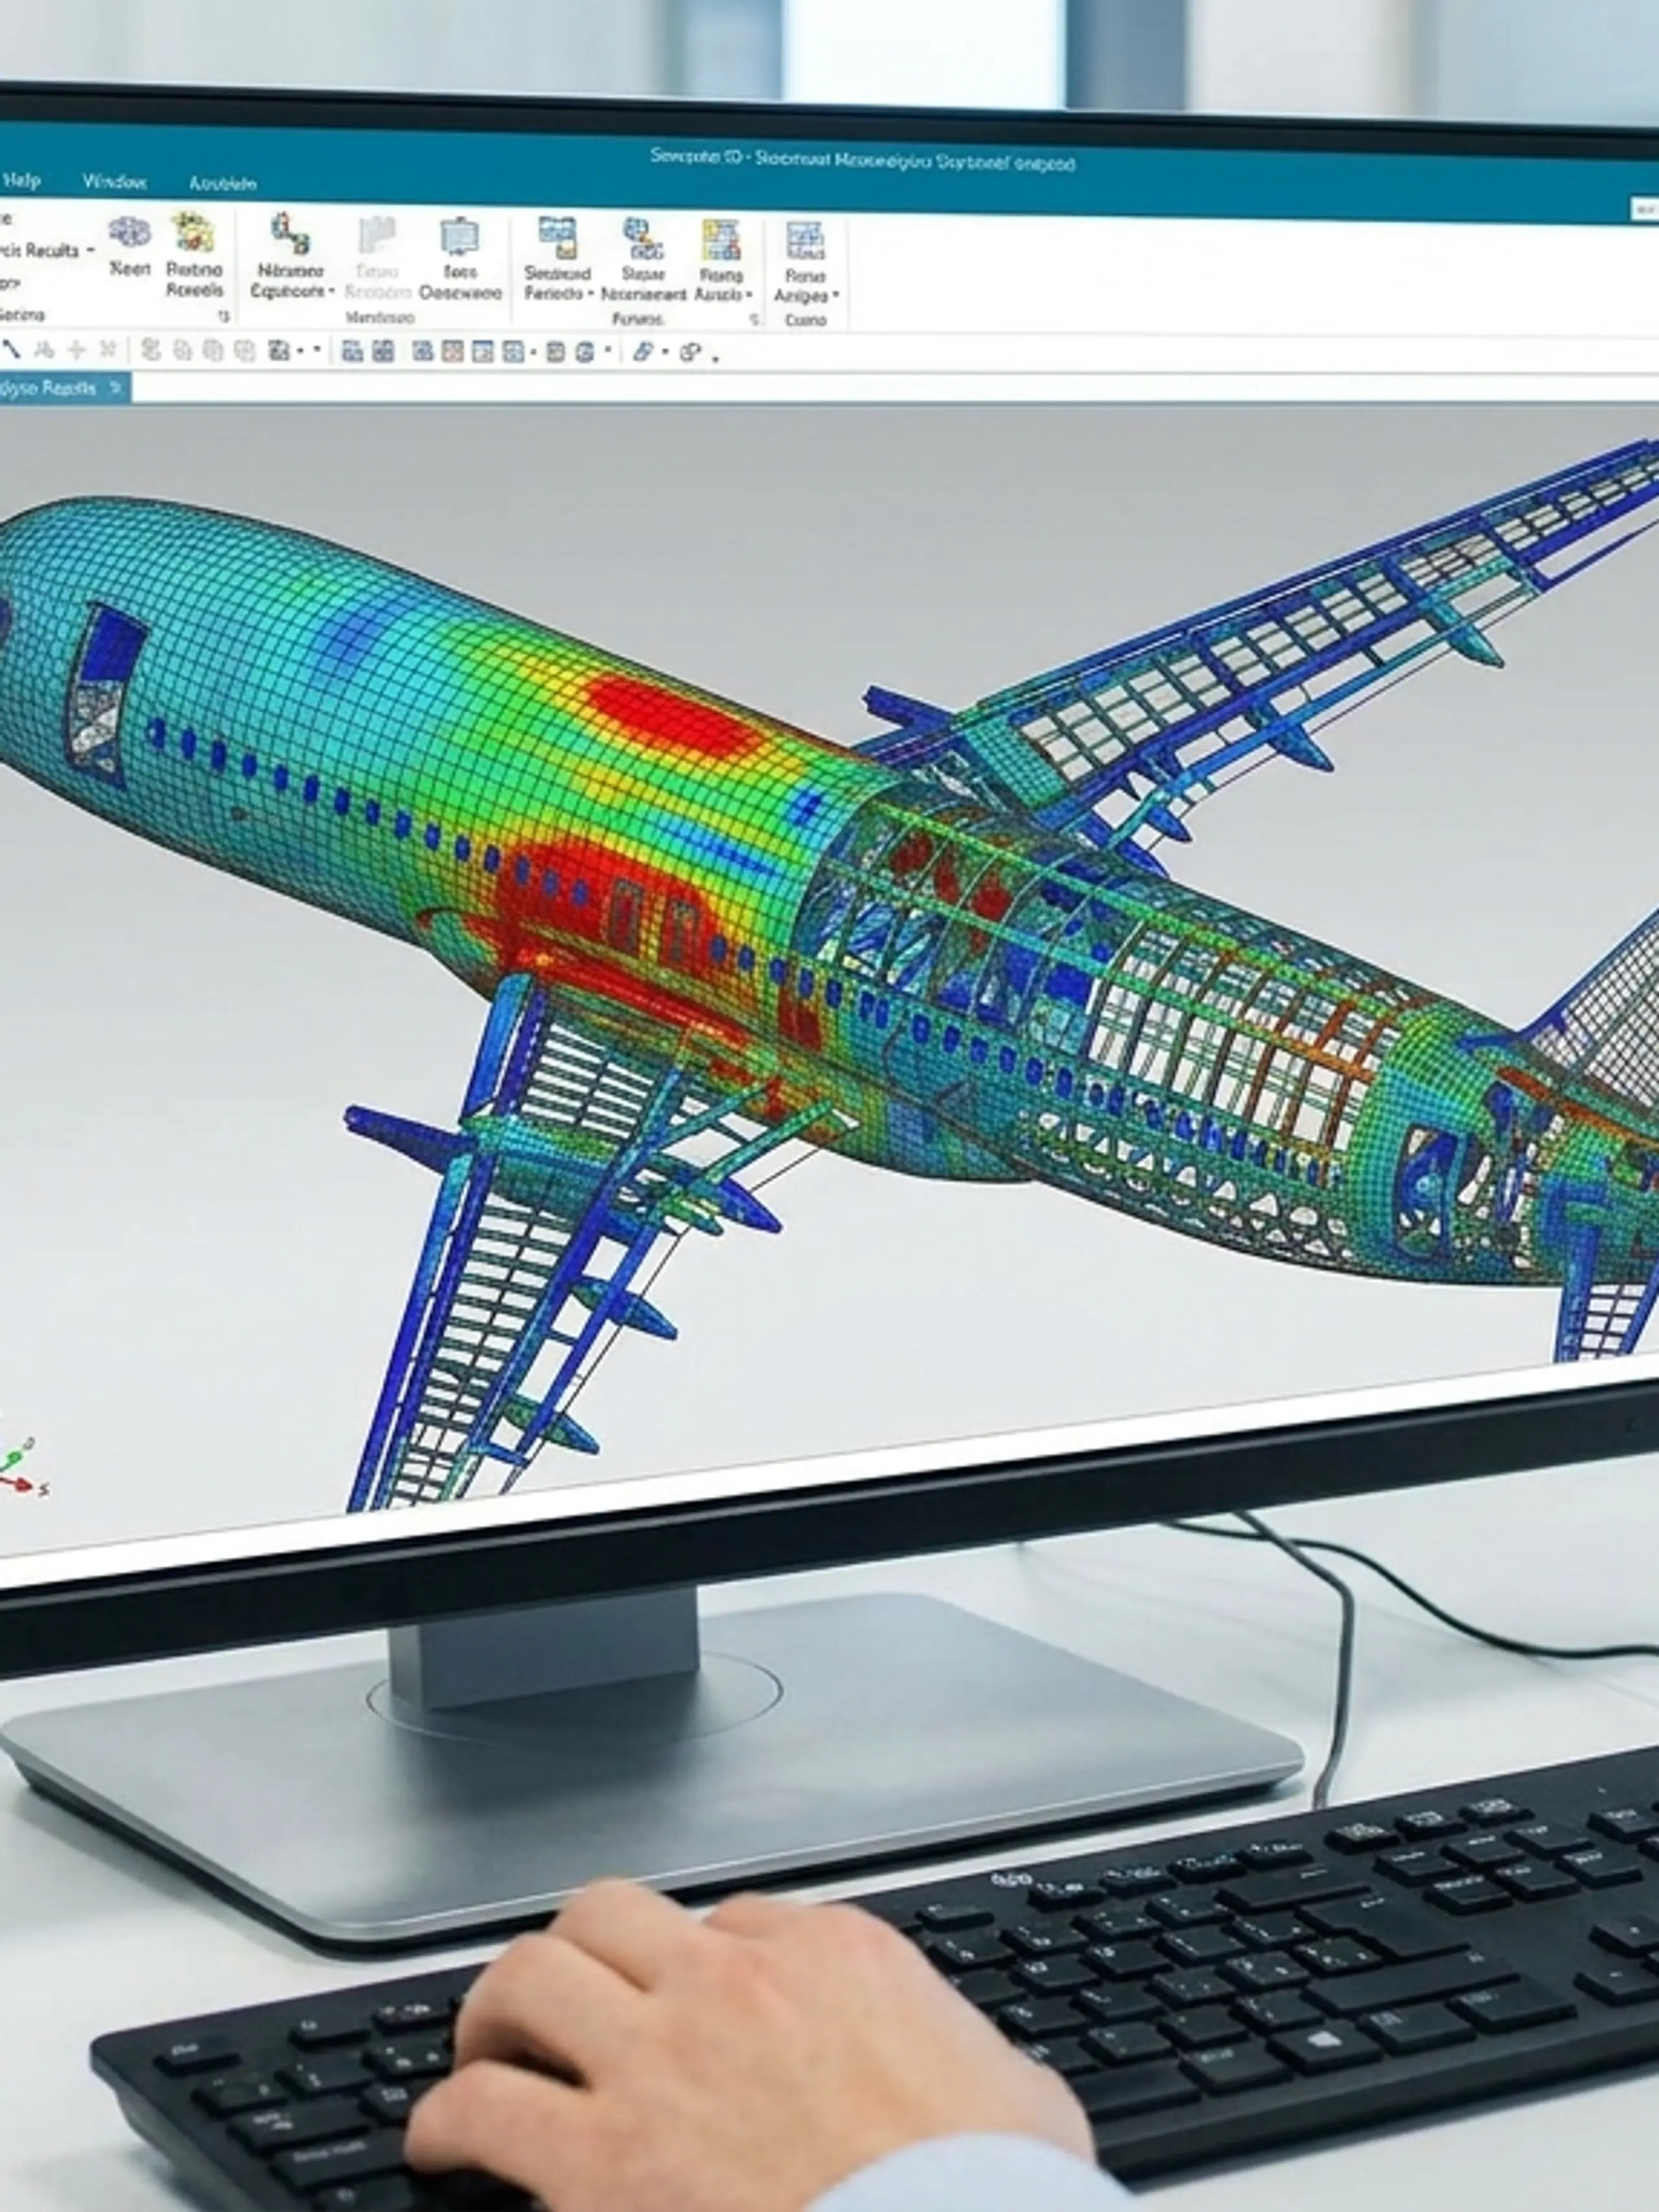
Aerospace and Defense
A&D simulation needs massive parallelism and low-latency writes to avoid lost jobs. NeuralMesh ingests sensor and IoT data in real time so intelligence reaches decisions faster.
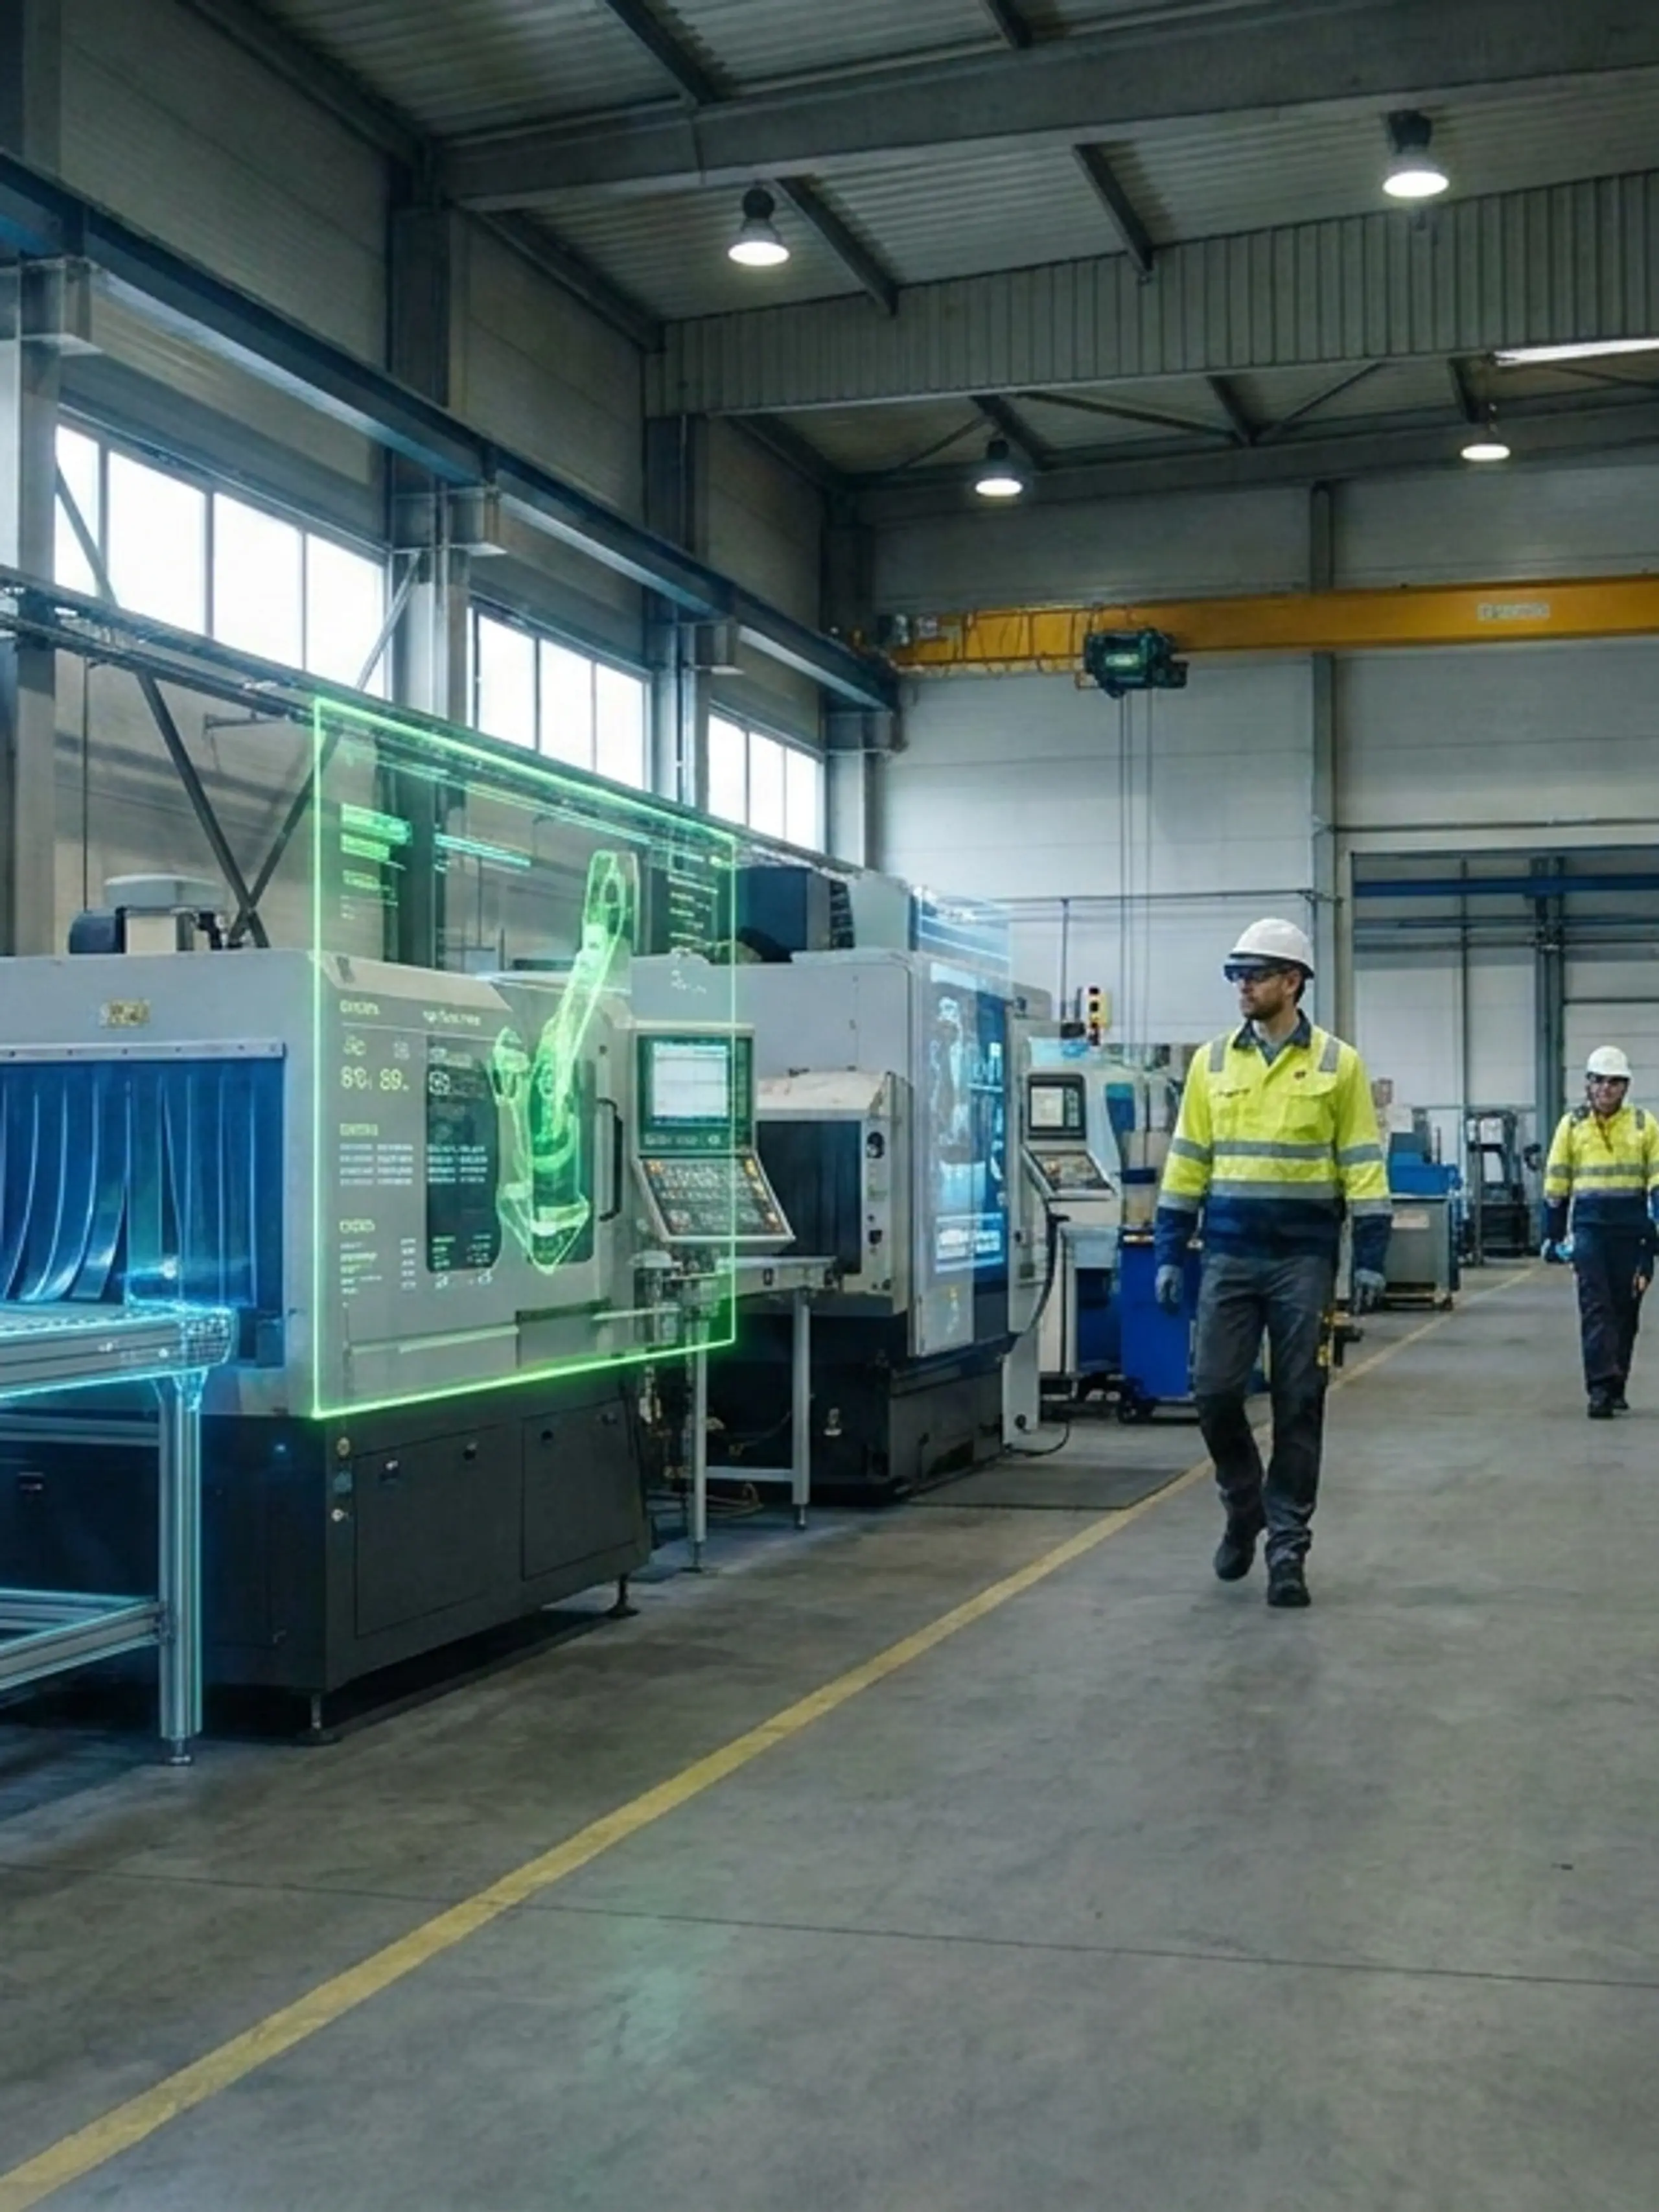
Industrial Manufacturing
Digital twins and IoT telemetry starve compute and stall production cycles. NeuralMesh delivers ultra-low latency across concurrent engineering workloads so GPUs stay saturated.
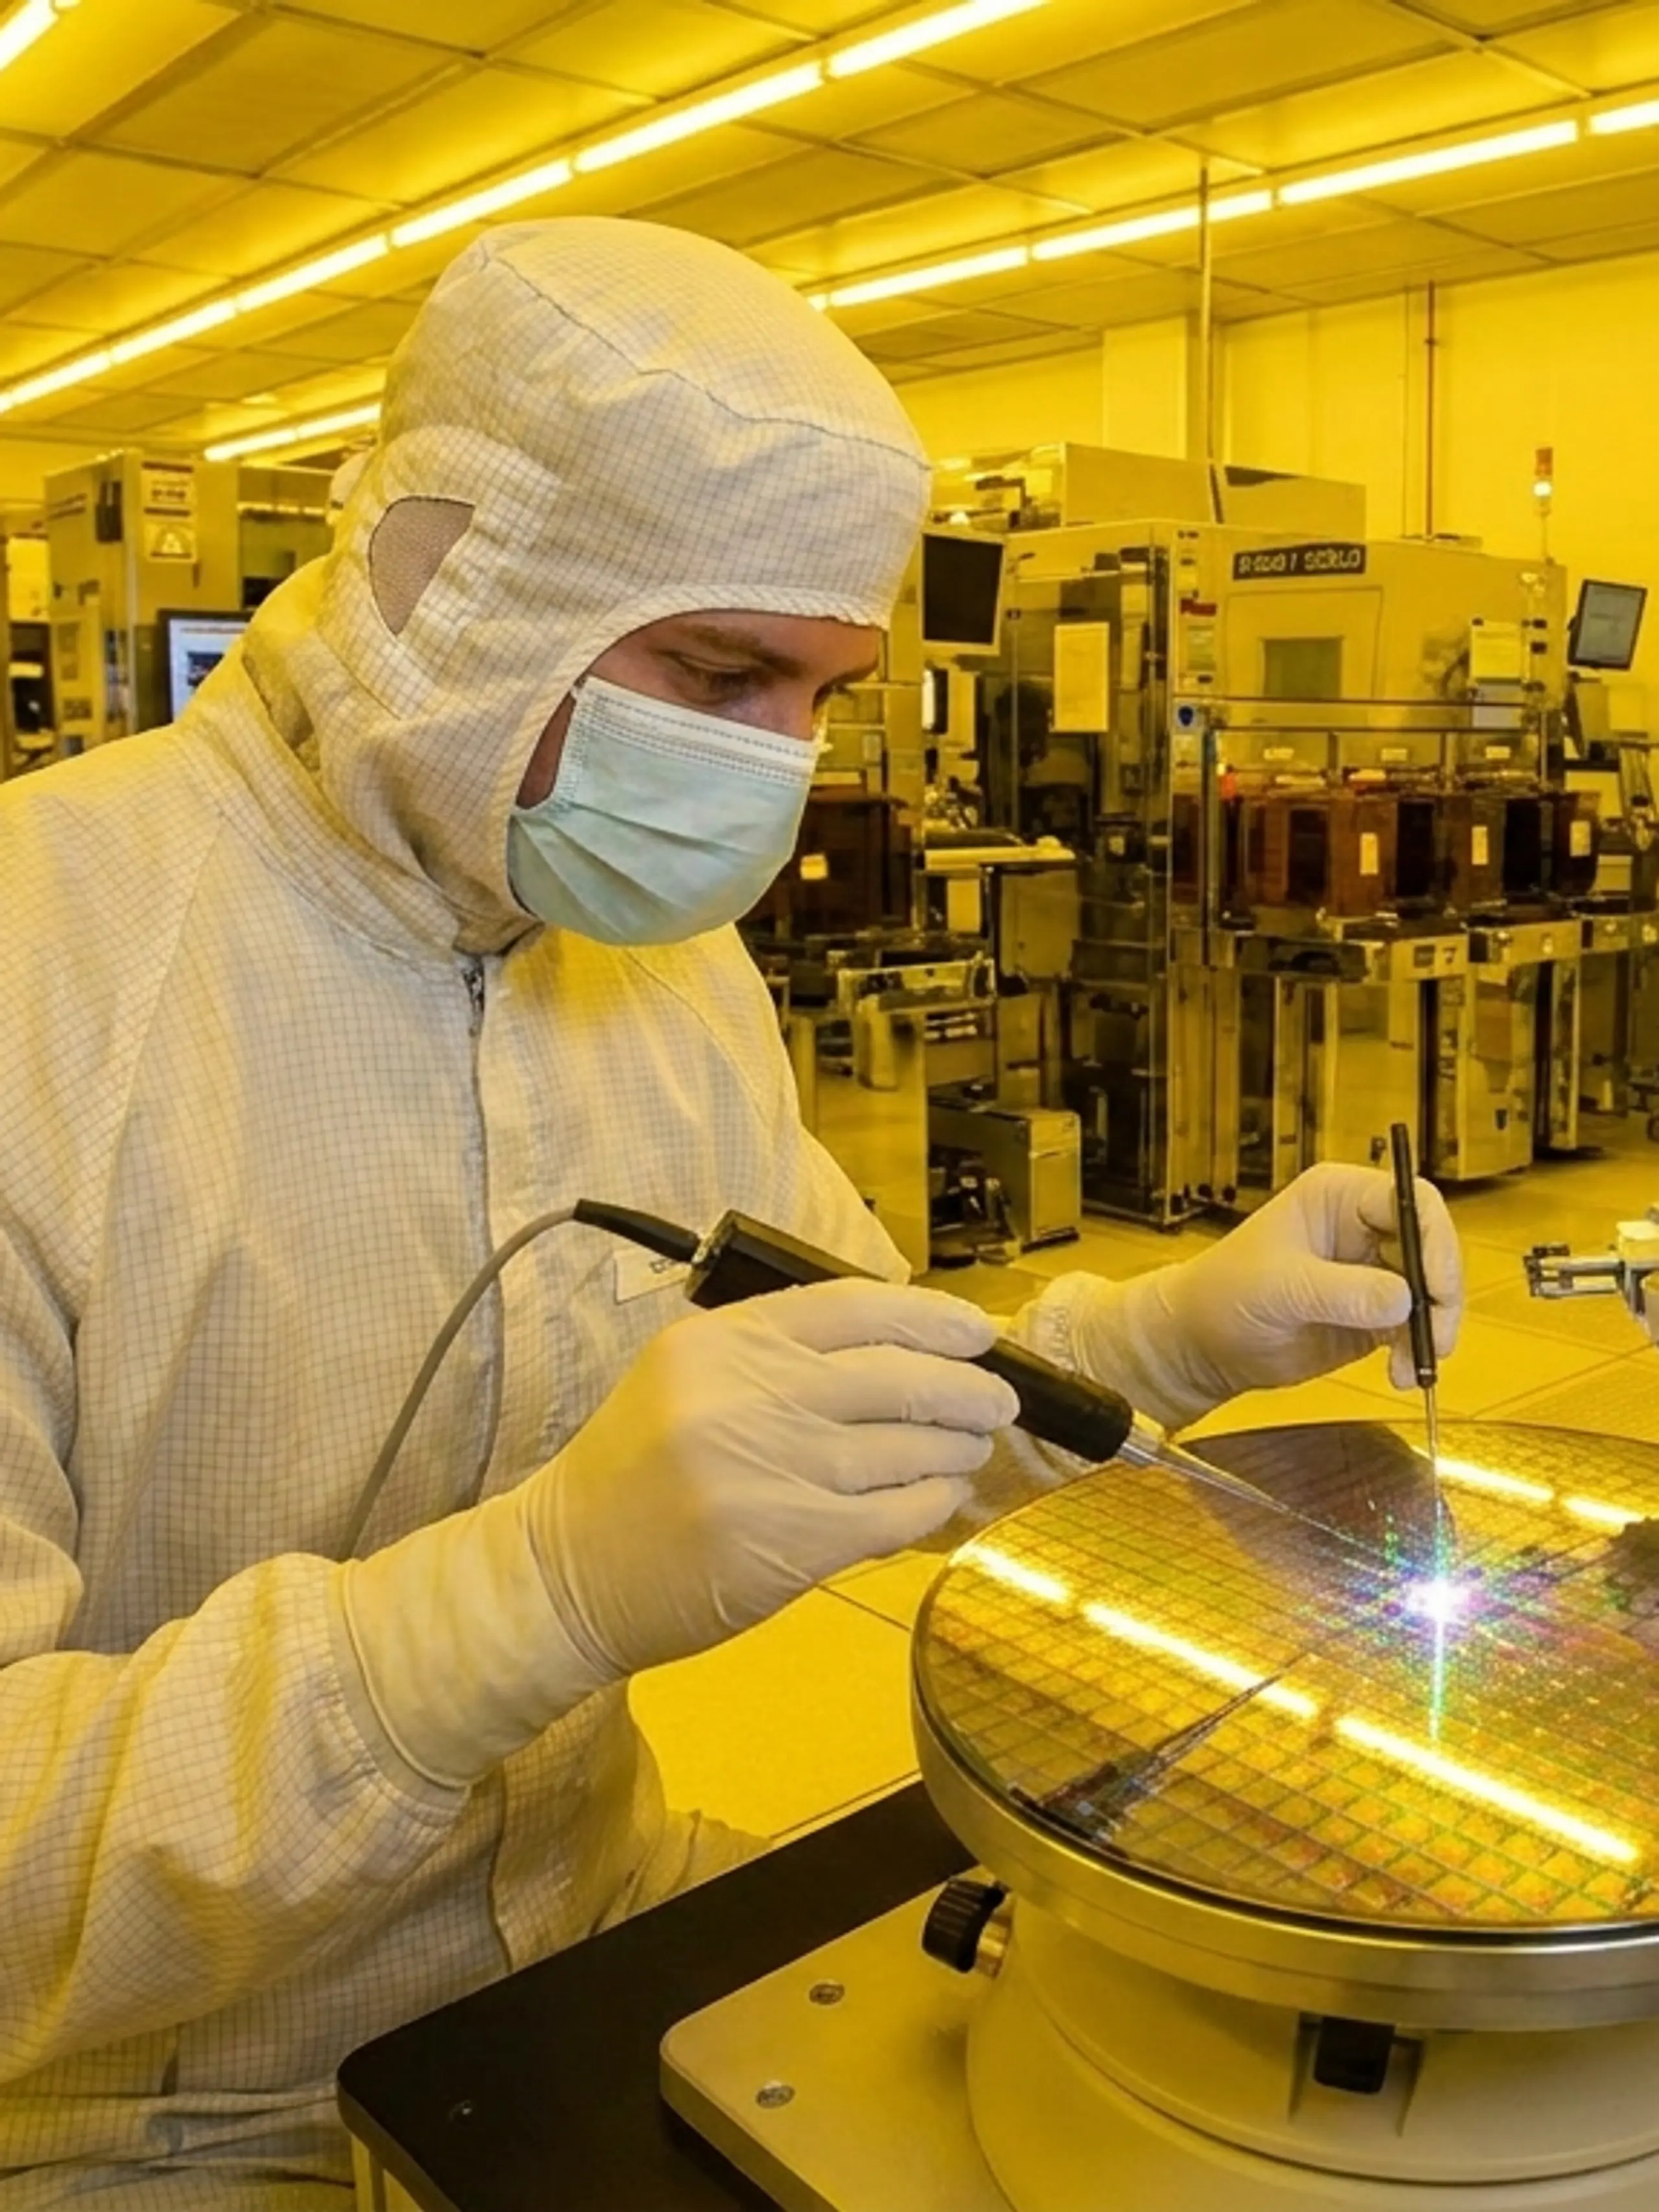
Semiconductor Fabrication
Fab workflows write terabytes per time step across hundreds of concurrent simulations. NeuralMesh delivers the throughput and checkpoint reliability that keep tapeouts on schedule.
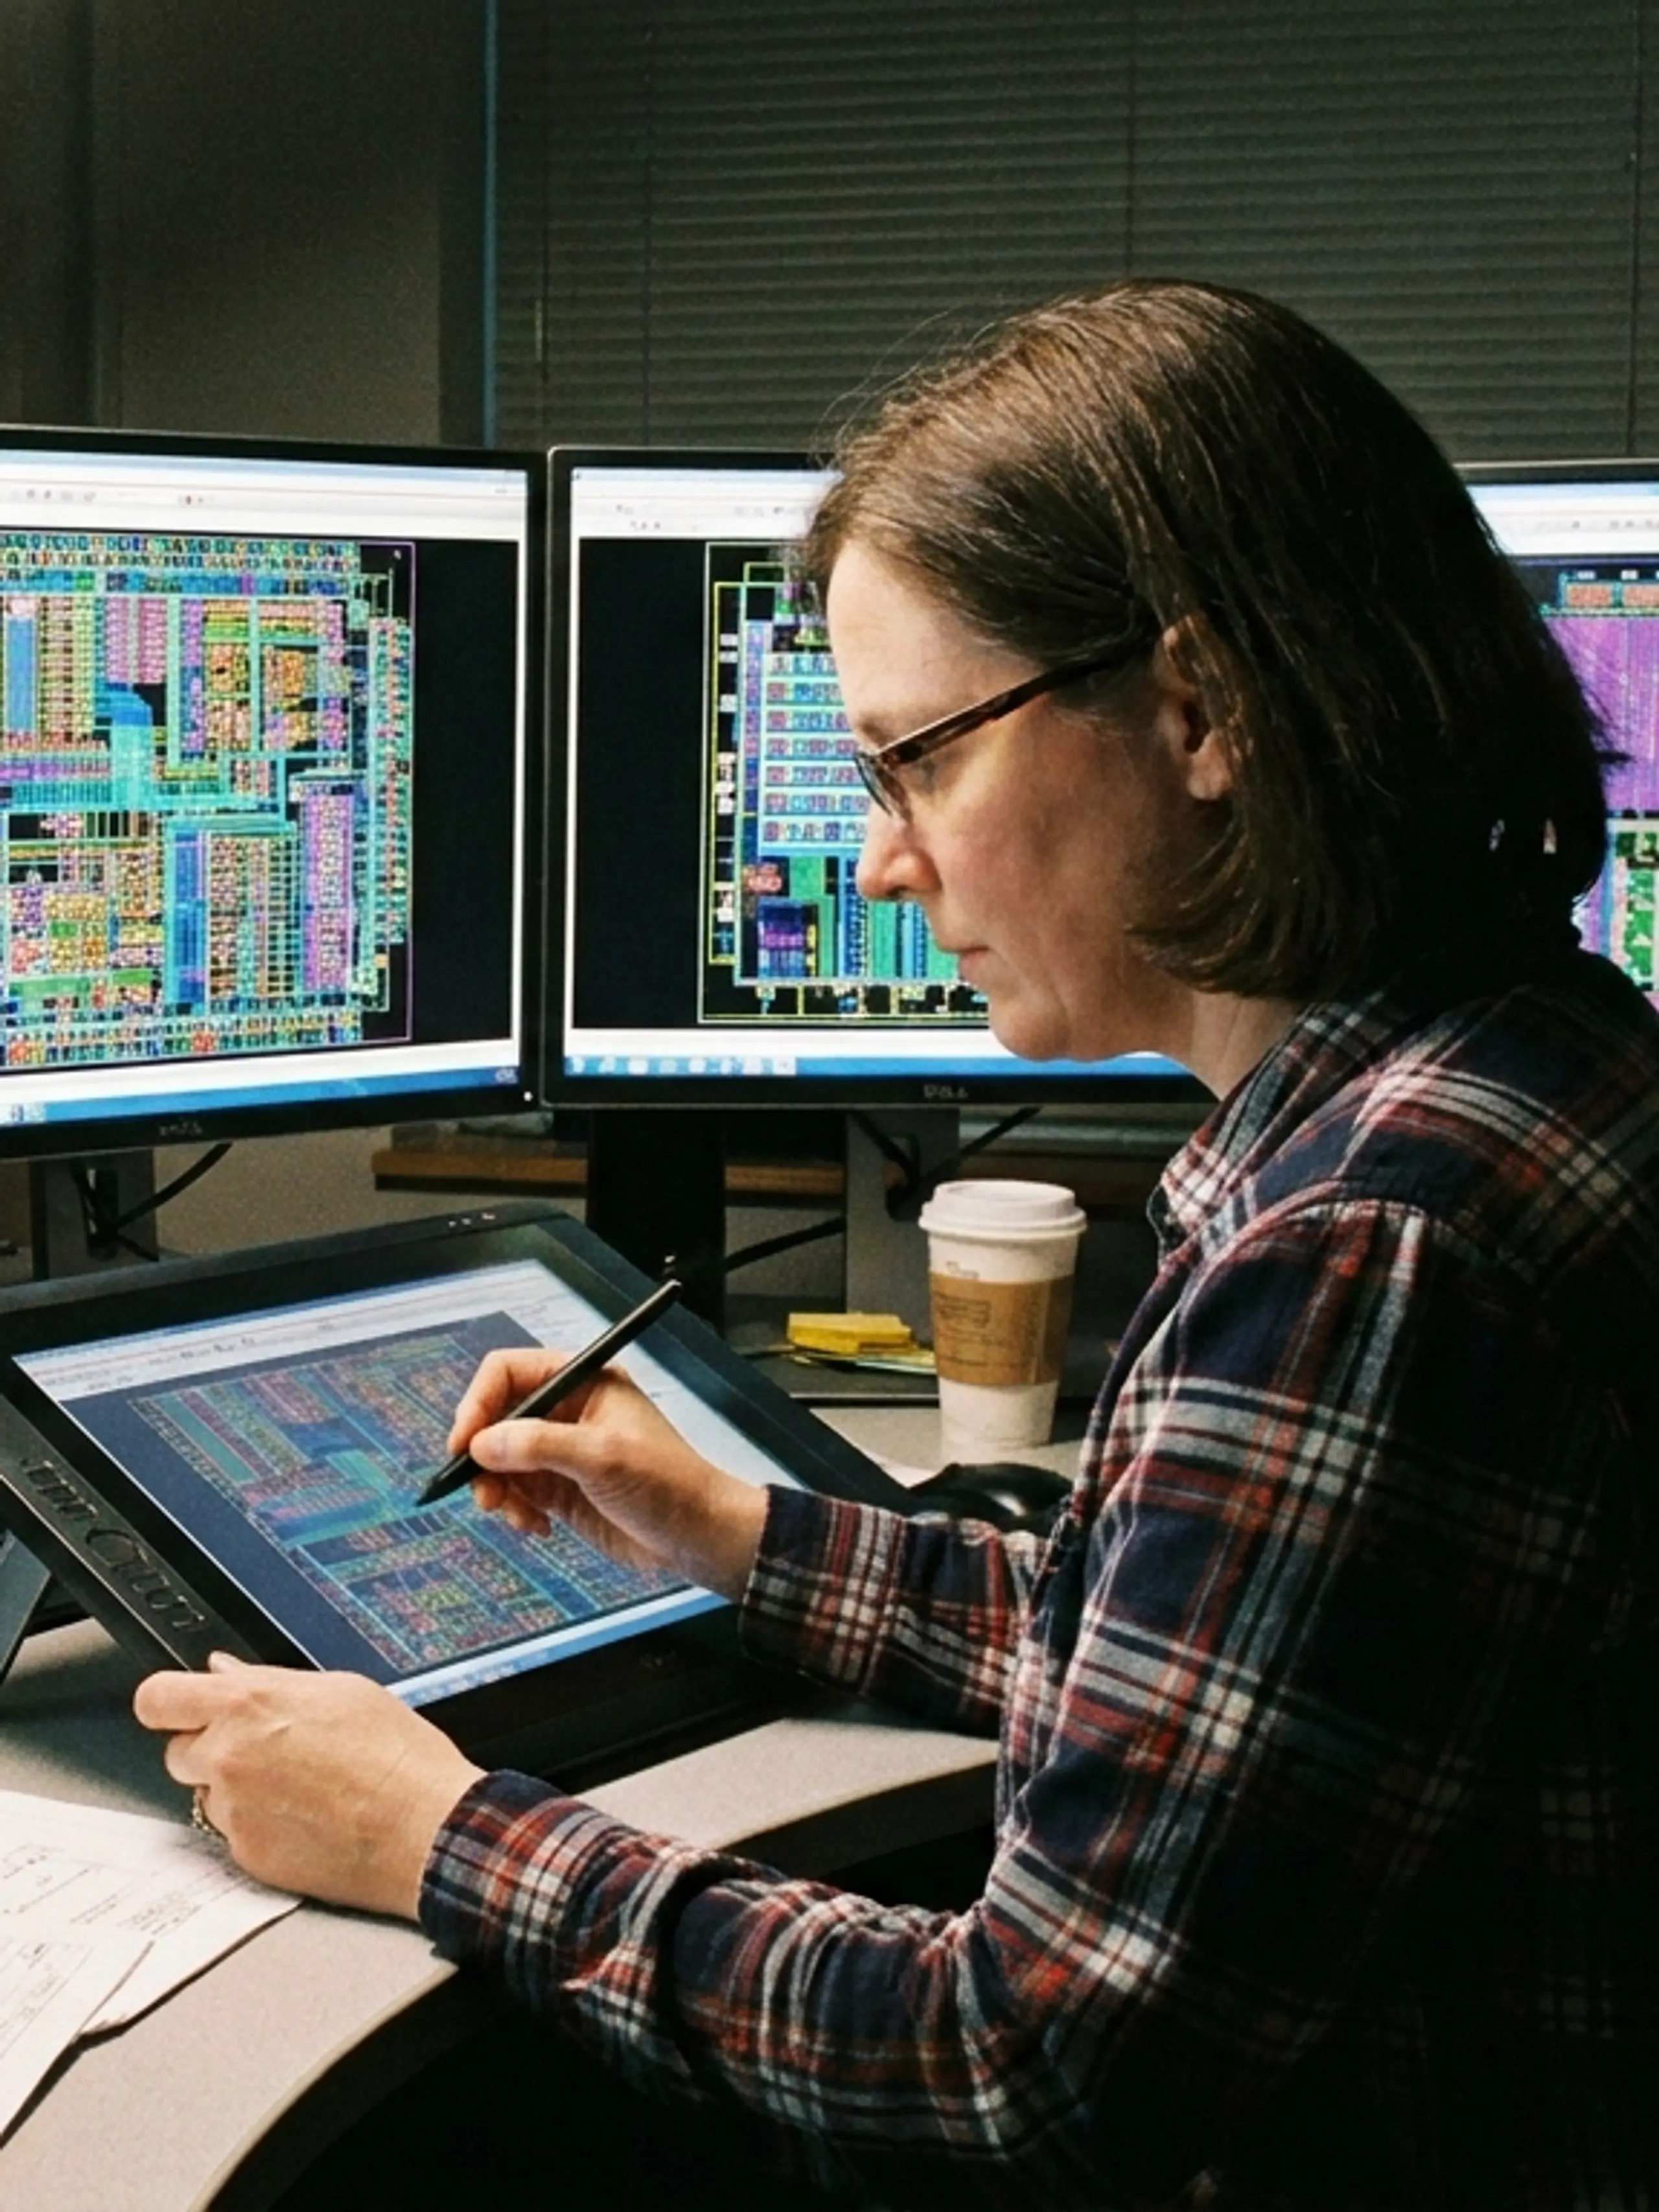
Chip Design and EDA
Hundreds of concurrent EDA jobs share one massive design database, and metadata performance decides whether tool farms run or stall. NeuralMesh handles the mixed load.
NeuralMesh Offers a Proven Solution for Manufacturing Teams
Results reported by individual manufacturing and robotics customers. Figures vary by workload and configuration.
0%
Faster model checkpoint times
Physical Intelligence measured checkpoint operations delaying training by 15%. Moving to NeuralMesh recovered that time.
0%
Reduction in data infrastructure costs
Physical Intelligence turned unused local NVMe across its GPU servers into shared high-performance storage.
0x
More bandwidth than NFS
WEKA’s storage scalability and ability to grow the infrastructure without losing performance
0B
Parameter multimodal model
Choosing WEKA in a public cloud environment was the optimal decision for maximizing performance, and it really made a difference in accelerating our multi-node AI training.
WHY WEKA
Get More Out of the GPUs You Already Bought
Manufacturing runs on concurrency, not raw capacity. Legacy NAS was built for files at rest, and adding shelves to it just adds copies, racks, and idle compute.
Reduce Failure-Driven Overhead Expenses
Maintain multi-tenant performance at sub-millisecond latency so quality inspection results reach the factory floor while the line is still running.
1 / 6
Reduce Failure-Driven Overhead Expenses
Maintain multi-tenant performance at sub-millisecond latency so quality inspection results reach the factory floor while the line is still running.
Streamline End-to-End AI Workflows
Host manufacturing workflows in a single, trusted infrastructure to dynamically support workflows from data ingestion, to training, to model deployment and inference.
Evolve Beyond Legacy HPC Infrastructure
Scale to exabytes without architectural limitations or performance degradation to transition smoothly from traditional HPC architectures to AI-ready data pipelines.
1 / 2

“Choosing WEKA in a public cloud environment was the optimal decision for maximizing performance, and it really made a difference in accelerating our multi-node AI training.”

Never Starve Your Engineering Pipelines
Feed massive telemetry streams and simulations in real time. NeuralMesh eliminates data starvation so your GPU clusters never stall.
Frequently Asked Questions
Did this page meet your expectations?