Work in Full Resolution. Skip the Proxy Workflow.
WEKA NeuralMesh holds 8K playback, VFX renders, and model training in one namespace, with no proxies and no copies.
Studios, Venues, and GenAI Labs Run On NeuralMesh


USE CASES
One Namespace From First Frame to Final Render
Media workflows fight over the same thing: a storage layer that can serve 8K sequential reads and millions of tiny metadata operations at the same time, for hundreds of artists at once. WEKA® NeuralMesh™ does both without tuning or proxies.
Generative AI
Multimodal training reads video, audio, and text at once. NeuralMesh bypasses the kernel and DRAM to keep training fed, then serves inference to thousands of concurrent users.
High-Quality Post-Production
Global post needs huge concurrency across millions of small files, plus CPU and GPU on demand. NeuralMesh removes proxy workflows and the pre-fetch guesswork underneath them.
Color Correction and VFX Rendering
Uncompressed 4K and 8K grading needs low-latency playback; frame rendering needs high IOPS. NeuralMesh serves both from one namespace, so nobody clears the SAN before a session.
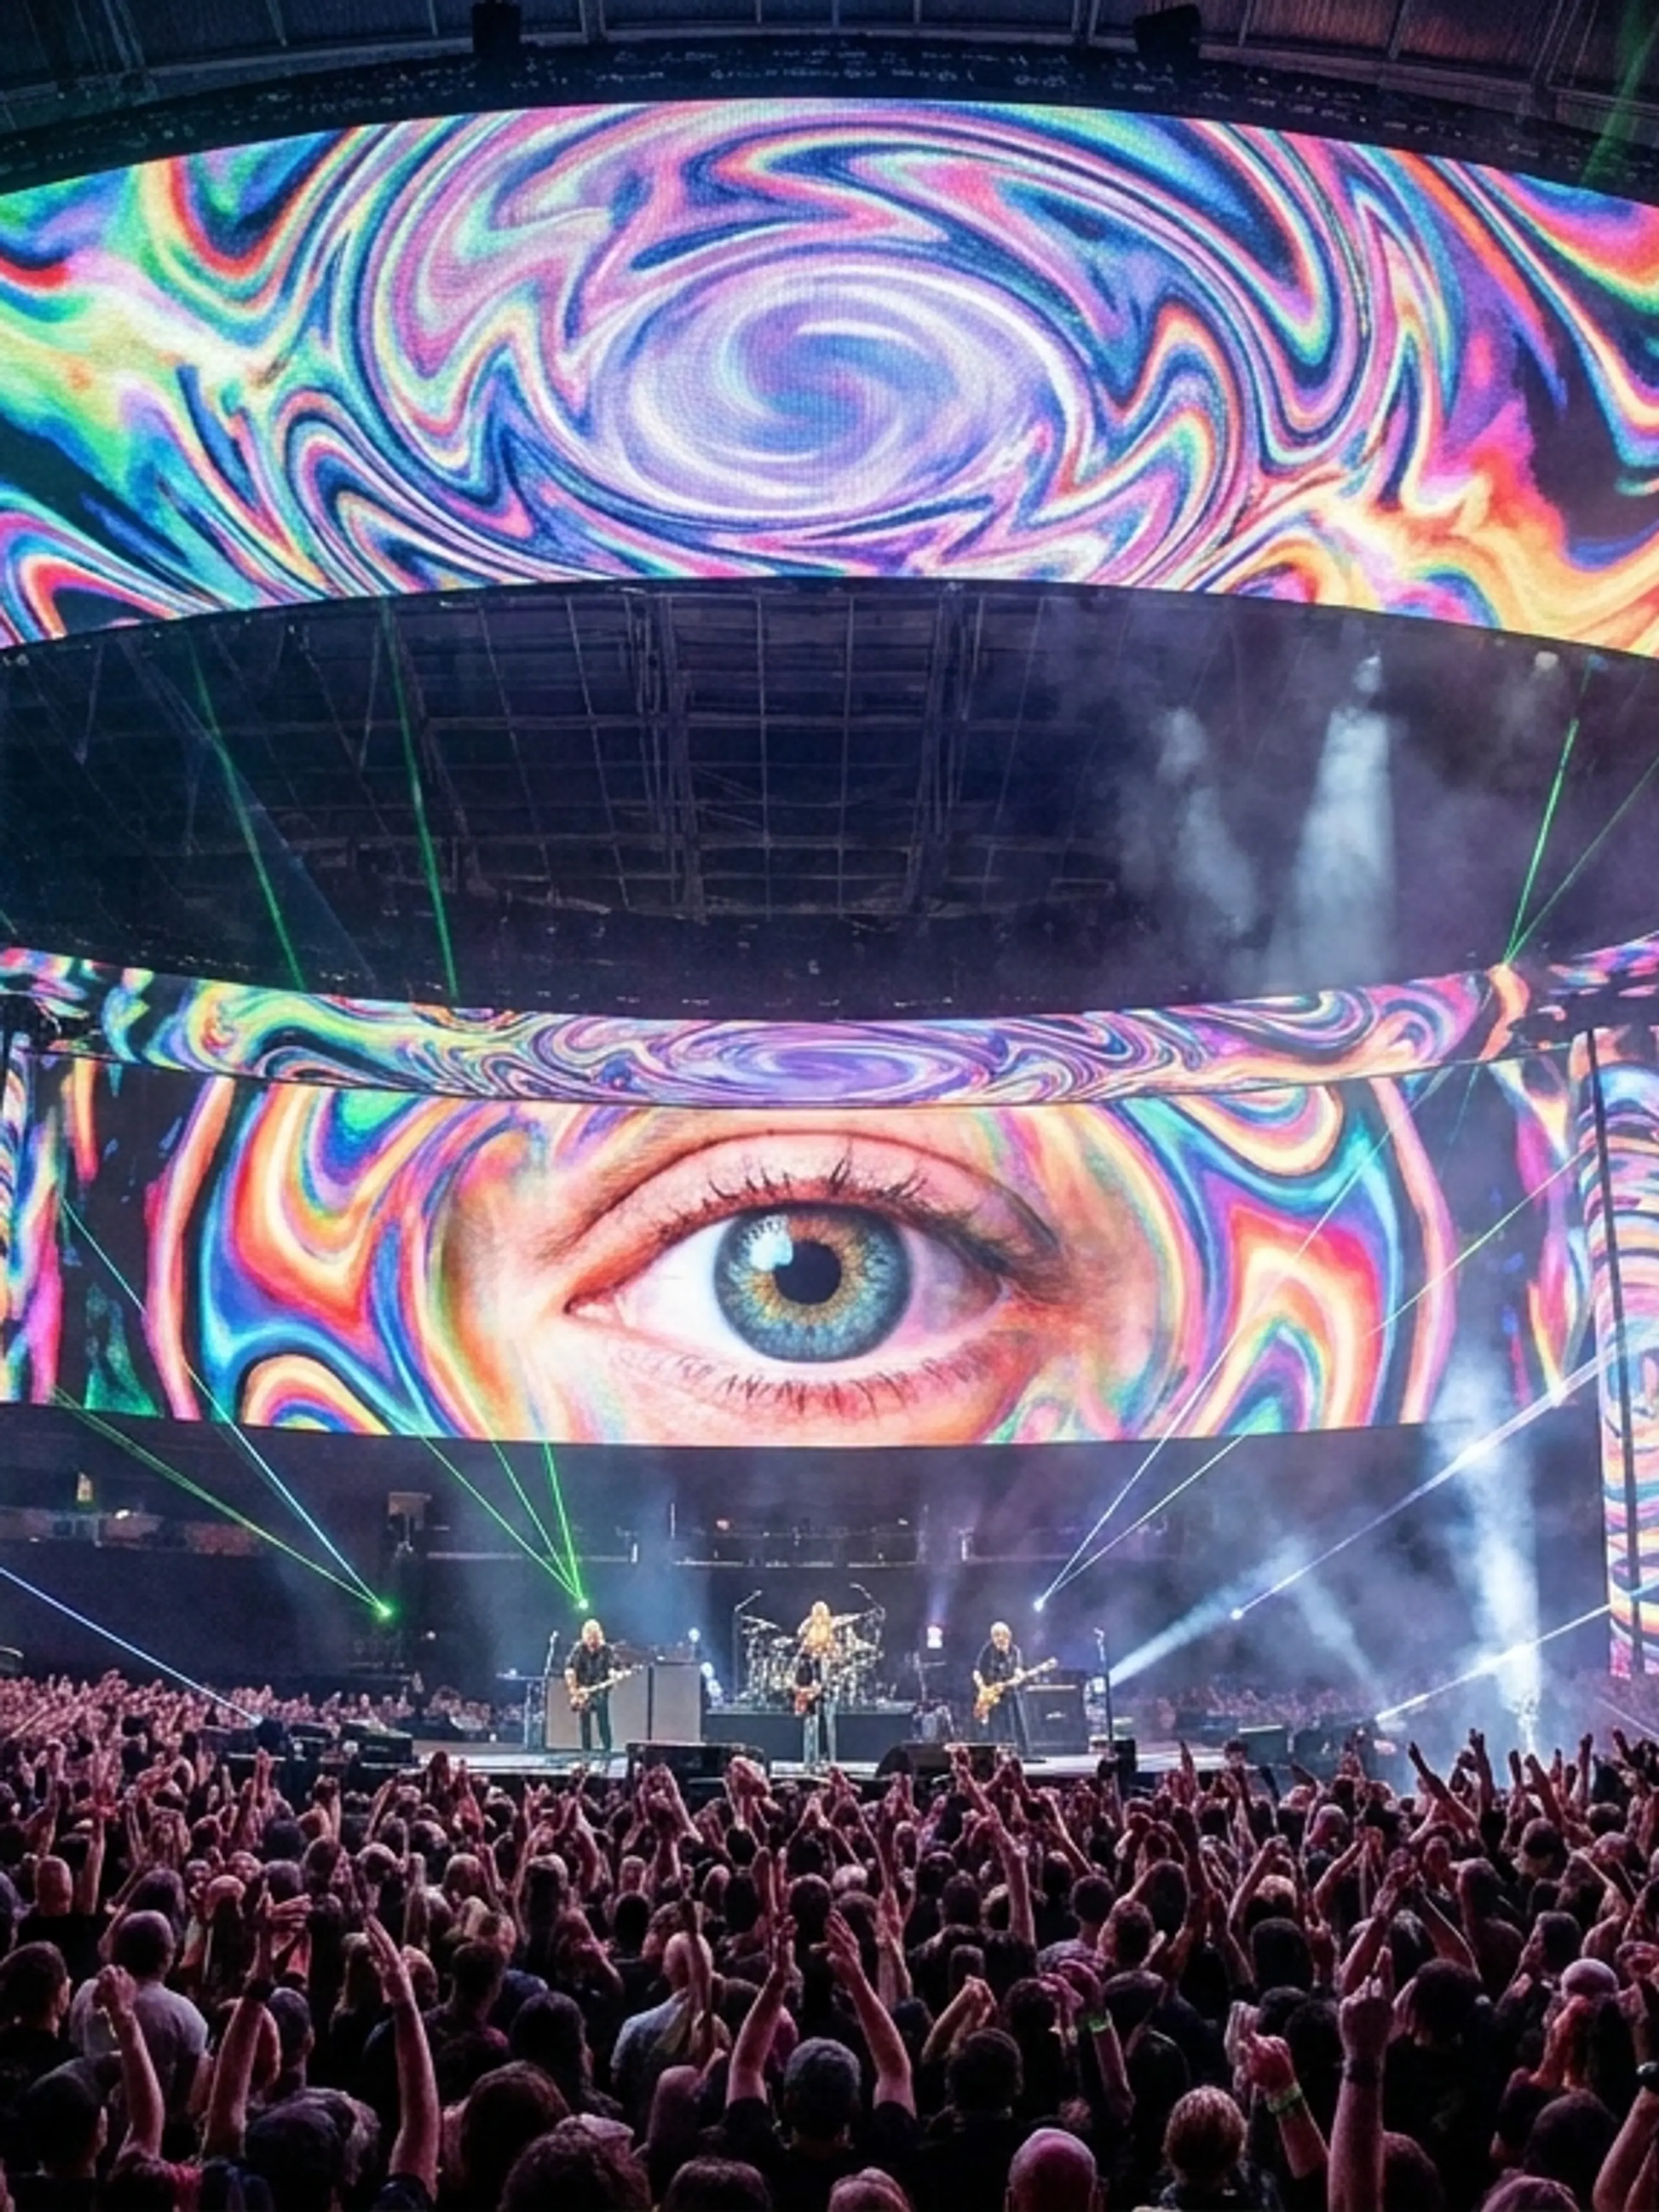
Immersive Live Entertainment
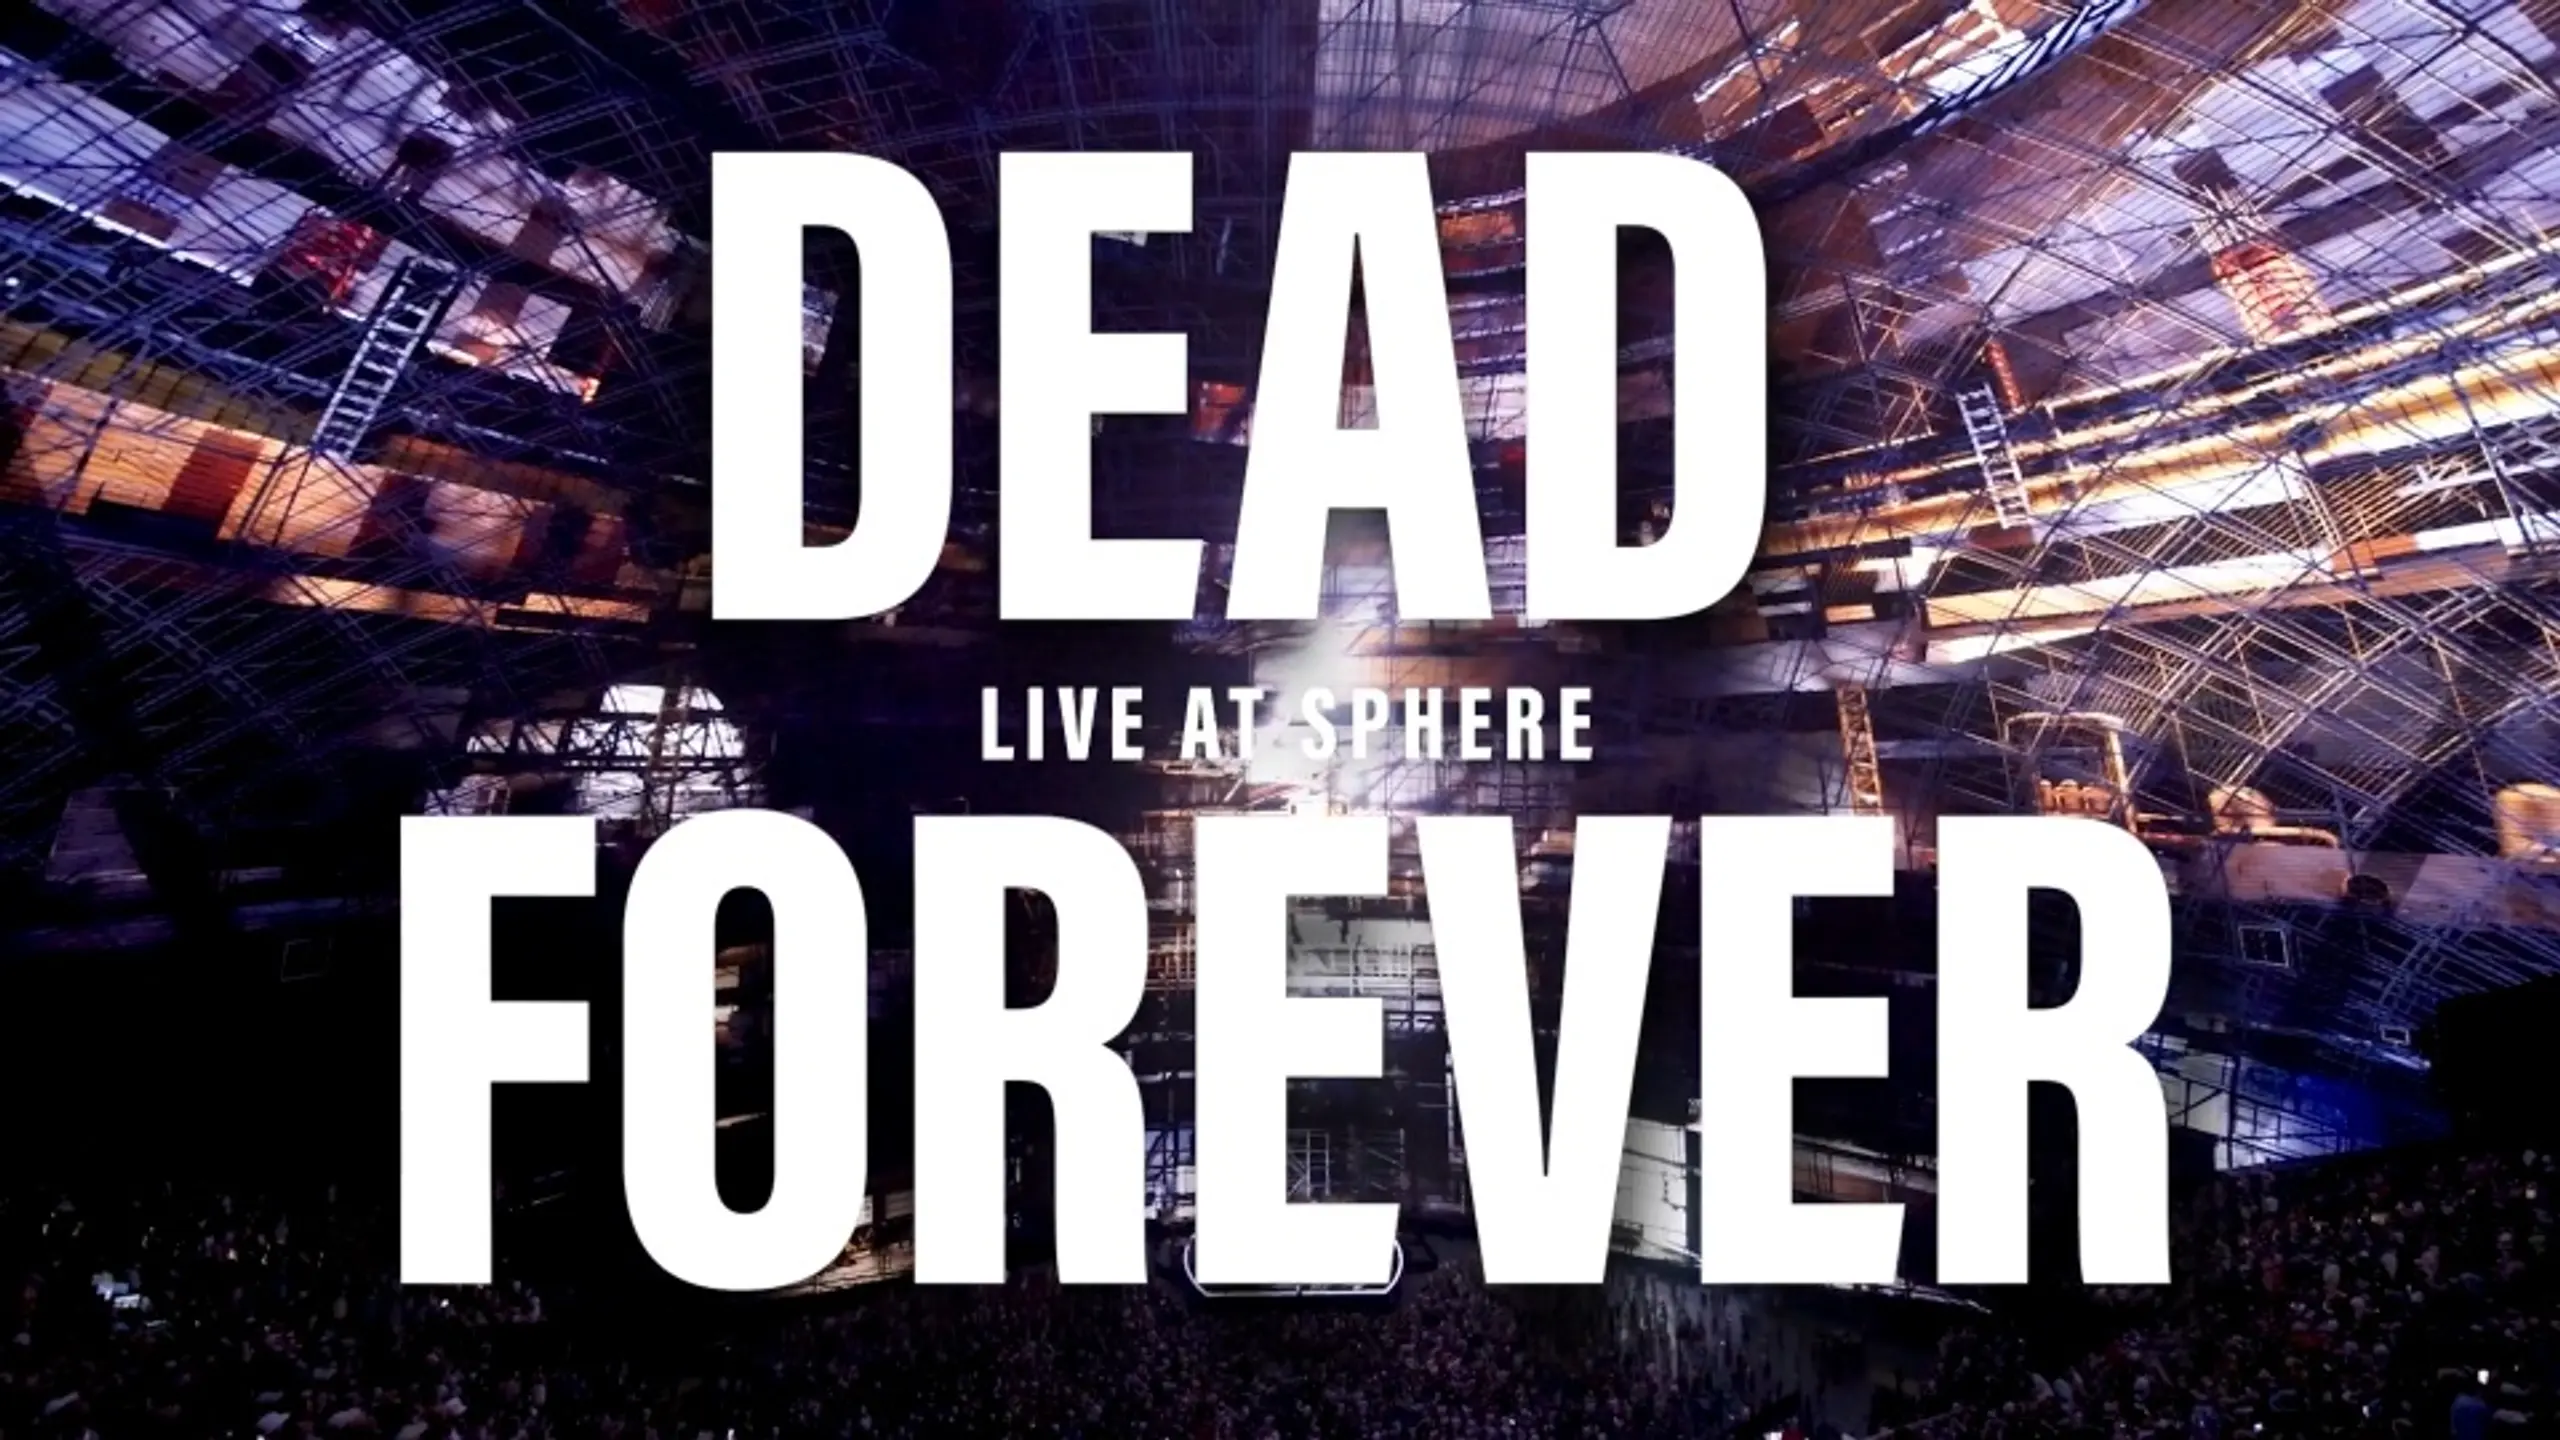
Some of the worlds largest screens need petabytes moving in real time. NeuralMesh distributes high-resolution content across media servers in minutes, not hours, before doors open.
Proof from the Studios and Venues Running NeuralMesh
How WEKA's M&E customers are using NeuralMesh to power every AI workload and maximize creative outcomes.
0+GB/s
Live video at 16K x 16K
U2:UV ran four concurrent 16K displays at Sphere across a 100Gb network at line-rate speed.
0%
Cut in cloud storage costs
Parliament VFX quartered its cloud storage spend and kept higher performance, across nine Super Bowl commercials and a Taylor Swift album launch.
0x
Faster AI training startup times
Luma AI went from 10 to 20 minutes of environment startup down to 30 to 60 seconds, at 95%+ utilization on its H100 nodes.
0.0PB
Distributed across 23 servers
Dead & Company moved 90TB of content per show at Sphere, rendering and encoding in minutes instead of hours.
WHY WEKA
Stop Paying Creators to Wait on Storage
M&E breaks storage from both ends at once: sequential 8K reads and millions of small-file metadata calls. Systems tuned for one tend to fall over on the other.
Enable Collaboration Across Distributed Studios
Hold high performance in every location and end versioning nightmares, using asynchronous writes and on-demand caching.
1 / 9
Enable Collaboration Across Distributed Studios
Hold high performance in every location and end versioning nightmares, using asynchronous writes and on-demand caching.
Dazzle Creators with an Uncompromising Experience
Enjoy a flawless, lag-free experience across demanding 4K, 8K, and 16K+ playback, color grading, and rendering pipelines.
Support Peak Rendering With Elastic Scalability
Adapt to unpredictable, heavy bursting workflows by independently scaling capacity and performance across concurrent clients.
1 / 3


“Technology is at its best when it gets out of the way of the creative process, and that is exactly what NeuralMesh did for us at Sphere. NeuralMesh made working with what were once unthinkable resolutions and file sizes a near effortless experience.”

Unify Heavy Research and Creative Pipelines
NeuralMesh unifies complex pipelines, delivering extreme throughput across shared multi-tenant clusters with zero performance stalls.
Frequently Asked Questions
Did this page meet your expectations?