More Compute Isn’t Enough
Get more from your AI infrastructure with storage built to keep compute productive.
Trusted by World’s Most Demanding AI Infrastructure


CHALLENGES
Building more compute makes everything around it matter more.
Every GPU you add increases the demands on the infrastructure around it. The challenge isn’t just acquiring more compute. It’s keeping that compute productive.
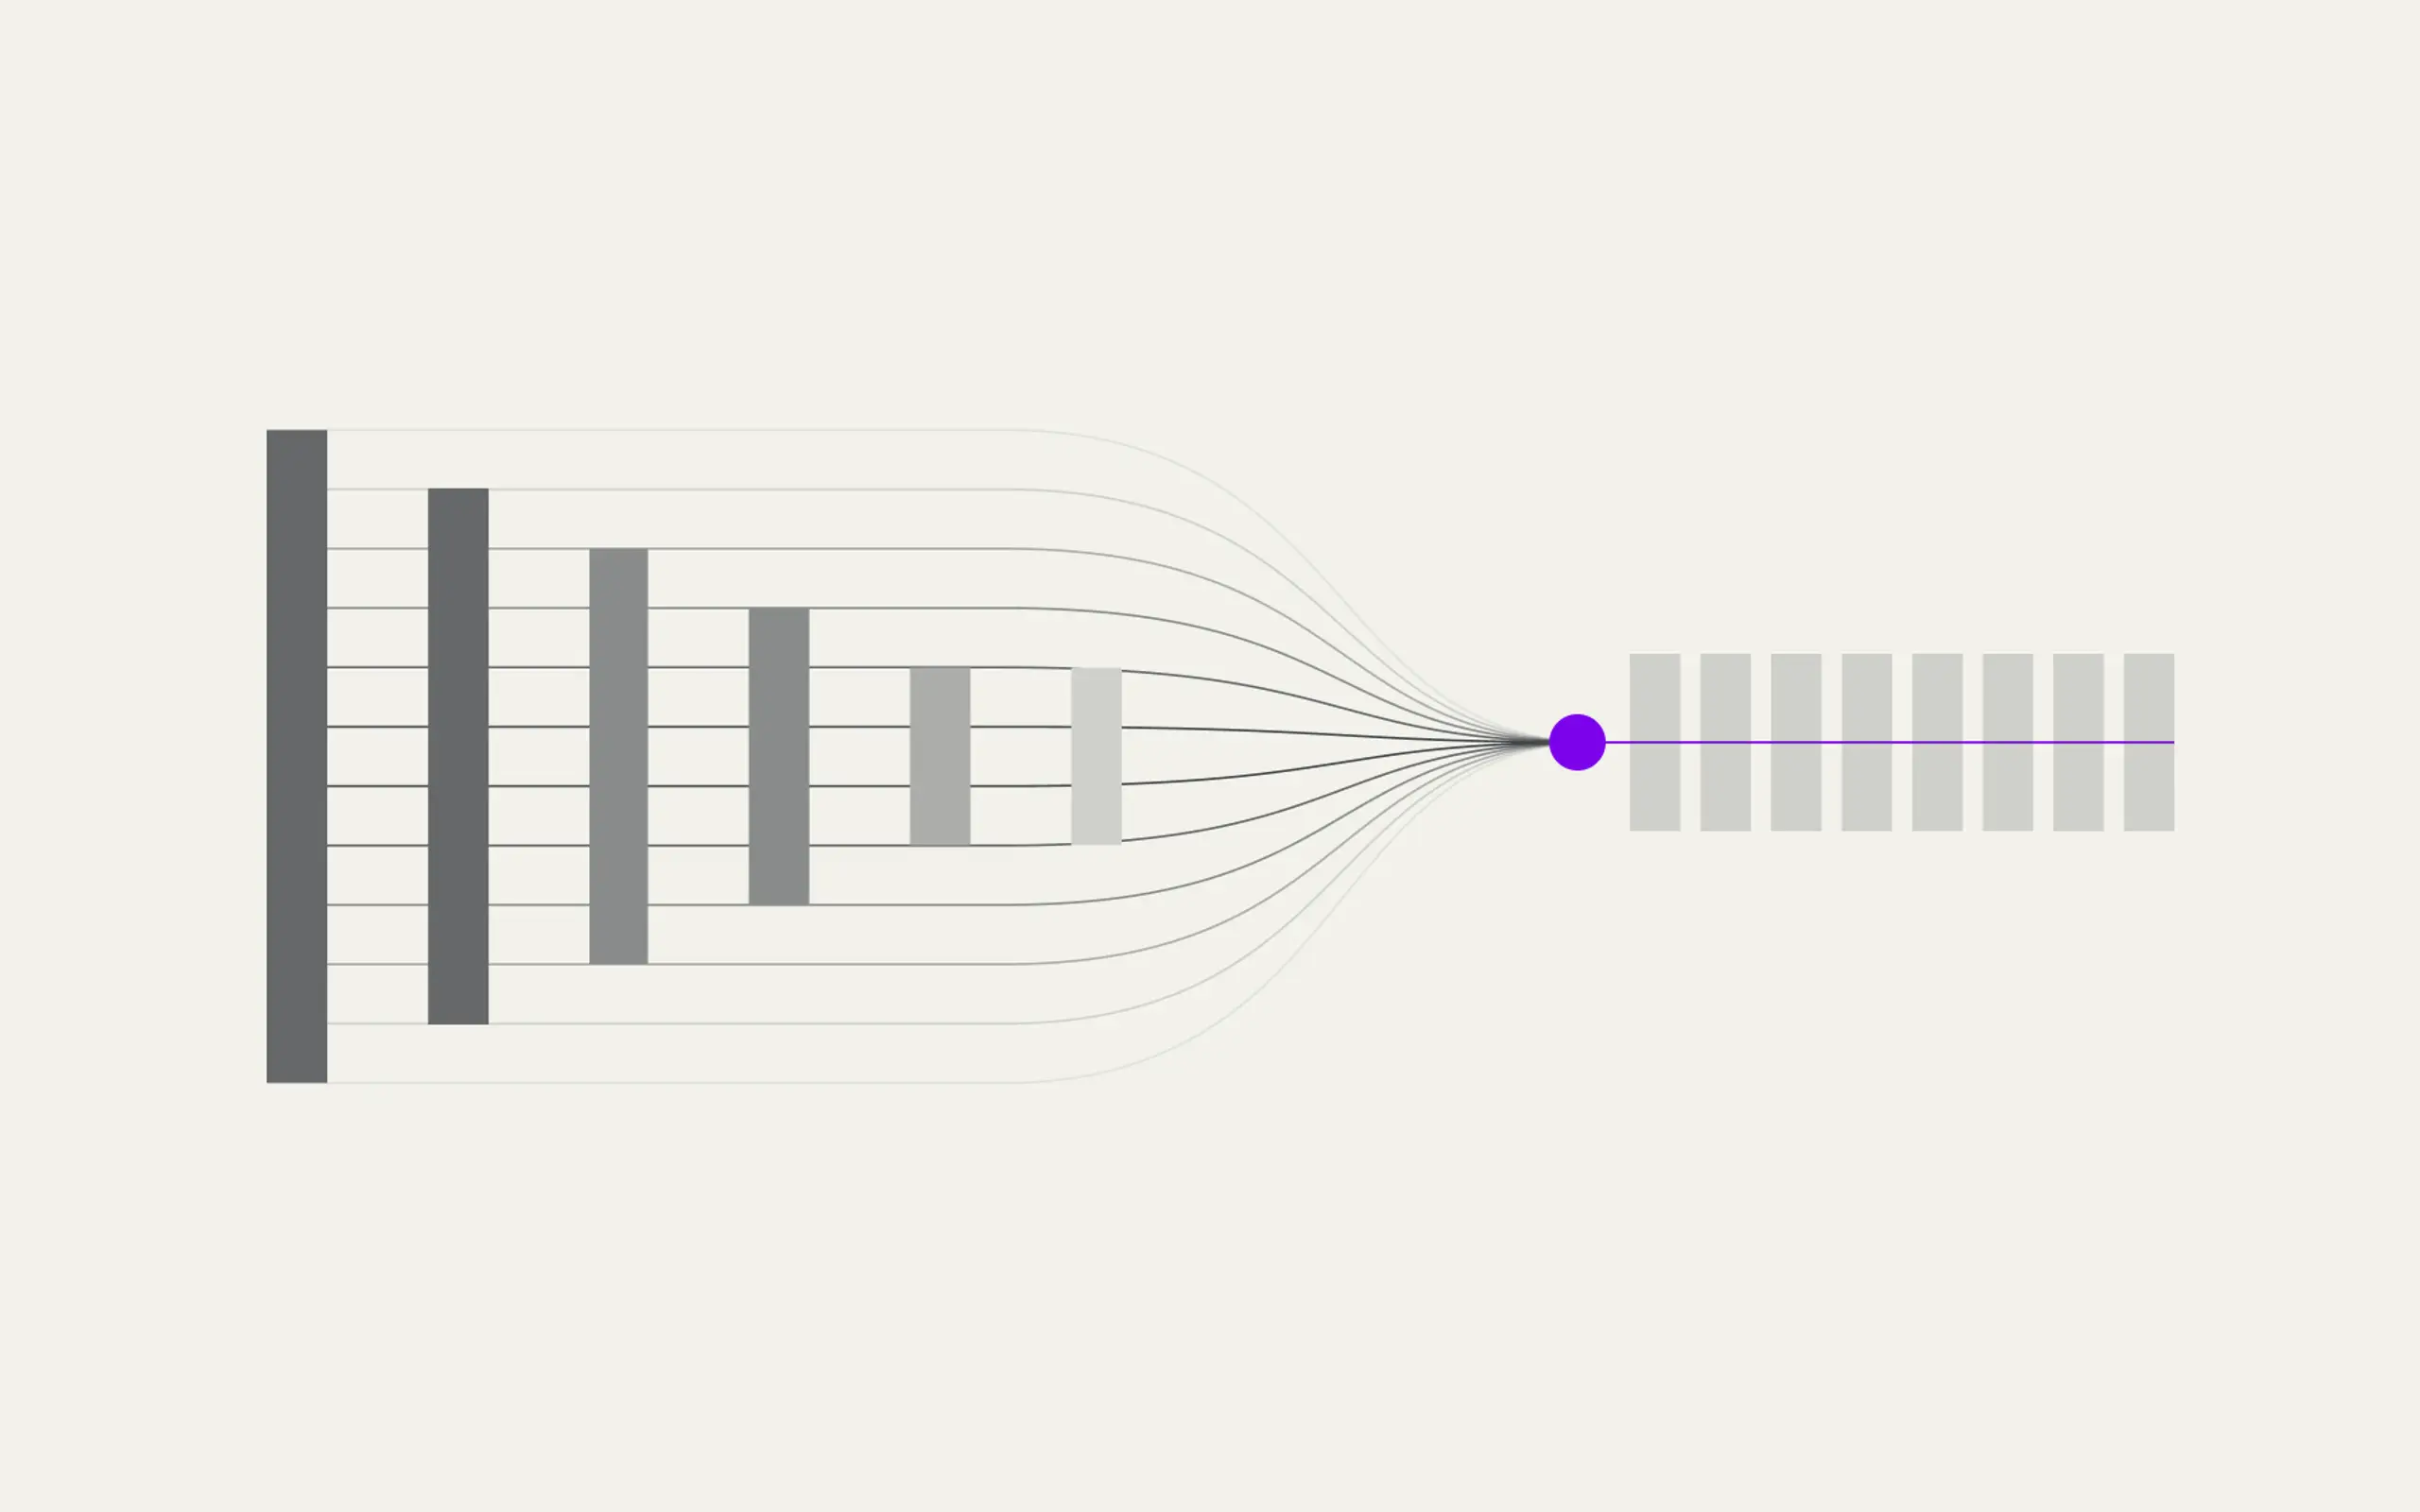
Faster GPUs Need Faster Data
Every generation of accelerators raises the performance storage must deliver to keep GPUs working instead of waiting on data.
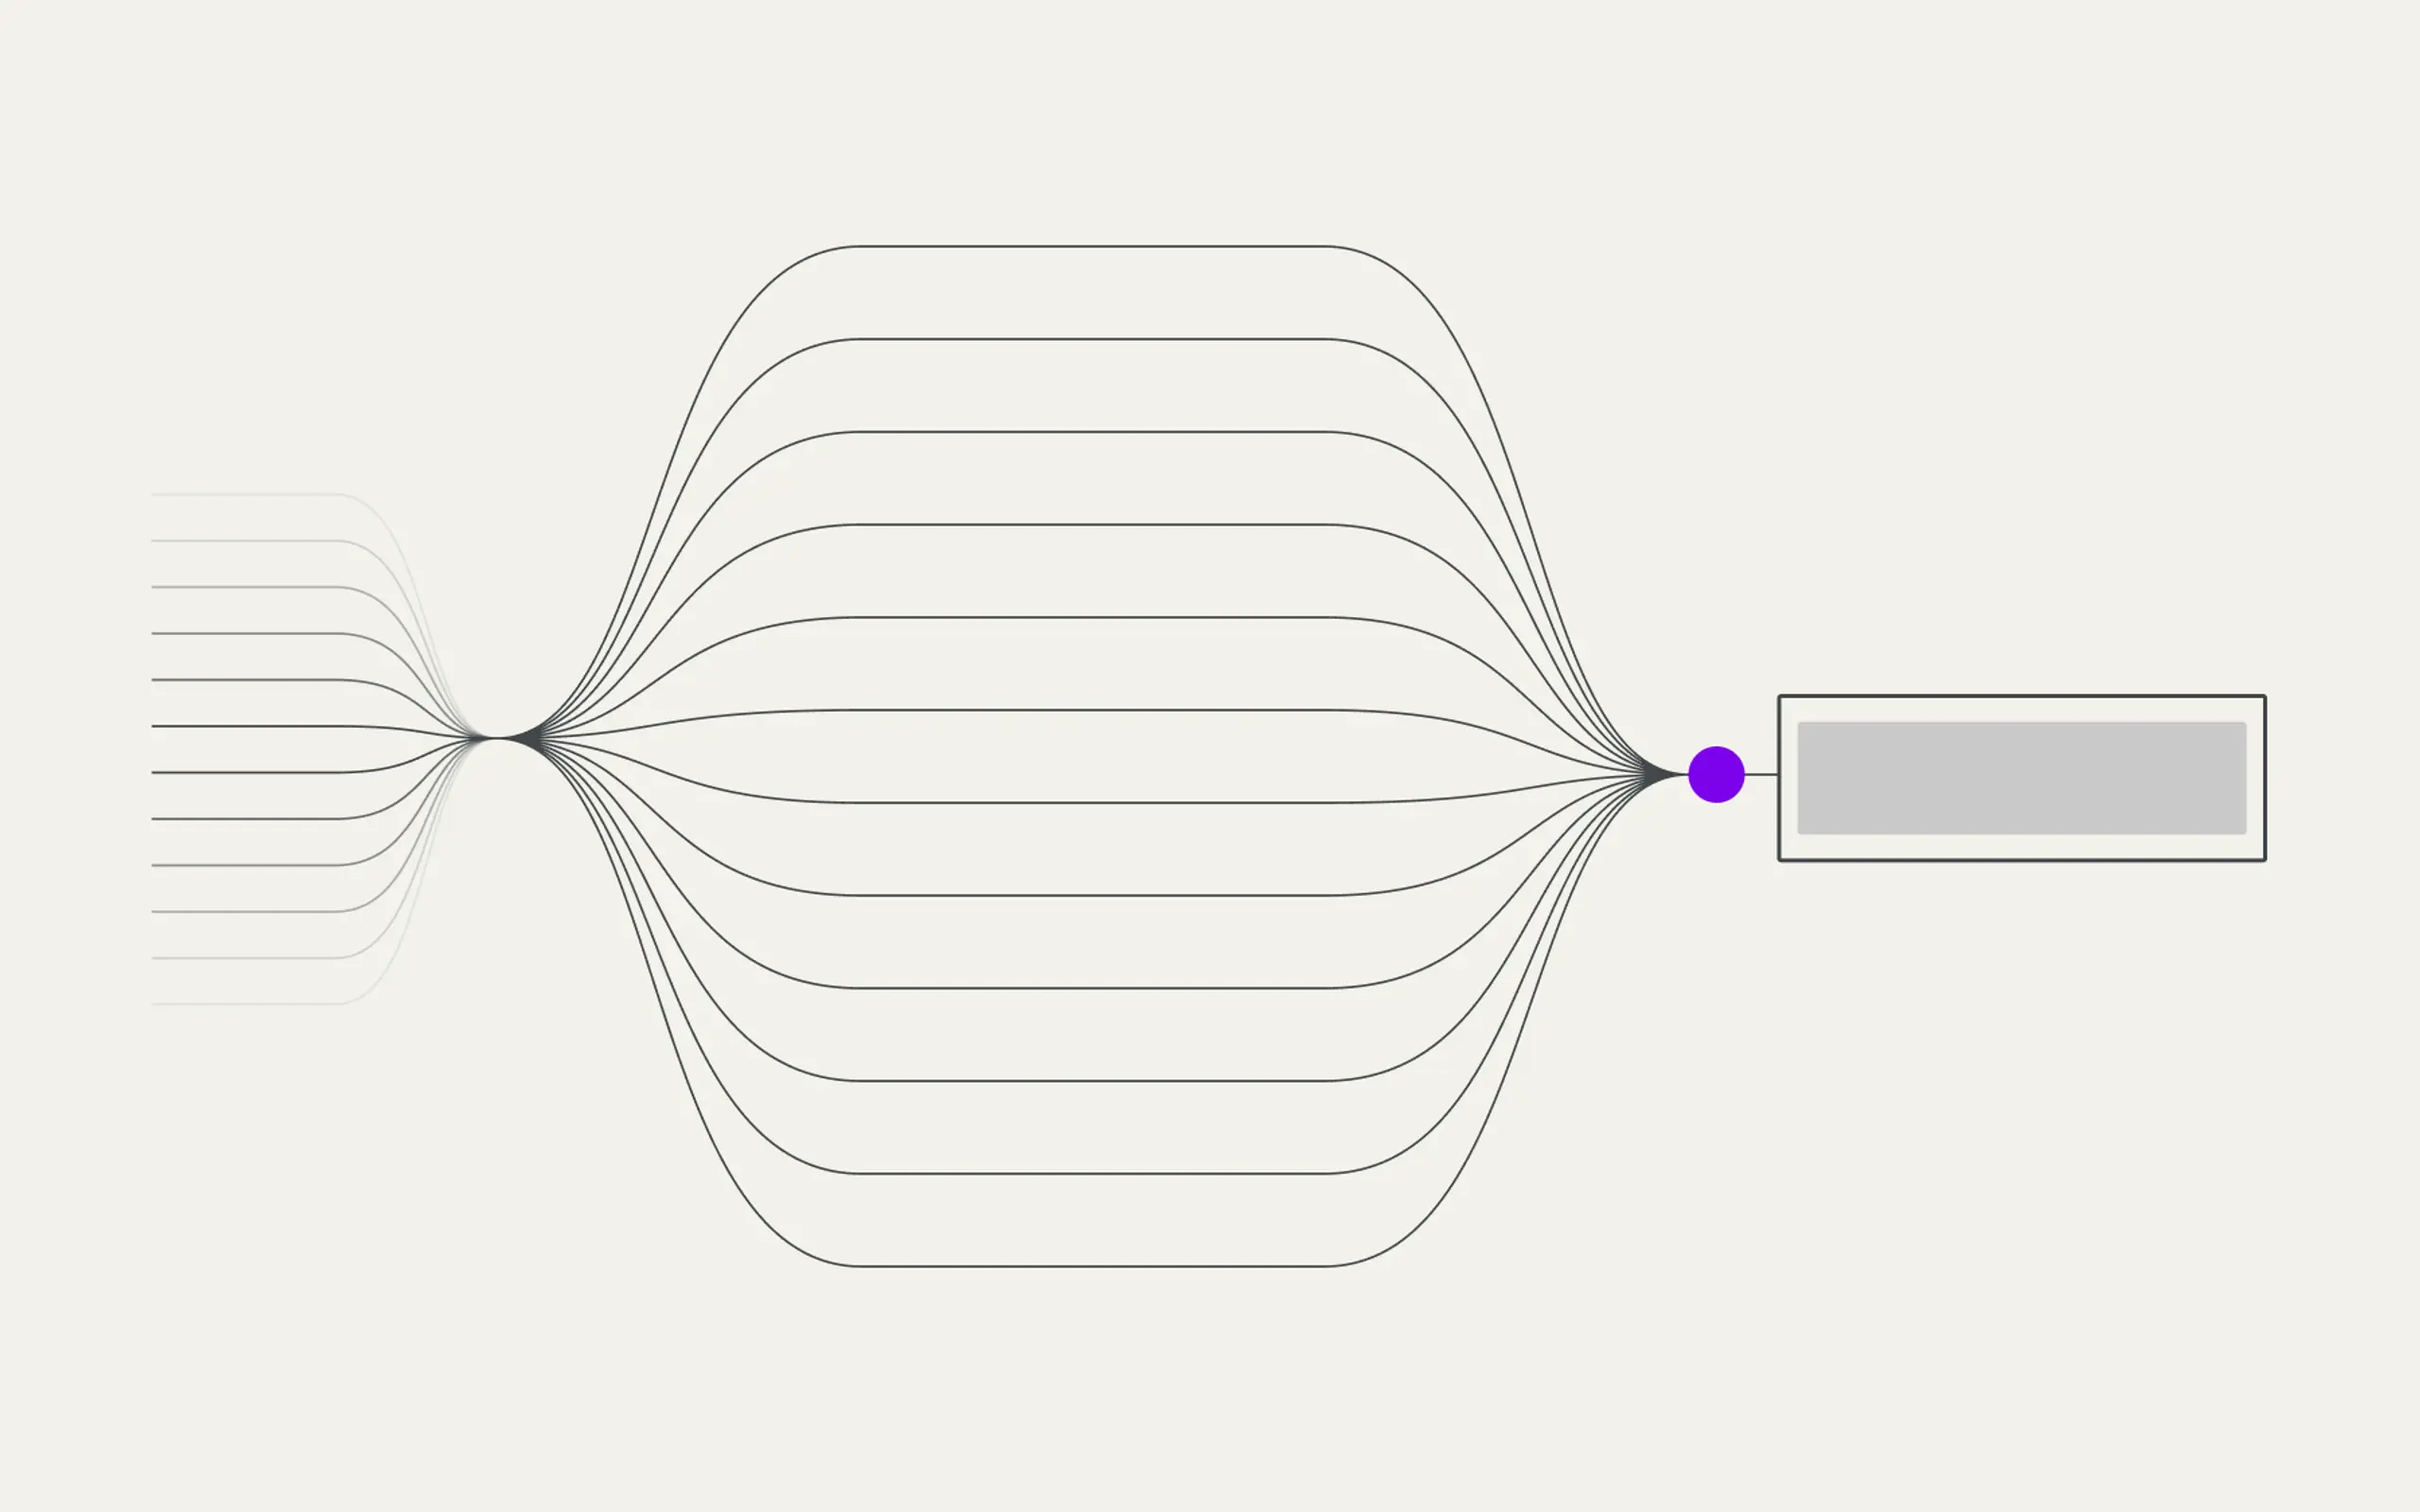
Scaling Compute Exposes Storage Bottlenecks
Storage that keeps up at pilot scale becomes the constraint as you scale into production.
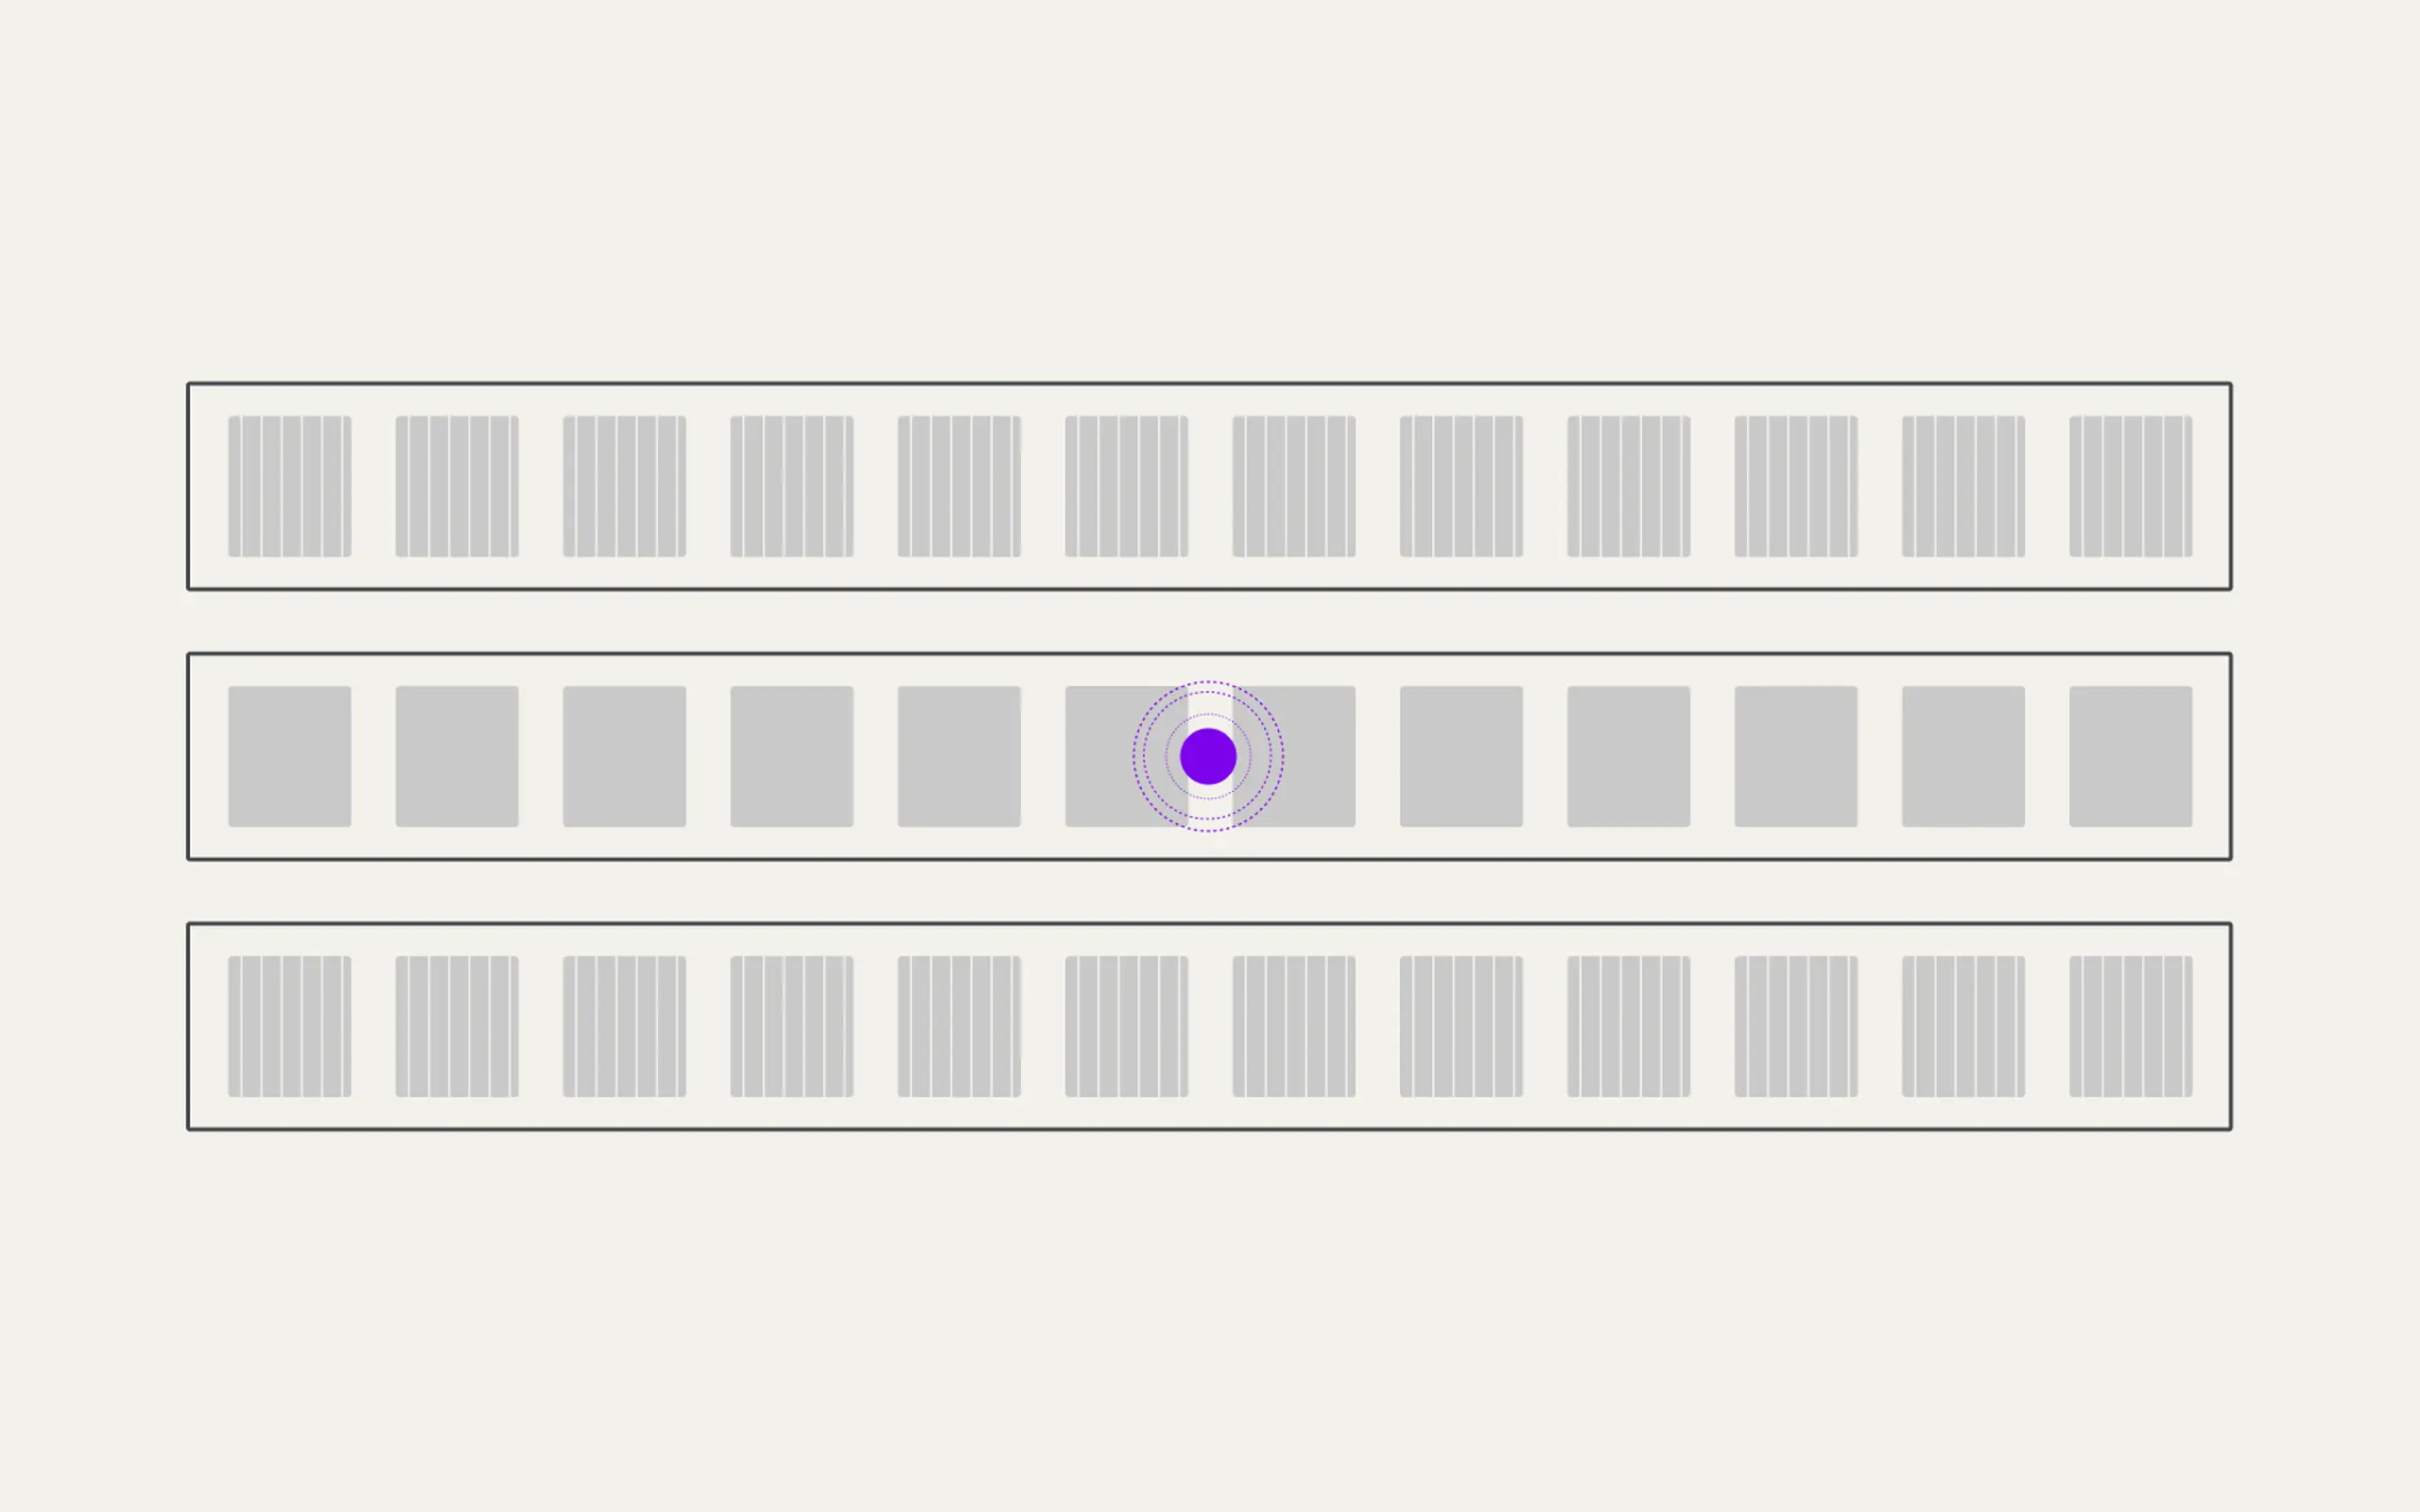
Every Data Center Resource Is Scarce
Data centers are constrained by space, power, and supply shortages that limit what you can do today and how you grow tomorrow.
BENEFITS
Storage Has to Do More Than Store Data
The standard for AI storage isn’t simply how fast the storage is. It’s what the storage enables the rest of your infrastructure to do.
Keep Compute Productive
Deliver data fast enough to keep GPUs working across the changing demands of AI workloads.
Scale With the Infrastructure
Grow performance, metadata capability, capacity, and resiliency as the compute environment expands.
Get More From Every Rack and Watt
Deliver the performance and capacity AI requires with greater density, leaving more data center resources available for compute.
Support the Work, Not Just a Workload
Keep data moving from preparation through computation to results, accelerating the full path to science and insight.
Measure Storage by What Your AI Infrastructure Delivers
The impact of AI storage shows up in the productivity of the infrastructure around it.
0%
GPU Utilization
0x
Higher Token Throughput
0x
Faster Experiments


Sam TabarCEO • WhiteFiber
“WEKA NeuralMesh's intelligent replication makes data mobility real at scale: we can make datasets visible across sites and pull exactly the data each job needs to the next GPU allocation as it becomes available. That shifts replication from a back-end protection function to a core part of how our distributed AI infrastructure needs to operate, improving workload mobility, capacity efficiency, and the resiliency our customers depend on. WEKA's data and memory infrastructure provides the foundation to scale our footprint without compromise.”

FEATURES
Built Differently for Accelerated Compute
WEKA® NeuralMesh™s was architected for the performance, scale, efficiency, and changing workload demands of accelerated compute and gives you multiple ways to put that architecture to work.
Build Storage for Accelerated Compute
NeuralMesh distributes data, metadata, and I/O across the cluster. Performance, capacity, and resilience scale with the cluster, while the architecture adapts to changing I/O demands, helping keep GPUs fed through training, checkpointing, inference, and other demanding AI workloads.
Go Deeper on AI Infrastructure
Scale Production AI Faster with NeuralMesh
Your models aren't slow. Your data is. Fix AI pipeline bottlenecks with high-throughput storage infrastructure.
Frequently Asked Questions
Did this page meet your expectations?