Maximize Token Output Across the AI Factory
Turn compute, memory, and power into more tokens
CHALLENGES
Every Layer of the AI Factory Shapes Token Economics
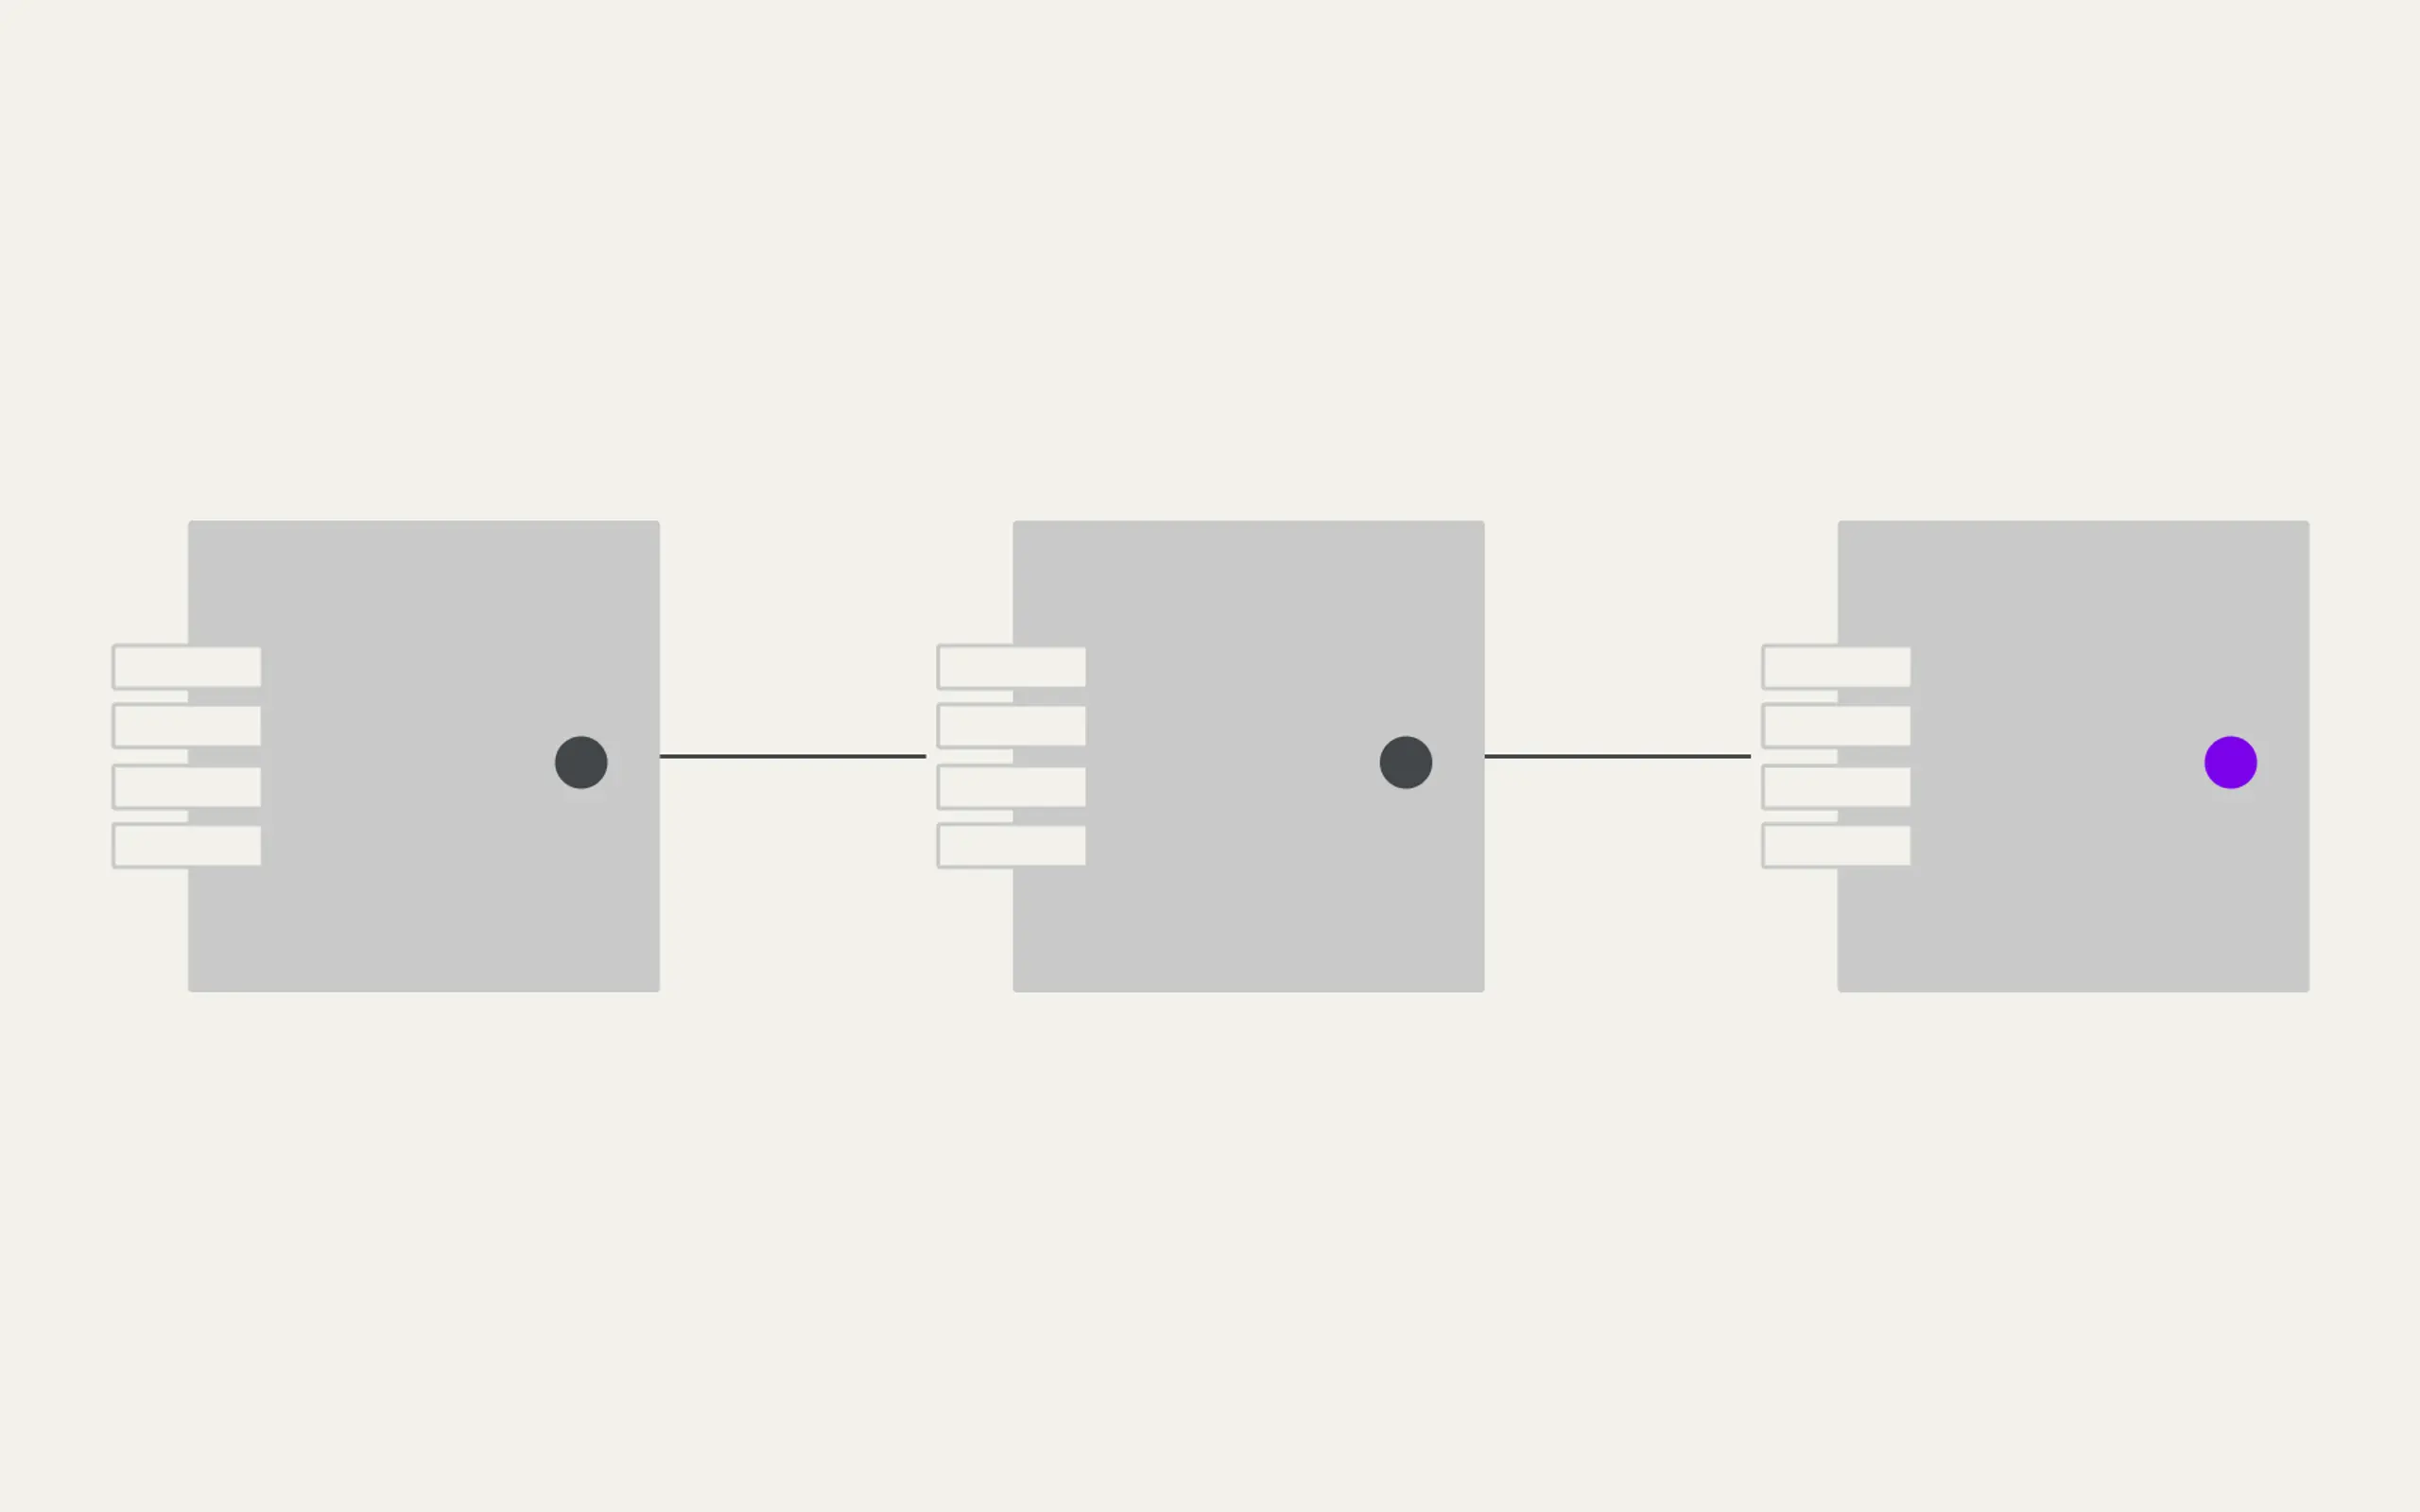
Repeated Work Makes Every Token More Expensive
When reusable context is lost, GPUs repeat prefill instead of generating new tokens, wasting time, power, and money.
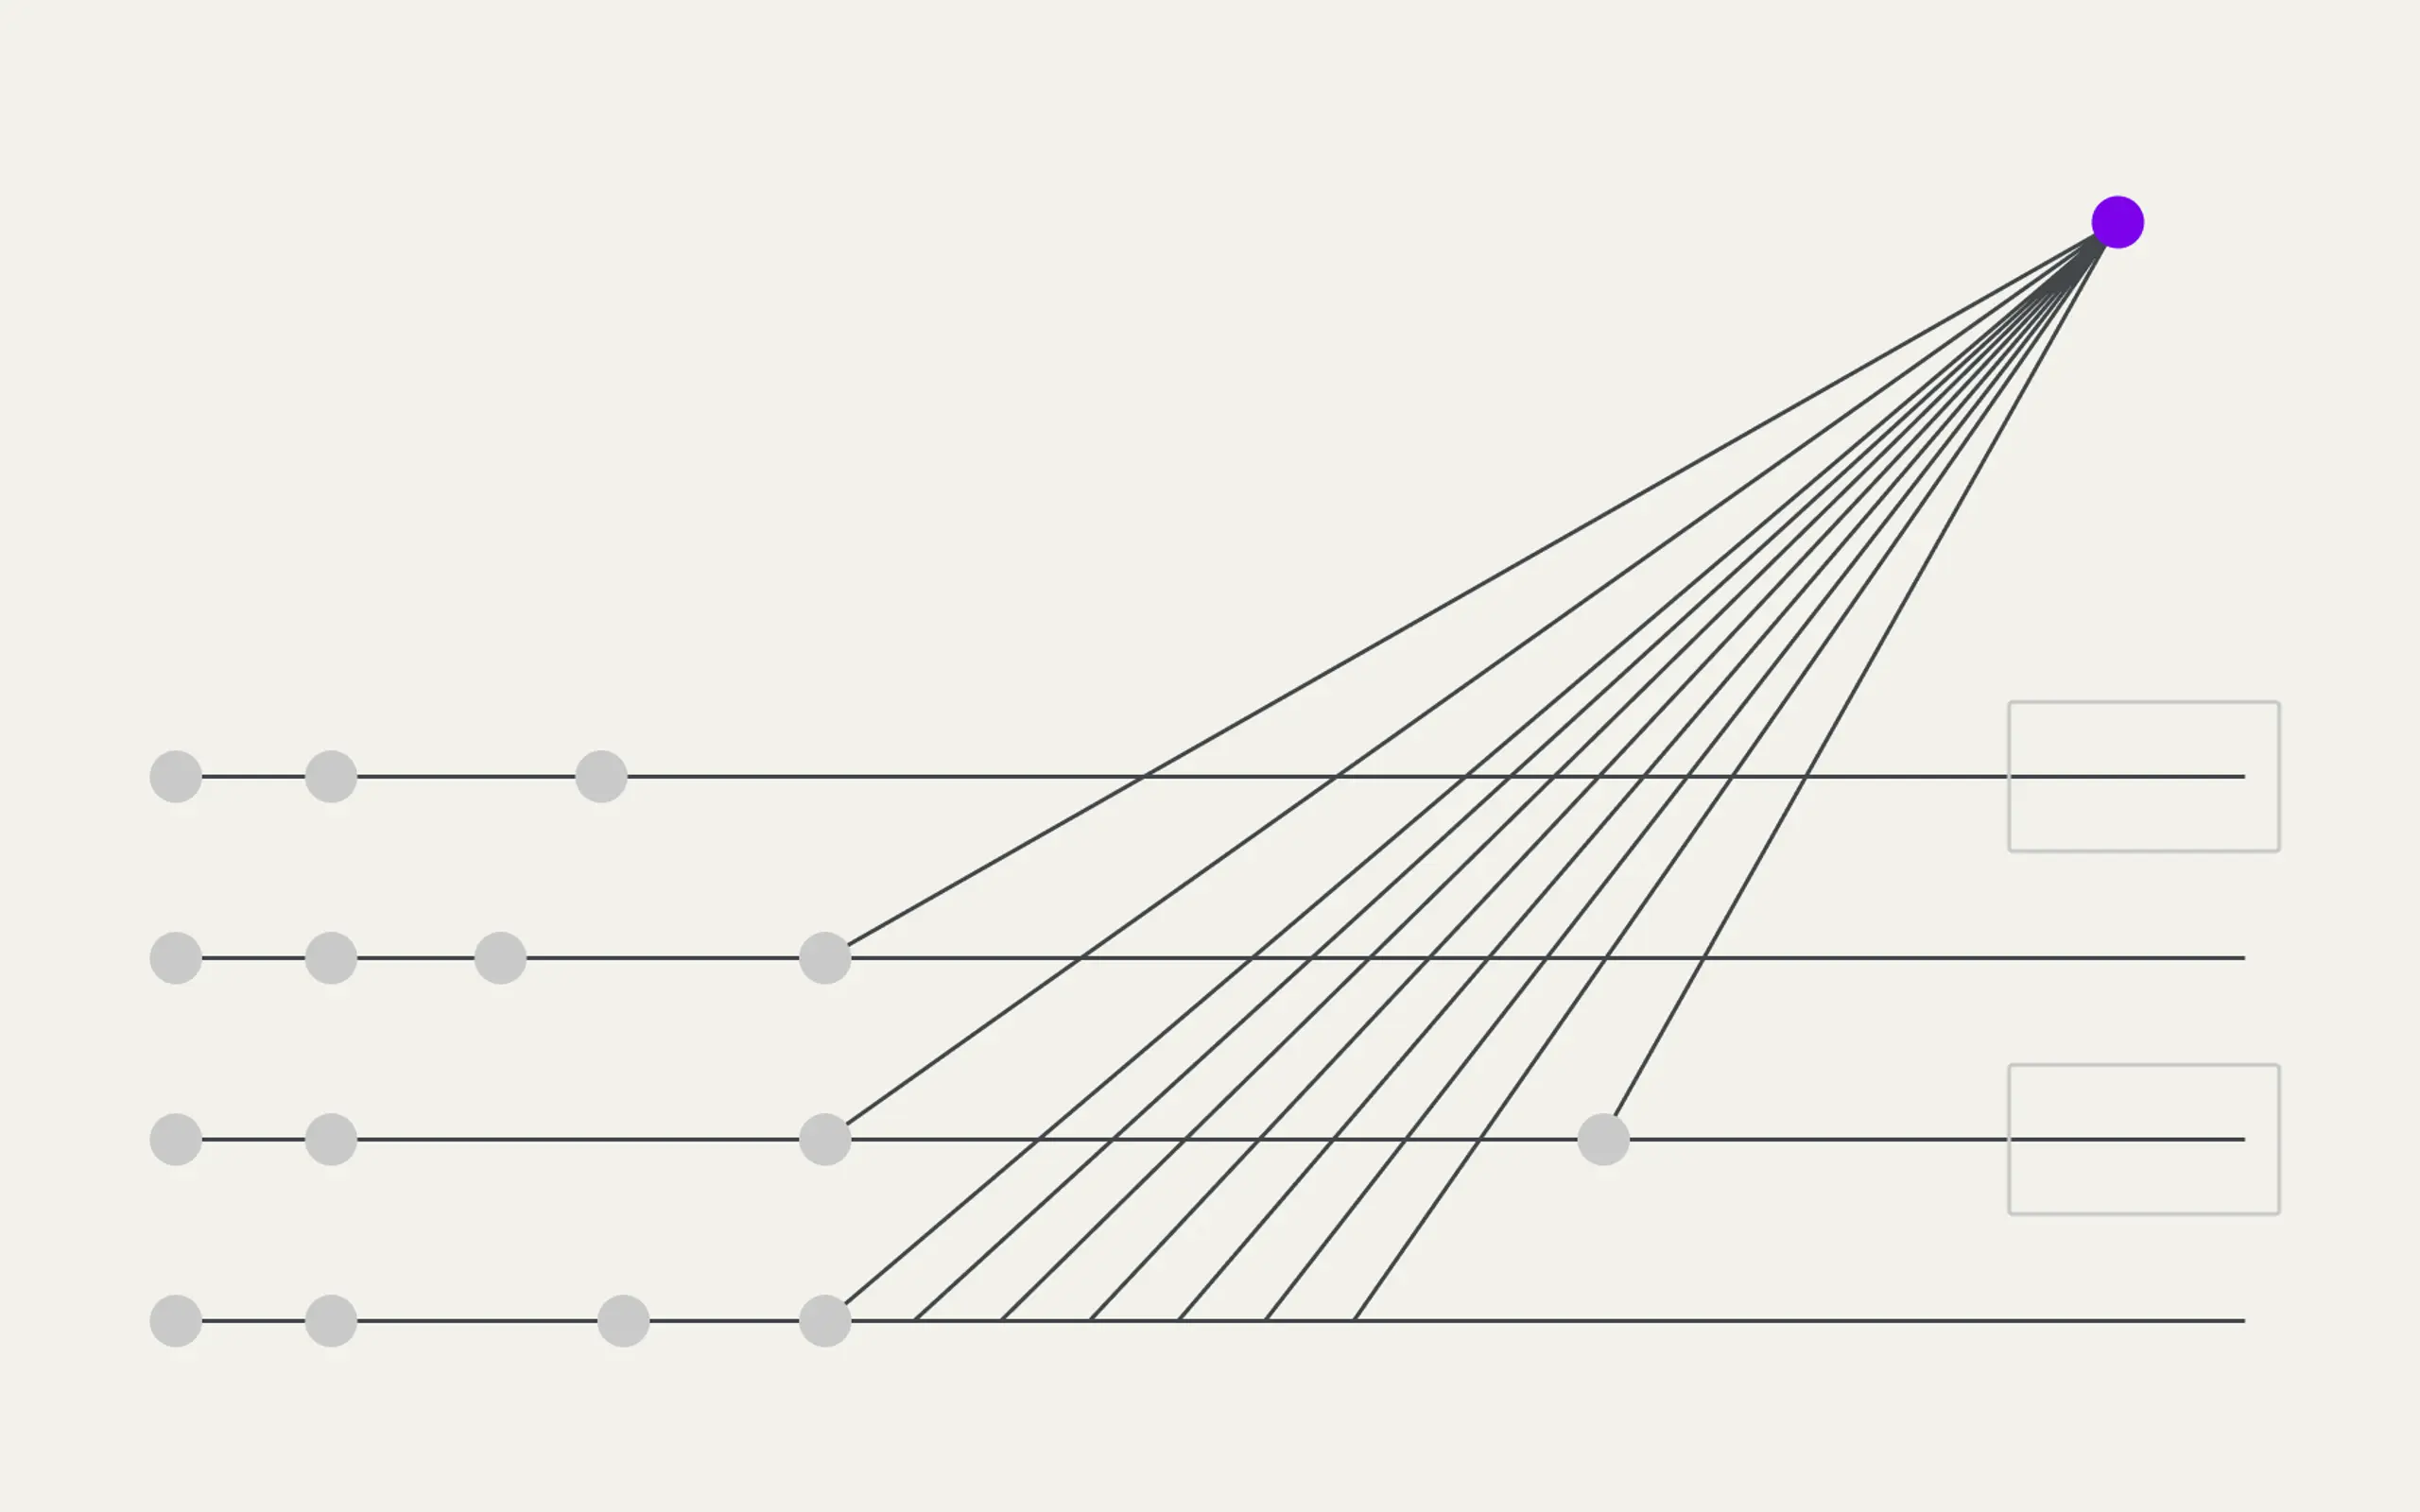
Token Demand Can Outpace Infrastructure Efficiency
More users and longer context increase memory, compute, power, and cooling demand faster than token output.
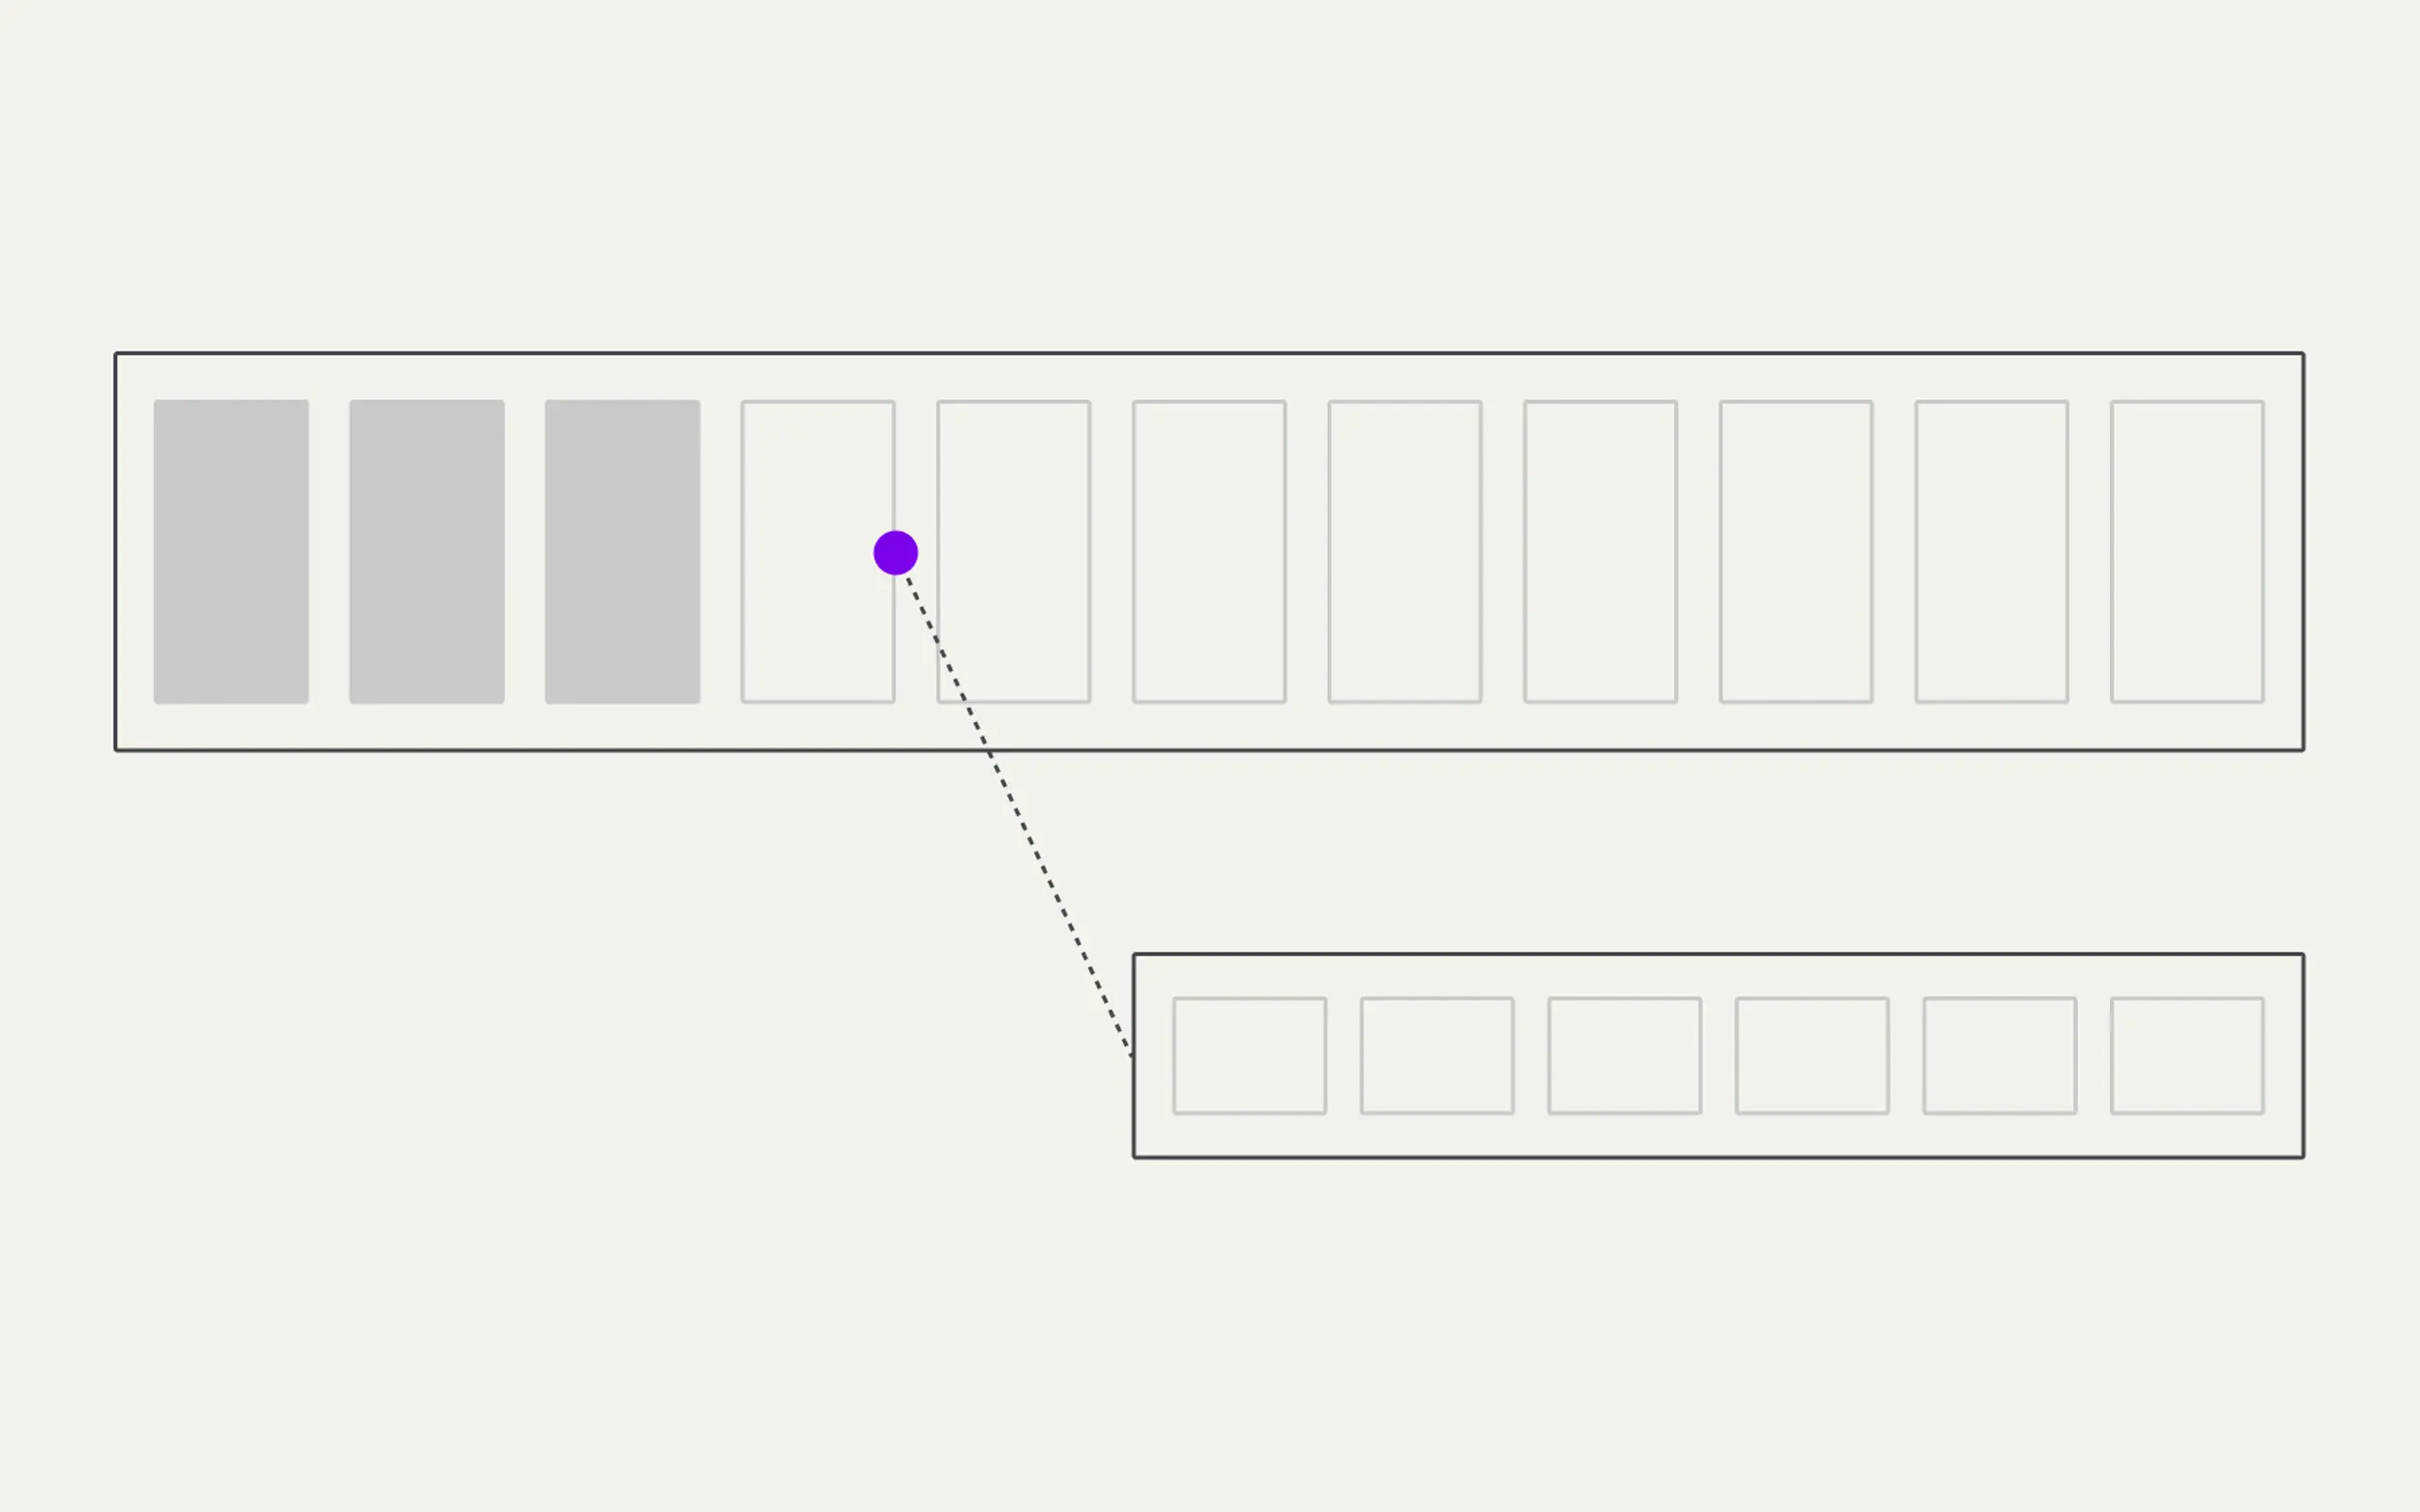
Resources Are Often Left on the Table
GPU resources can sit underused while teams add separate infrastructure, increasing cost and footprint.
BENEFITS
Turn Your Infrastructure Into a Lean Mean Token Machine
Reduce repeated work and infrastructure overhead so more of every GPU cycle, watt, and dollar go towards producing tokens.
Generate More Tokens From Every GPU
Reuse computed context so more GPU cycles go toward generating new tokens instead of repeating work.
Improve the Economics of Every Token
Increase useful token output without scaling compute, memory, power, cooling, and infrastructure cost at the same rate.
Get More From Your Infrastructure
Put underused GPU resources to work as part of the data layer instead of adding separate infrastructure.
Produce More Tokens From Every Rack
Increase data performance and density so less rack space and power are consumed by the infrastructure supporting GPUs.
More Token Output From the Infrastructure You Already Have
0x
Higher Token Throughput
0 seconds
Inference deployments took 5 minutes now occur in 15 seconds
Cohere
0.0 EB
effective capacity per rack

“WEKA’s NeuralMesh platform with Augmented Memory Grid on OCI helps remove memory bottlenecks, delivering substantially more throughput and concurrent users from the same GPU footprint. For customers, that means higher ROI on infrastructure investments and a clearer path to cost-efficient AI at scale.”

FEATURES
Improve Token Efficiency From GPU Memory to the Rack
WEKA® NeuralMesh™, WEKA Augmented Memory Grid™, NeuralMesh Axon™, and WEKApod™ improve how AI factories use compute, memory, data infrastructure, and physical datacenter capacity.
Reuse Context. Generate More New Tokens.
Store petabytes of key-value (KV) Cache in NeuralMesh and serve it back at memory speed, so GPUs spend less time repeating prefill and more time generating new tokens.


Deliver More Tokens From Every GPU and Watt
Turn idle compute into active throughput. Offload reusable context over RDMA to generate more tokens per rack.
Frequently Asked Questions
Did this page meet your expectations?