Faster Research From the GPUs You Already Own
Collapse storage silos, reclaim stranded GPUs, and speed discovery across Higher Ed teams with WEKA NeuralMesh.
Deployed at Universities, National Labs, and Observatories


USE CASES
One Namespace Serves Every Research Workload On Campus
Modern research I/O is metadata-bound: billions of small files, bursty parallel reads, constant checkpoints. NeuralMesh strips metadata across every node, so one system holds performance instead of forcing you to tune per workload.
Converging HPC and AI on Shared Clusters
Traditional HPC now runs on GPUs beside AI, and even non-AI jobs show AI-like patterns. NeuralMesh serves both from one cluster without per-workload tuning.
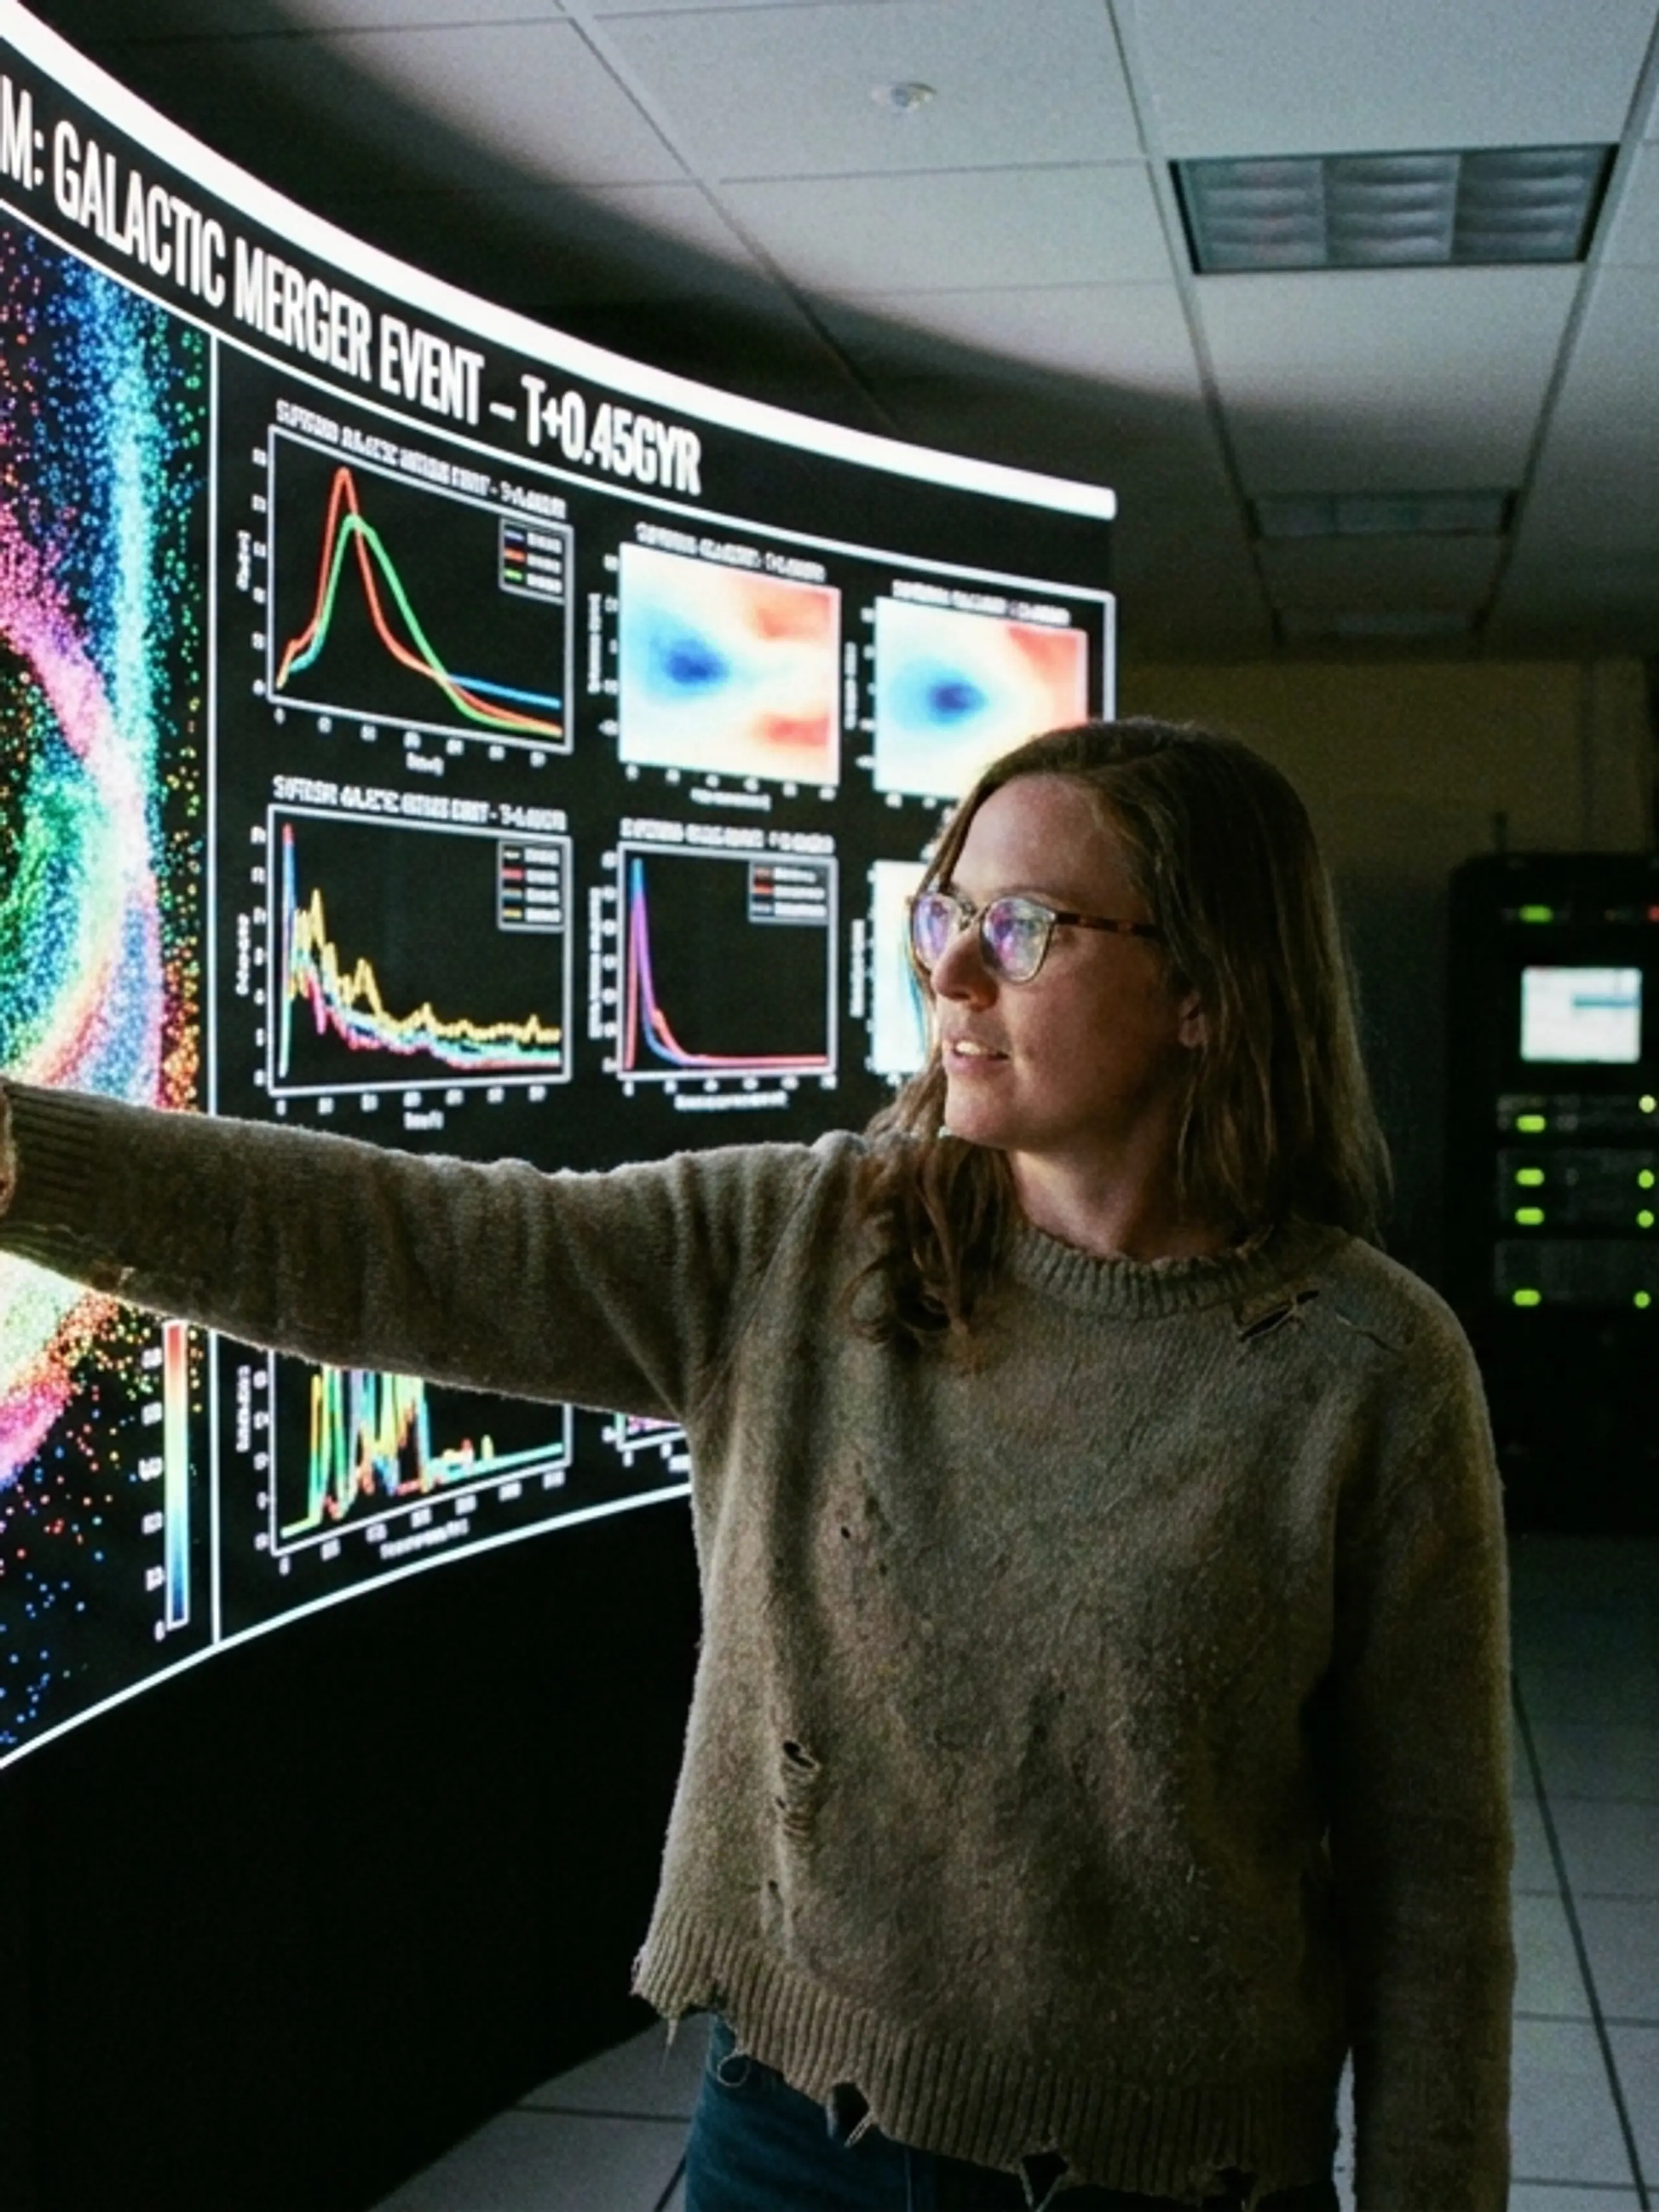
Scientific Simulation and Modeling
Climate, CFD, astrophysics, and materials runs mix large sequential reads with bursty parallel I/O. NeuralMesh serves both patterns without tuning trade-offs.
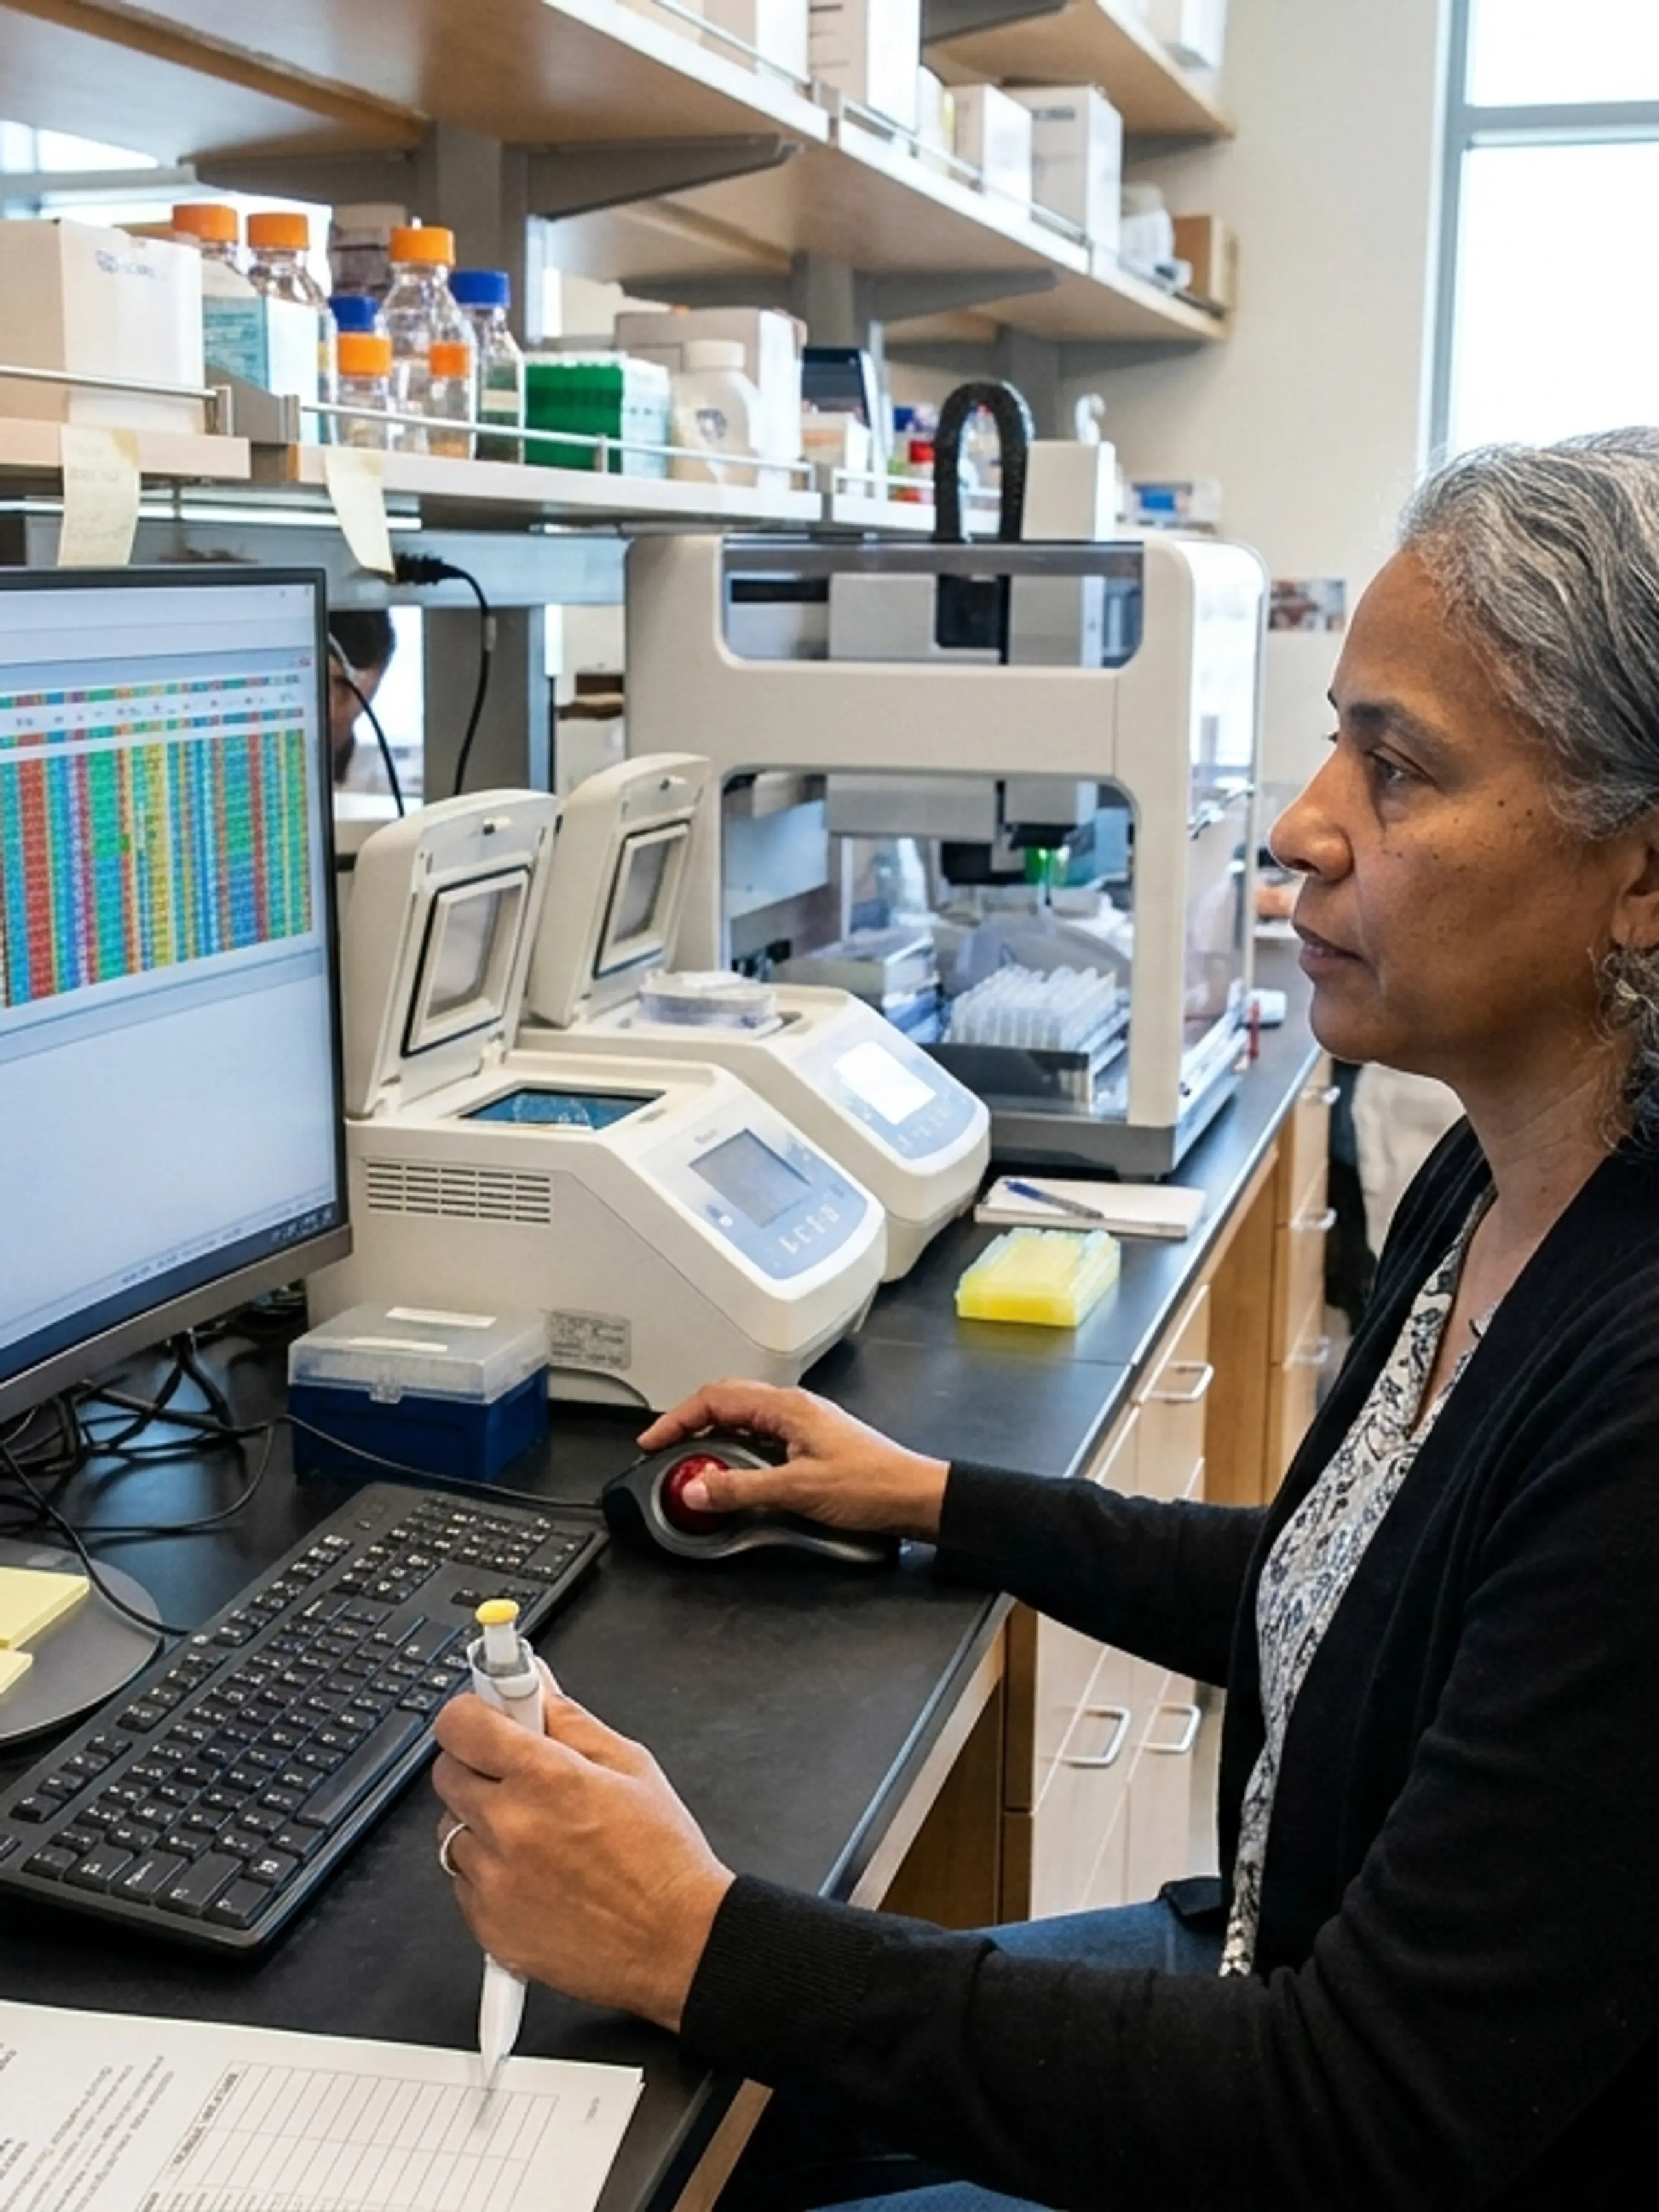
Genomics, Imaging, and Bioinformatics
Petabyte-scale sequence data makes metadata the bottleneck. NeuralMesh handles billions of small files natively and moves imaging into GPU pipelines without copies.
AI and Foundation Model Training
Campus AI factories fine-tune models for many groups at once. WEKA® NeuralMesh™ sustains long runs with rapid checkpointing and continuous read and write for agentic work.
Physical AI, Robotics, and Computer Vision
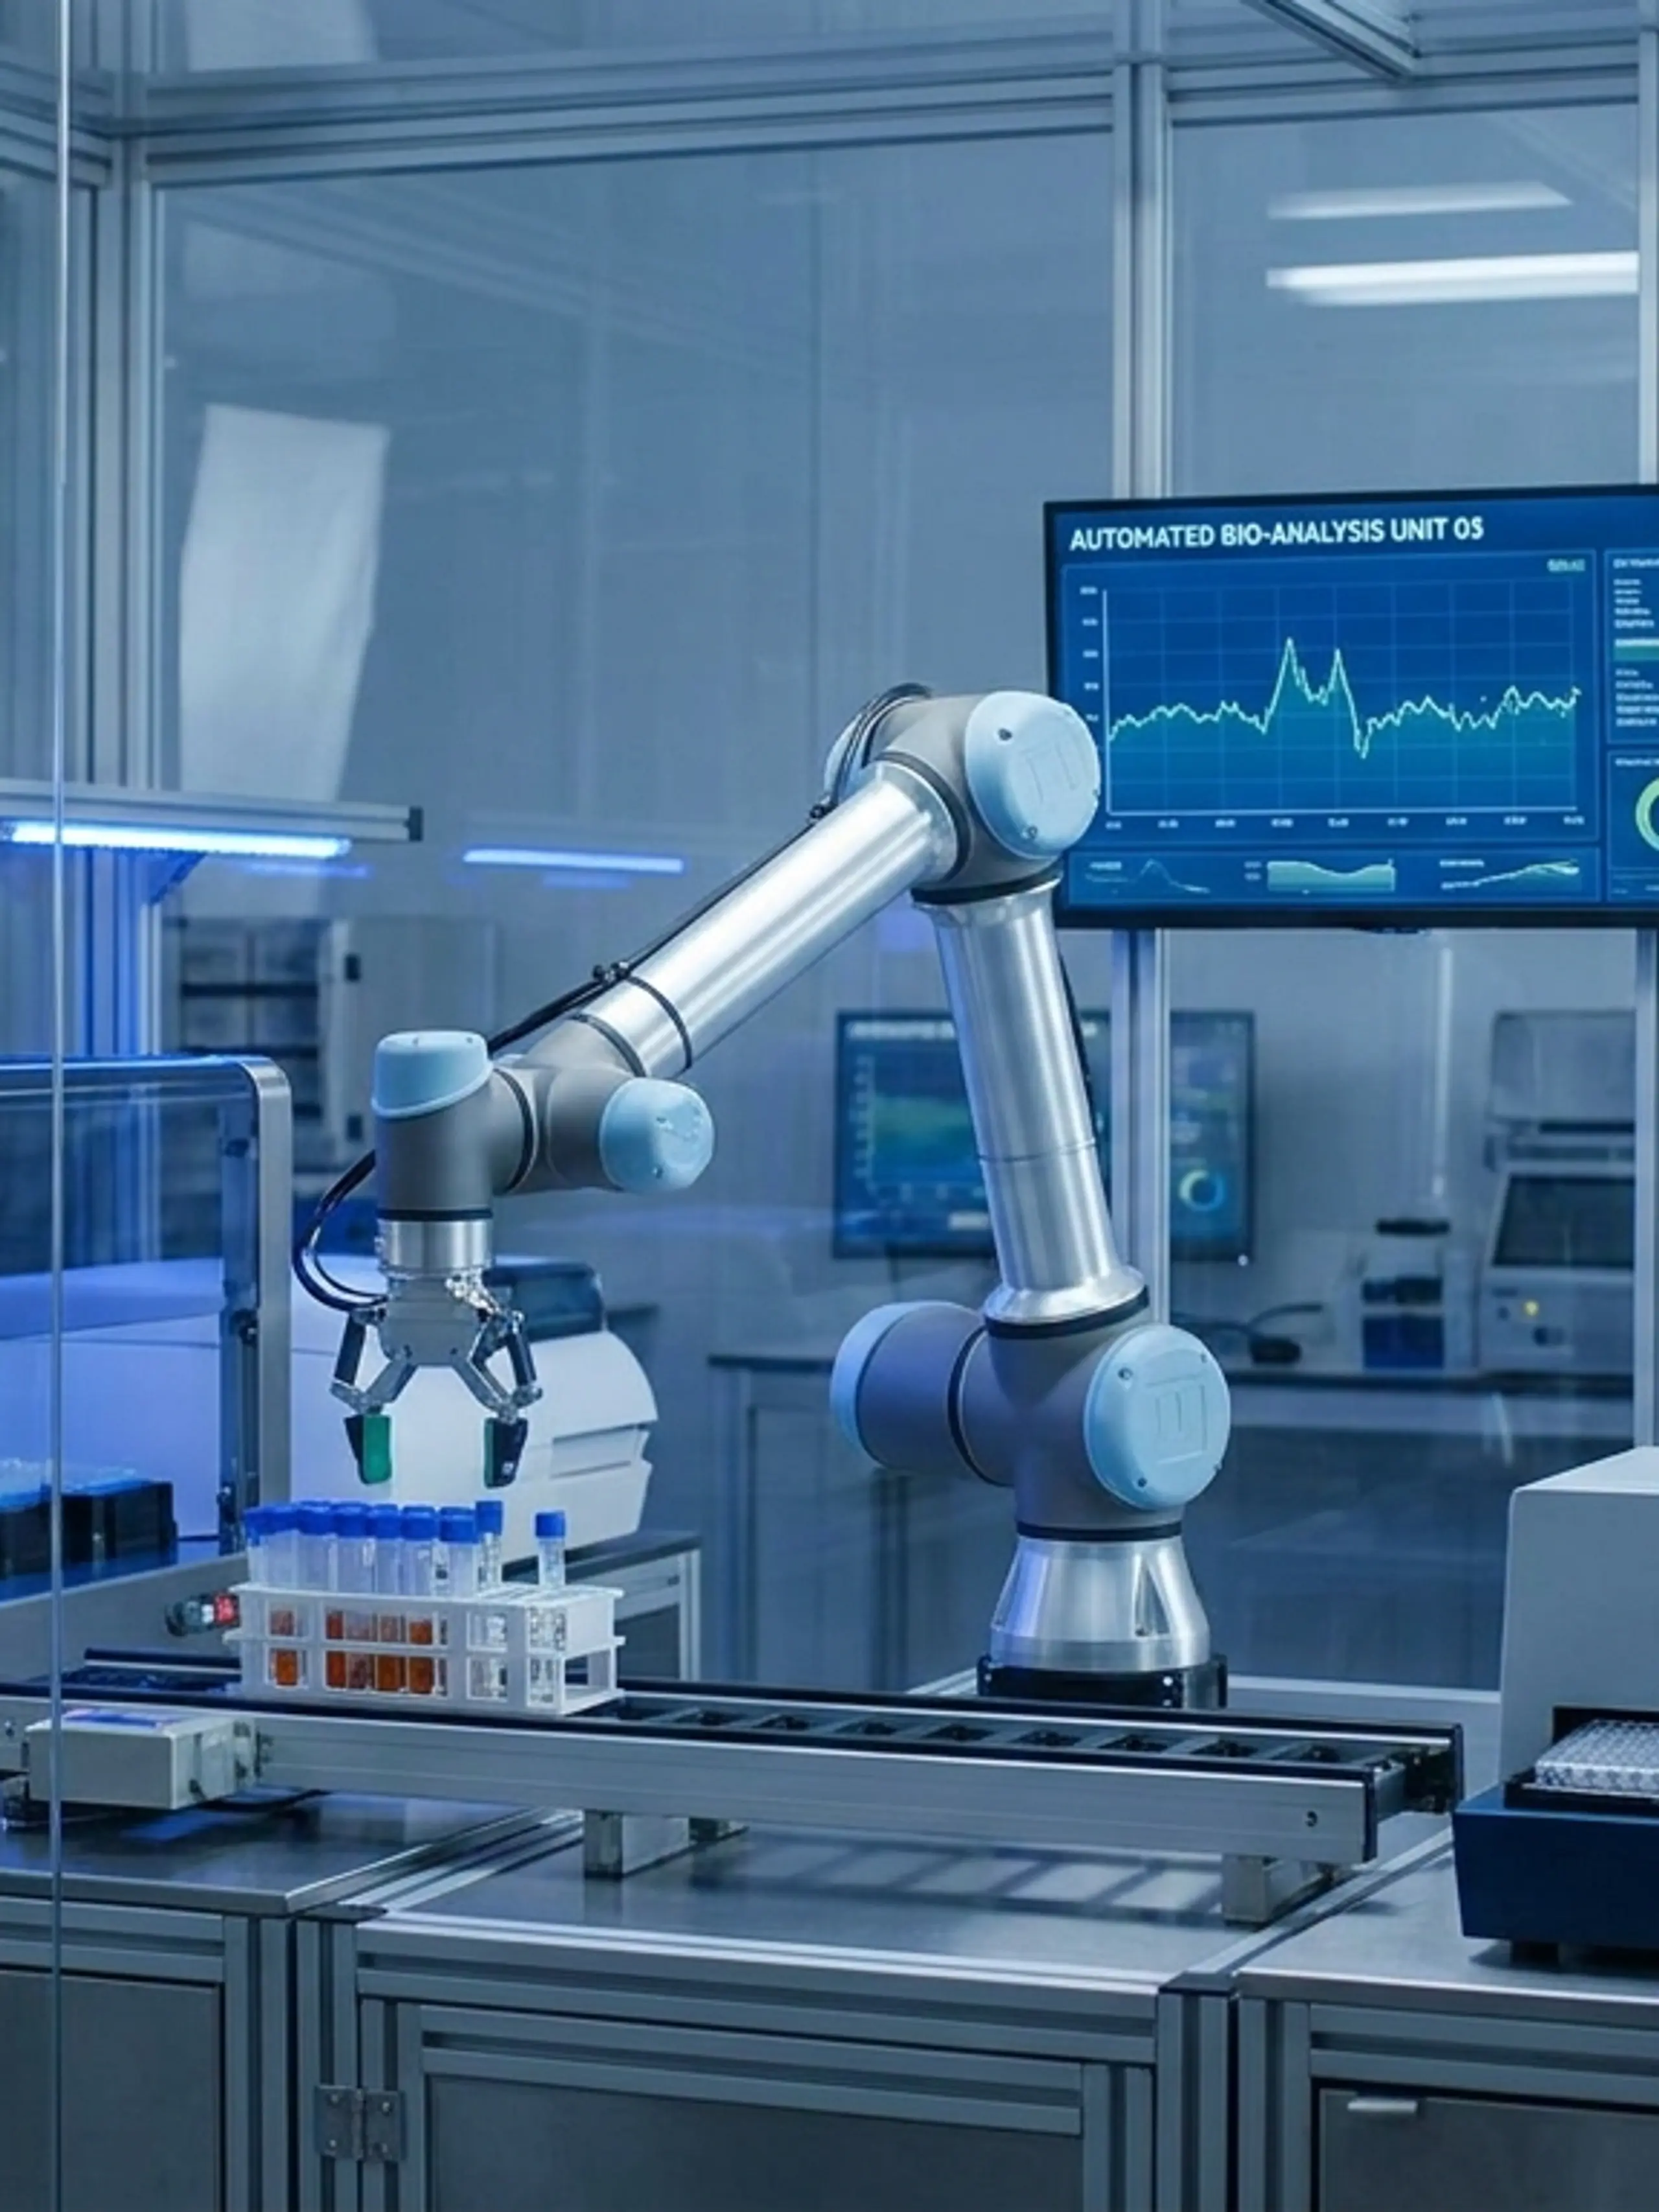
Synthetic data generation with NVIDIA Isaac and Omniverse, video analysis at scale, and small-file labeling all run on one system. No separate storage tier required.
What Universities Measured After Switching
Real results from named higher education institutions running NeuralMesh in production.
0x
Acceleration in research training times
0%
Reduction in cloud storage costs
0+
Concurrent researchers on one cluster
0%+
GPU utilization, up from ~30%
WHY WEKA
Stop Paying For GPUs That Wait On Storage
Research that is now metadata-heavy, small-file, and IOPS-bound breaks legacy storage systems that assume sequential I/O. Your GPUs pay for it.
Collapse Silos Into Shared Capacity
Converge isolated lab systems into one shared resource with full tenant isolation, reclaiming GPUs stranded inside departmental islands and putting grant dollars back to work.
1 / 9
Collapse Silos Into Shared Capacity
Converge isolated lab systems into one shared resource with full tenant isolation, reclaiming GPUs stranded inside departmental islands and putting grant dollars back to work.
Serve Every Workload From One Namespace
Store small files and large files, training data and archive, on a single system. Native POSIX, NFS, SMB, and S3 mean data moves between stages without copies.
Maximize GPU Utilization
Push utilization from roughly 30% on legacy systems past 90% by tuning NVIDIA GPUDirect Storage so every application node stays continuously fed.
1 / 3

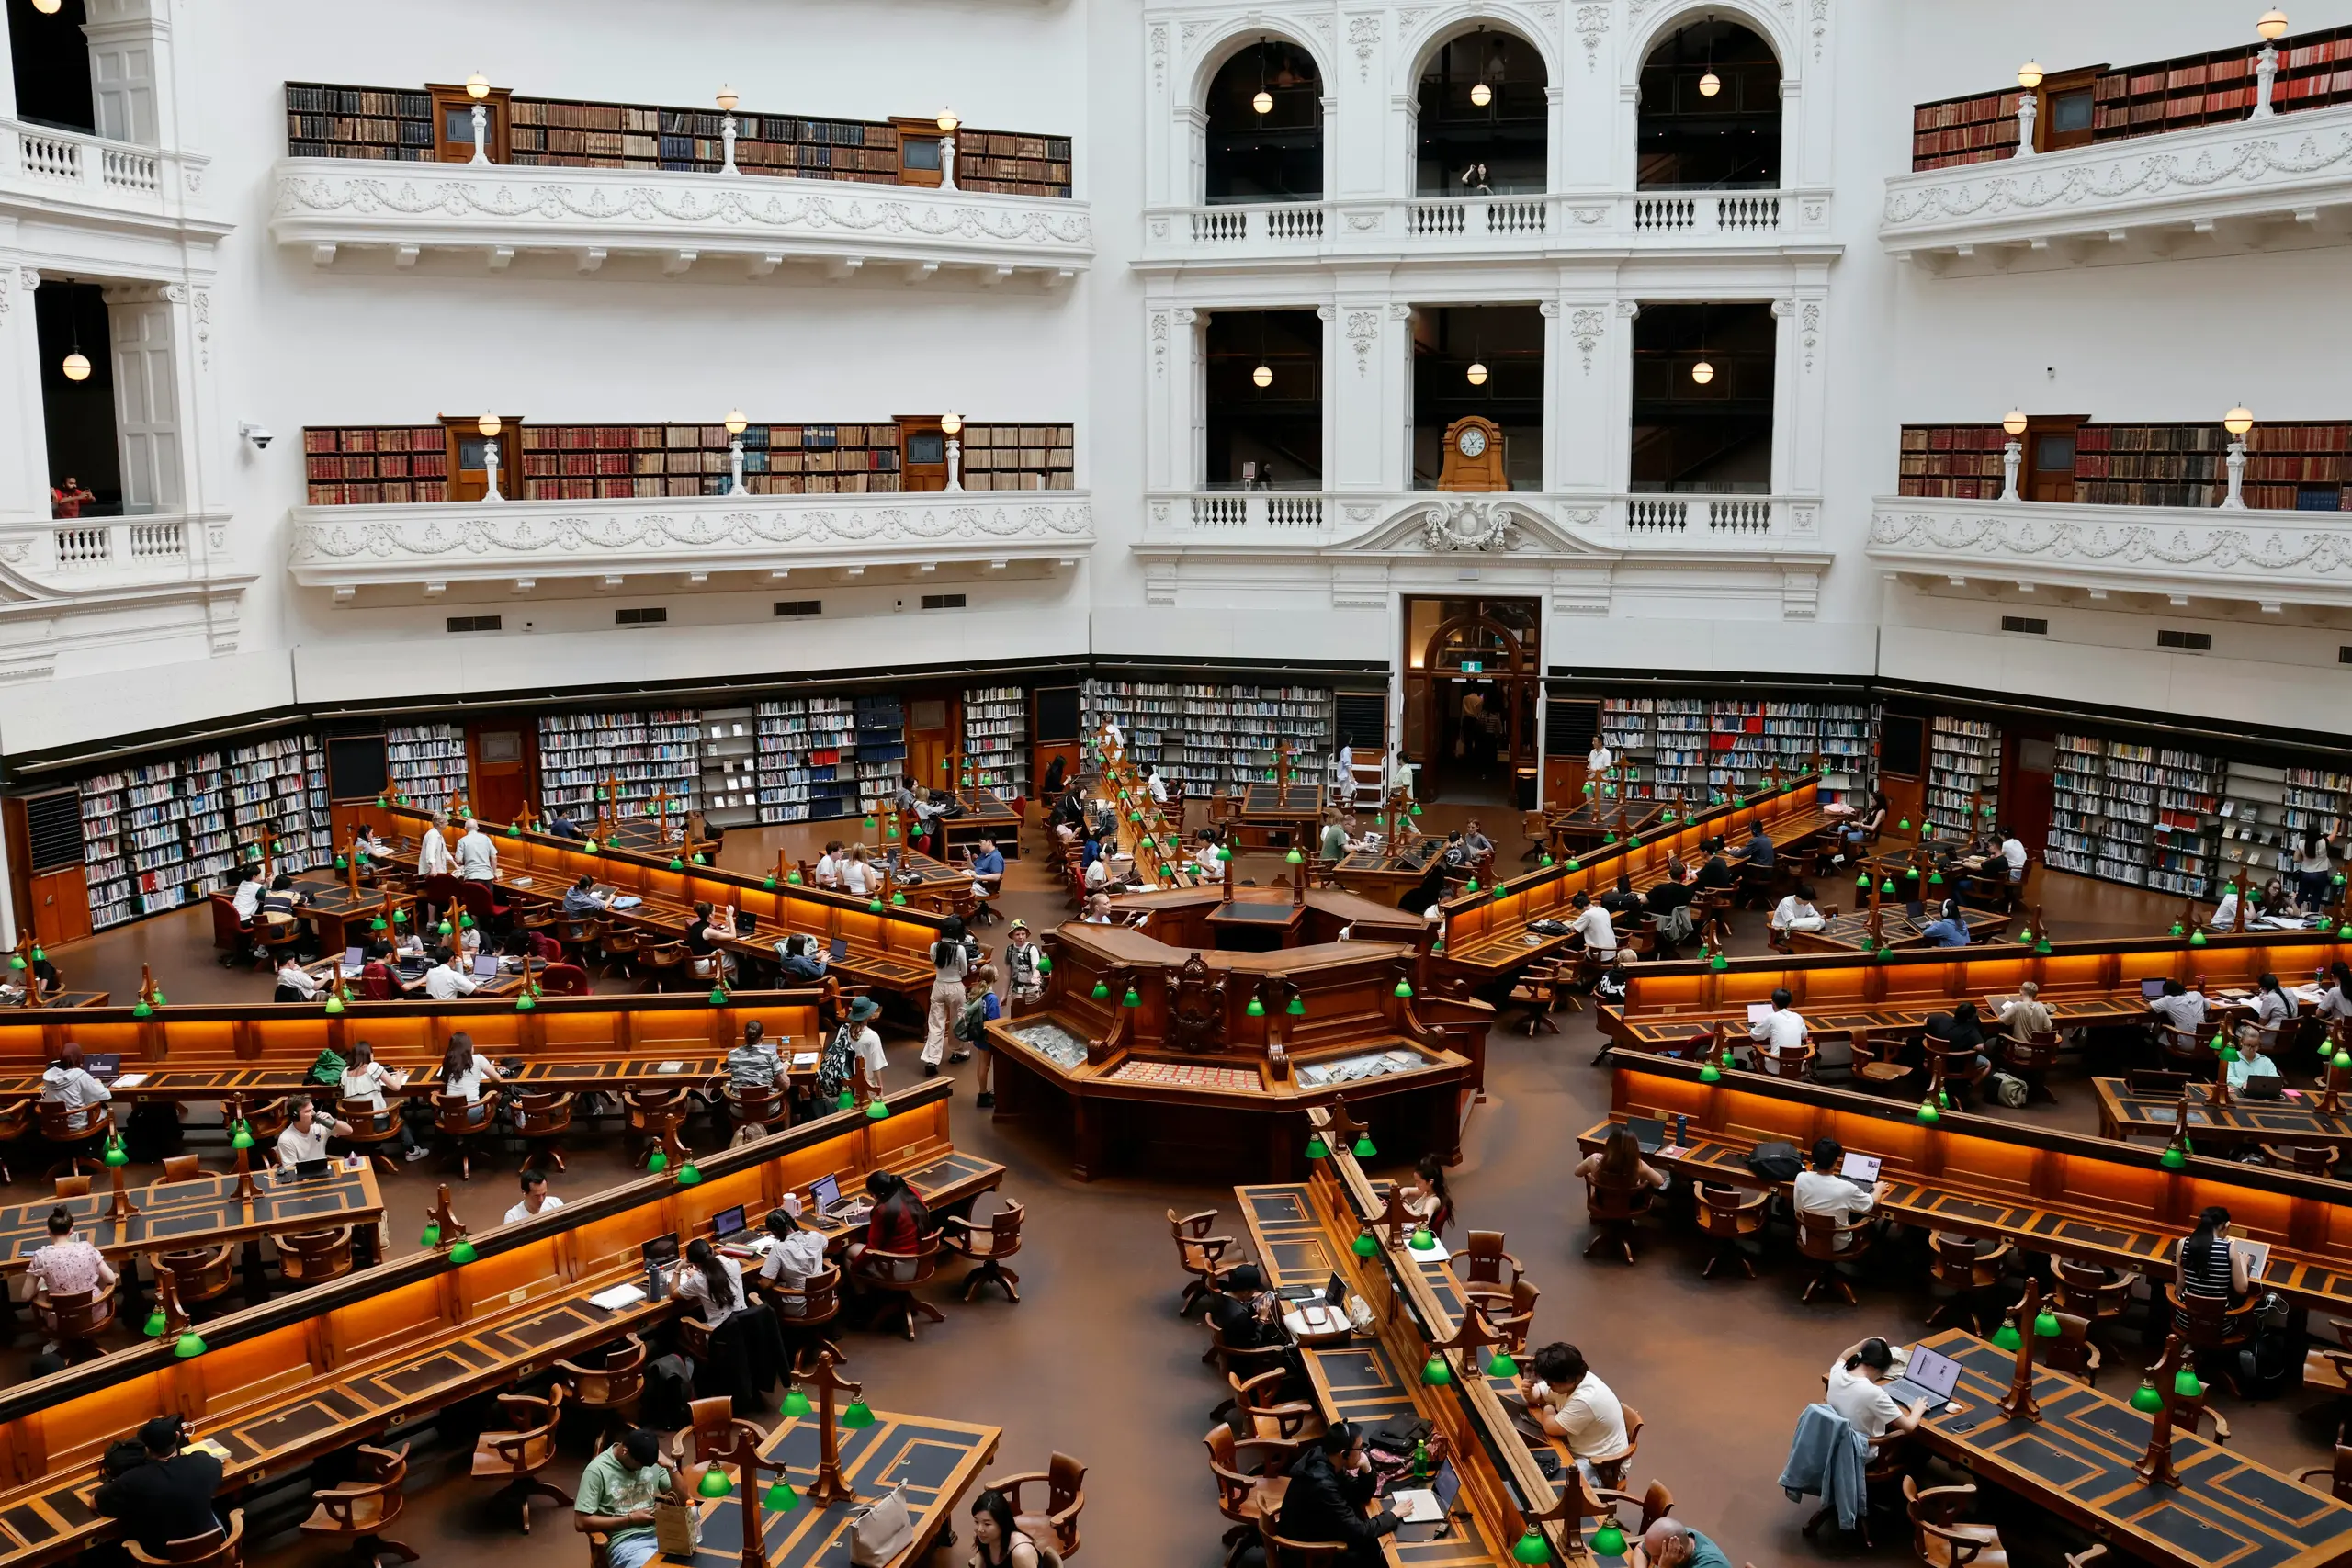

“Implementing NeuralMesh has given the institute the capability to keep pace with the growing demands of our researchers.”

Unify Heavy Research and Creative Pipelines
NeuralMesh unifies complex pipelines, delivering extreme throughput across shared multi-tenant clusters with zero performance stalls.
Frequently Asked Questions
Did this page meet your expectations?