Your GPUs are Waiting. That Impacts Critical Missions.
WEKA NeuralMesh moves encrypted research, classified intel, and sovereign AI data in microseconds, wherever it runs.
Powering National Labs, Sovereign Clouds, & Federal Agencies


USE CASES
One Storage System for All Government Workloads
Federal workloads vary drastically across uses, but they all stall out when compute waits on data. NeuralMesh is a distributed, shared-nothing architecture, so every node serves data, metadata, and I/O in parallel instead of queueing.
Real-time Data Analysis & Processing
NeuralMesh processes and validates real-time sensor and IoT data, cutting the time to actionable intelligence.
Federal Research
NeuralMesh delivers high bandwidth, IOPS, and metadata throughput for HPC, AI training, and agentic workloads at national laboratory scale.
Security & Surveillance
NeuralMesh ingests and processes persistent video, sensor, and ISR streams in real time, enabling sustained AI inference on classified data.
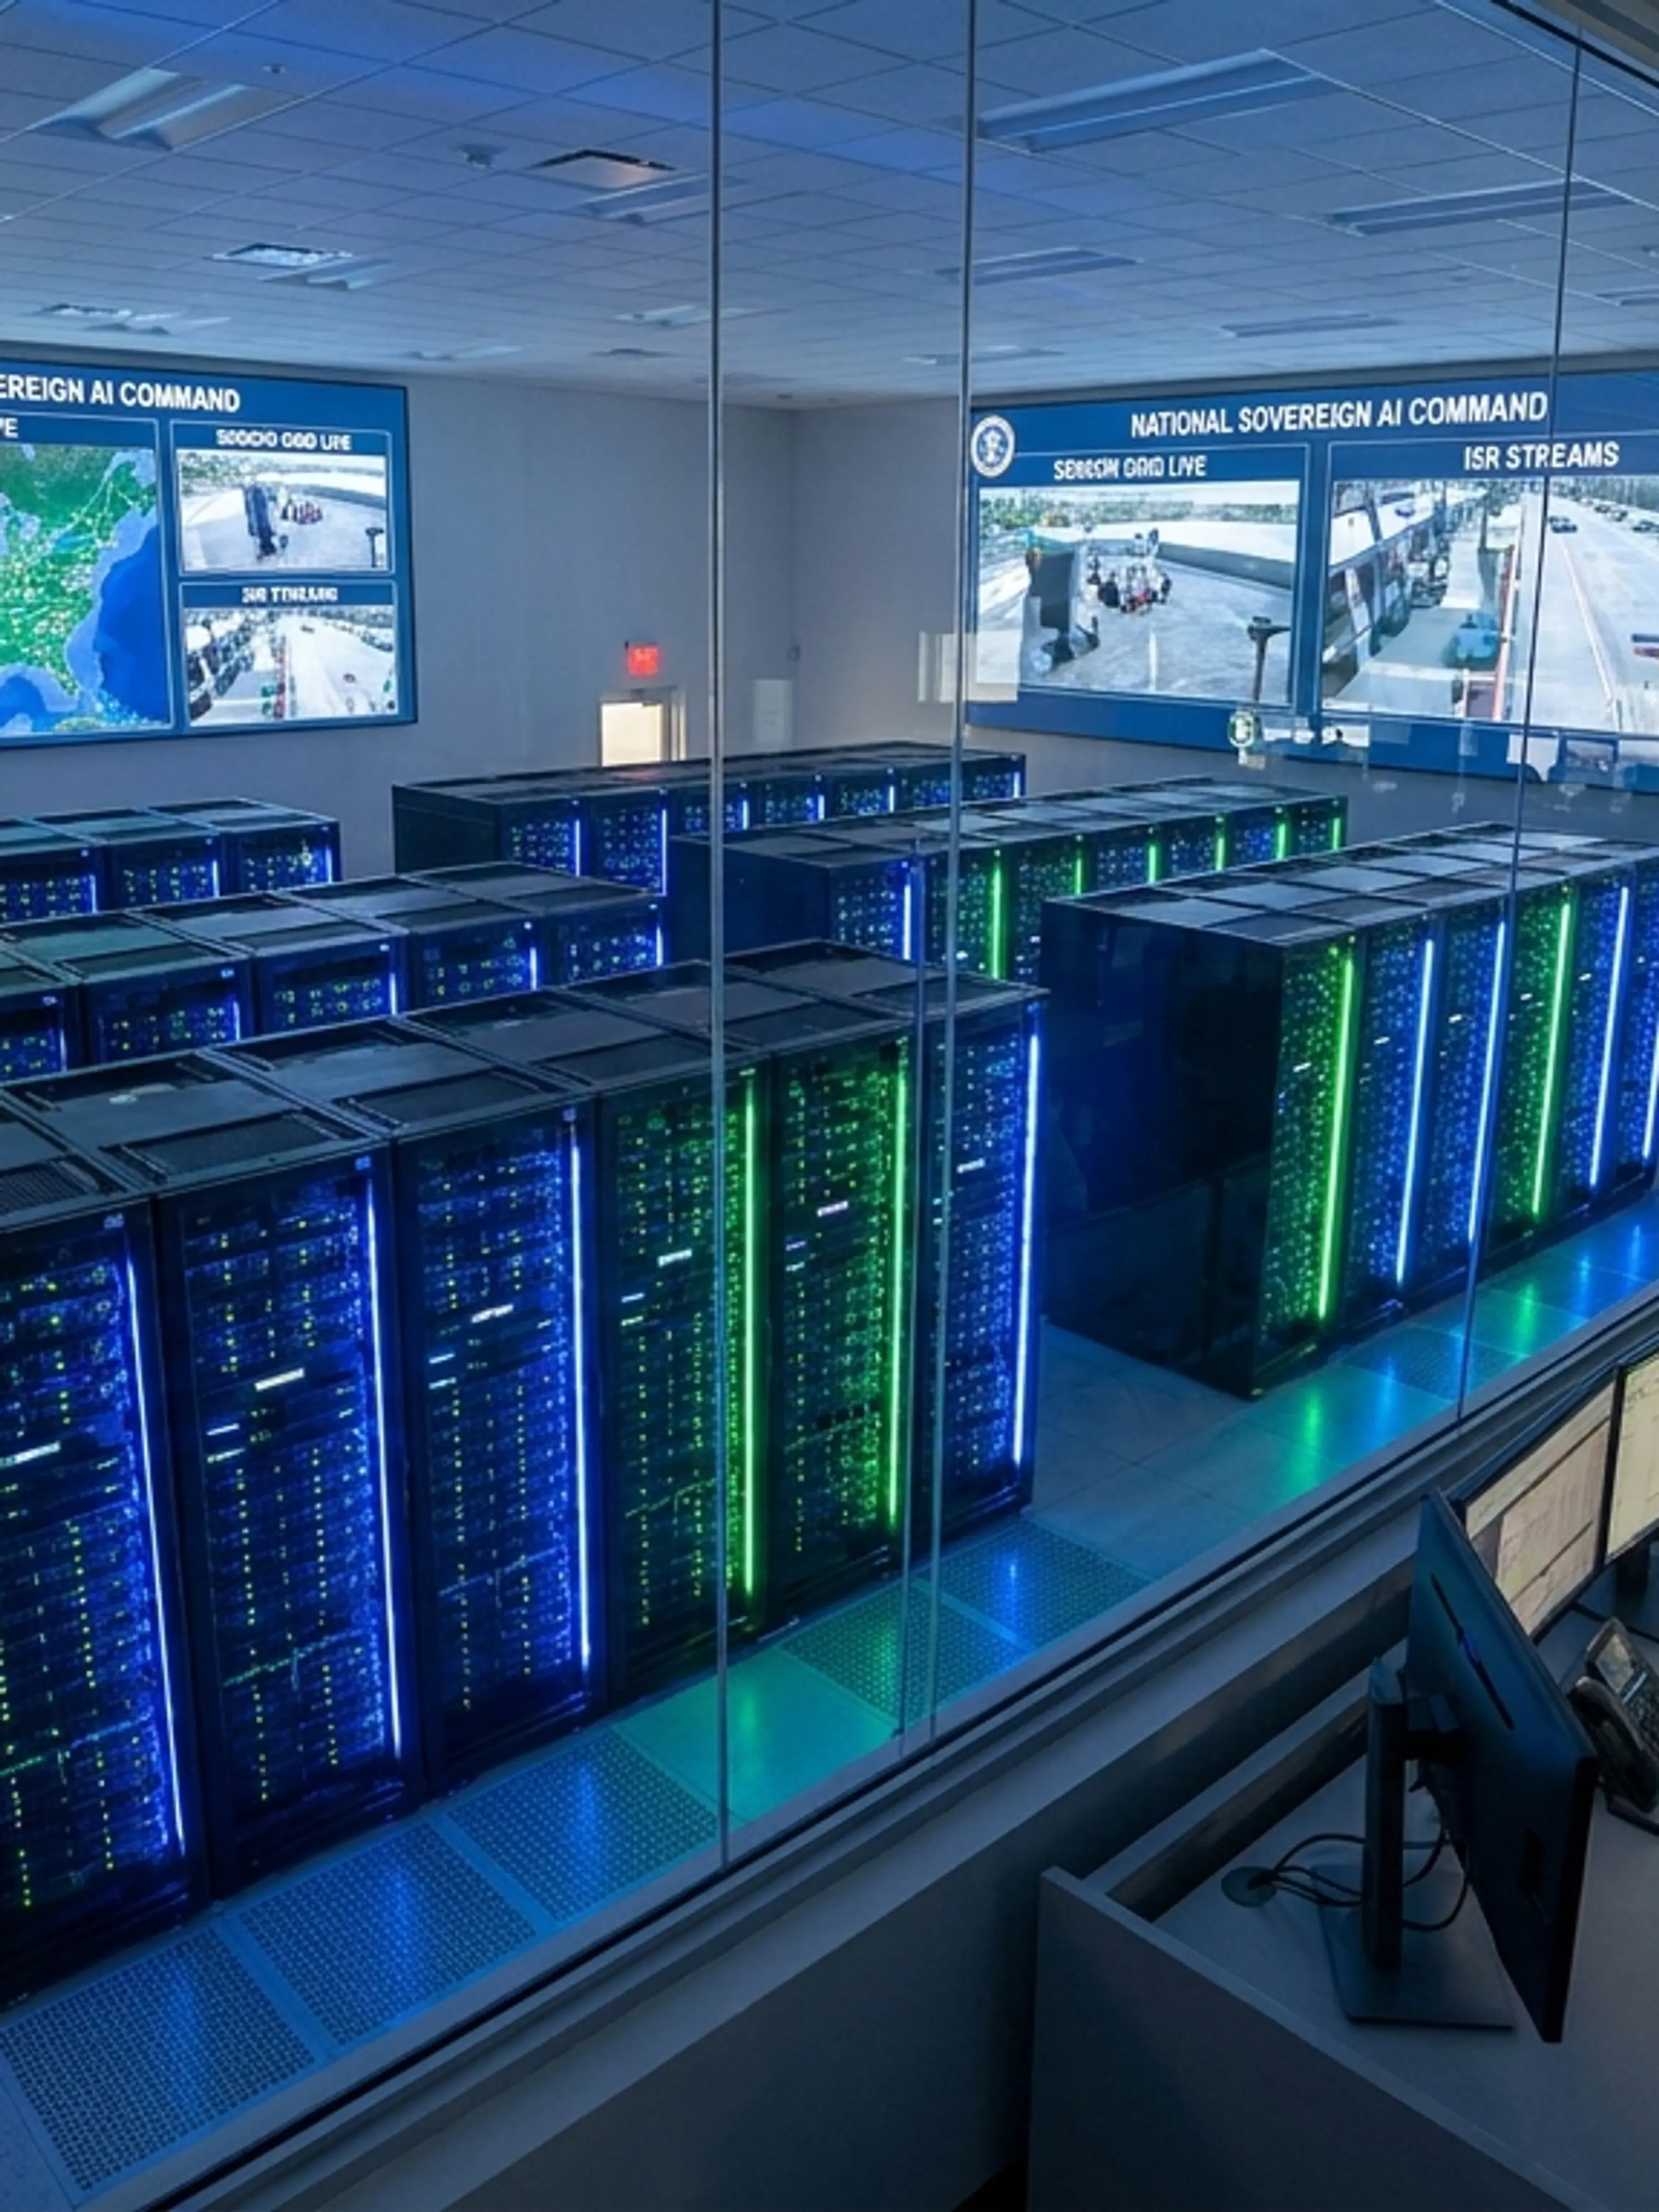
What Agencies Measured After Implementing NeuralMesh
<0.0ms
Latency across 140 GPU clients
NeuralMesh sustains millions of IOPS at sub-millisecond latency while 140 GPU clients read and write at once, so no tenant degrades another.
0%
Less infrastructure to power and cool
A single-tier, software-defined architecture stores more per rack, which pulls down energy draw, cooling load, and operational complexity together.
0PB
Of imagery in a single database
Petabyte-scale imagery archives stay searchable and analyzable in one namespace rather than fragmenting across tiers and separate systems.
0M
People served on one sovereign network
A single NeuralMesh deployment underpins national-scale AI services, with data held inside national borders end to end.
WHY WEKA
Accelerate HPC and AI Workflows for Federal Agencies
Federal data spans classified networks, on-premises centers, and authorized clouds. Legacy storage slows workloads, and multi-million dollar clusters sit idle, wasting resources.
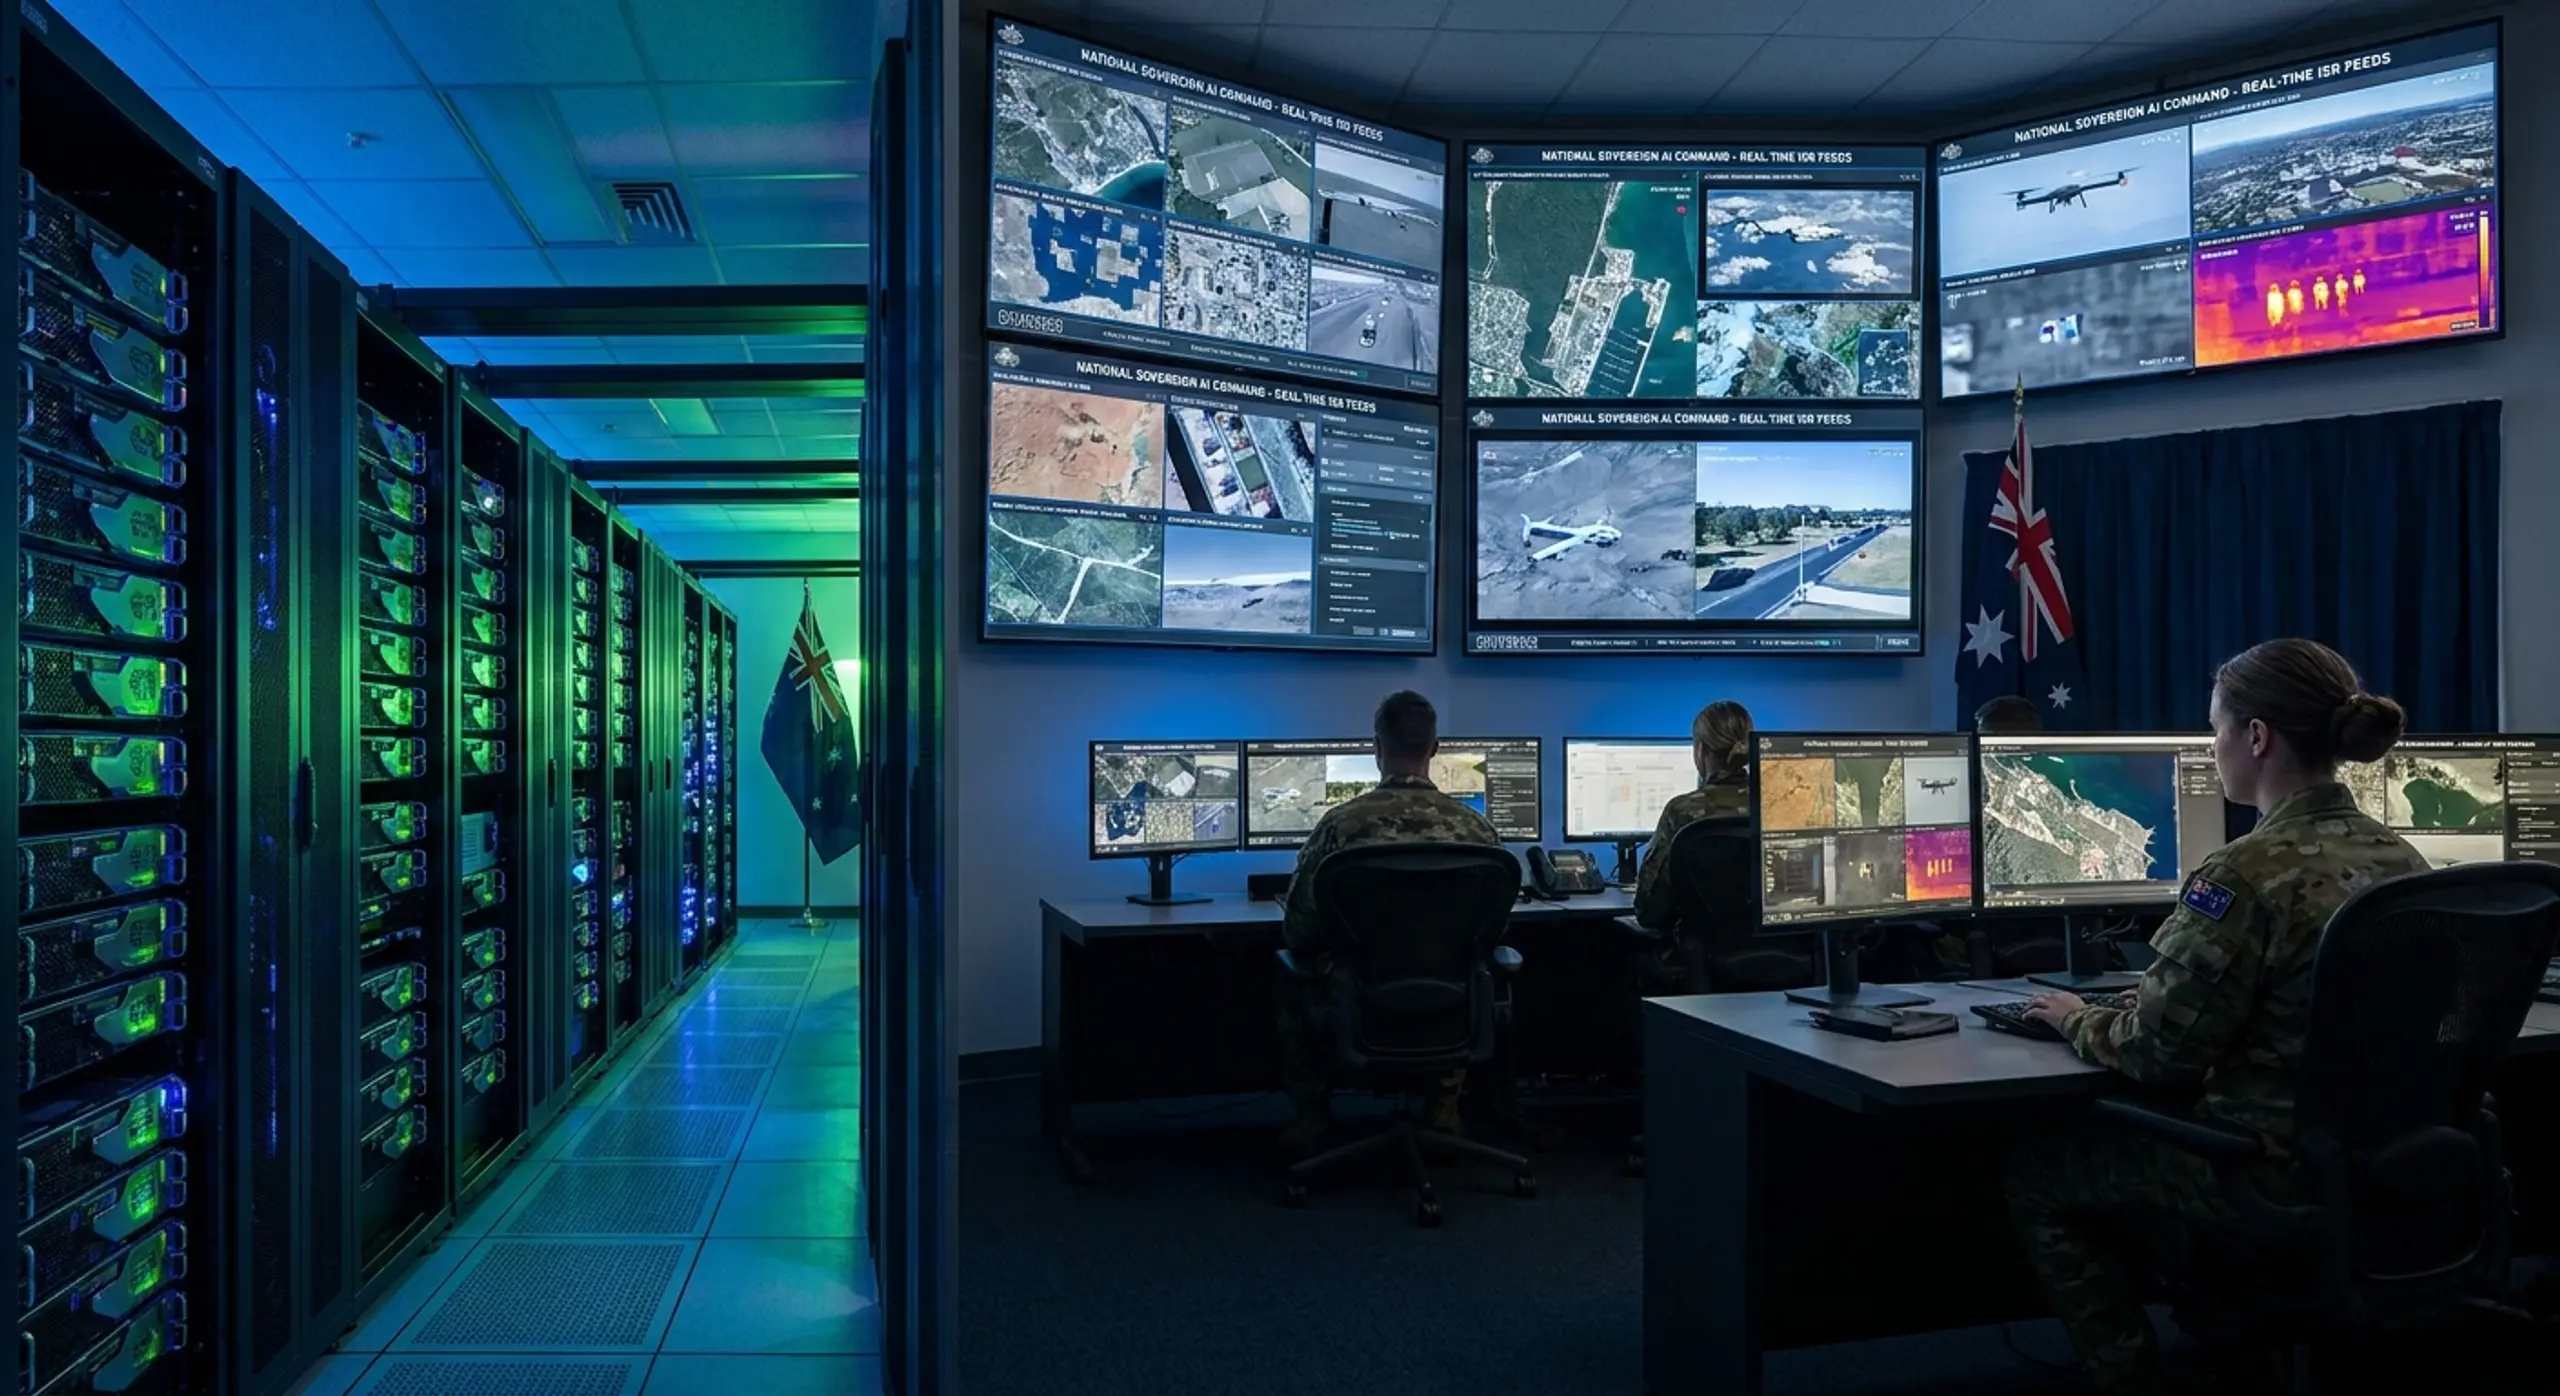
Secure Data Across Classified Environments
End-to-end encryption with zero operator access to your data, plus sovereignty compliance and independent privacy audits, across on-premises, classified, and cloud deployments.
1 / 9
Secure Data Across Classified Environments
End-to-end encryption with zero operator access to your data, plus sovereignty compliance and independent privacy audits, across on-premises, classified, and cloud deployments.
Cut Time to Actionable Intelligence
Consistent sub-millisecond latency holds even under multi-tenant load, so analysts process intel and act on it inside the decision window rather than after it.
Power Mission-Critical AI
Process real-time intel faster, accelerate real-time AI decision making, and speed AI training iterations.
1 / 3

Sunil GuptaCo-founder, Managing Director & CEO • Yotta
“NeuralMesh by WEKA is crucial in optimizing the performance of Yotta’s Shakti Cloud, India’s fastest AI supercomputing infrastructure. Shakti Cloud allows us to provide scalable GPU services to enterprises of all sizes, democratizing access to high-performance computing resources and enabling businesses to fully harness AI through our extensive NVIDIA H100 GPU fleet. With this enhancement, our customers can efficiently run real-time generative AI on trillion-parameter language models. At Yotta, we are deeply committed to balancing data center growth with sustainability and energy efficiency. We are dedicated to deploying energy-efficient AI technologies to minimize the environmental impact of our data centers while continuing to scale our infrastructure to meet the growing demand. WEKA is instrumental in helping us achieve this objective.”


Accelerate Critical AI Without Compromise
Meet strict compliance and sovereign data governance while delivering the extreme throughput your mission-critical models demand.
Frequently Asked Questions
Did this page meet your expectations?