Introducing WEKA OpenSharing for Databricks
WEKA is now a validated external storage provider for Databricks. WEKA OpenSharing for Databricks lets Databricks query data on WEKA® NeuralMesh™—on-premises, in a colo, or in your own VPC—natively through Unity Catalog, eliminating the need to copy the data to the cloud first. This lets high-performance AI and HPC workloads stay anchored on NeuralMesh on-premises for maximum speed, while making their downstream analytical results instantly queryable across the Databricks Data + AI Platform.
Databricks is a Data + AI Platform built on open infrastructure; however, critical datasets often cannot move to the cloud—whether bound by strict residency rules or anchored to a high-performance storage layer feeding GPUs. With the new WEKA OpenSharing capability, teams can now make data that lives on NeuralMesh queryable from Databricks, on their own terms, without duplicating data, migrating data, or handing over infrastructure credentials. As organizations build more AI applications and agents, this gives them an open, governed way to bring enterprise data into their data and AI workflows without forcing that data into a new storage system.
WEKA OpenSharing delivers the following key capabilities
- Remote Cloud Querying Without Migration. Databricks compute engines query NeuralMesh-hosted datasets, pulling only the relevant parquet files into cloud compute rather than copying entire tables or duplicating storage footprints.
- Selective Table Exposure. A NeuralMesh S3 user selects which specific tables to make visible to Databricks from their issued bucket boundary—keeping raw files, unshared directories, and underlying bucket credentials completely isolated.
- Unified Unity Catalog Governance. Databricks workspace admins mount those shared tables as native catalogs, allowing central security teams to manage fine-grained user access (
GRANT SELECT), track audit logs, and enforce group permissions directly in Unity Catalog.
AI workflows on NeuralMesh generate valuable downstream artifacts (e.g., evaluation metrics, inference results, run metadata, and drift statistics) stored as Delta tables right next to the raw datasets that produced them. WEKA OpenSharing lets you simply publish only those analytical tables to Databricks without opening the surrounding namespace or raw data directories. This extends Databricks’ open approach to data and AI, giving organizations governed access to the data they need while preserving choice over where that data lives.
An Example Use Case
Consider a research institute running high-throughput DNA sequencers on a high-performance NeuralMesh cluster, producing terabytes of raw base calls, FASTQ files, and aligned BAM files per run.
Strict institutional compliance governs most of this footprint (hundreds of terabytes of unstructured sequence data). It must stay safely on-premises, and downstream analytics teams rarely access it directly. However, sitting right beside these raw files on NeuralMesh is a lightweight layer of Delta Lake tables capturing the derived scientific and operational output:
- Genomic Variant Calls: Variant matrices (SNVs, indels), allele frequencies, and annotated mutation impact scores.
- Sample and Clinical Metadata: Cohort assignments, patient consent terms, tissue source, and matched-normal QC status.
- Pipeline Run Metrics: Coverage depth, alignment error rates, model versions, and population drift statistics.
Many teams need to tap into this metadata layer
- Internal Researchers and External Collaborators: Need to collaborate with internal lab teams, external biopharma partners, and academic institutions to analyze live genomic variant impacts and protein viability metrics in Databricks notebooks—filtering thousands of candidates down to high-confidence drug targets.
- Data Analysts and Computational Biologists: Need to run queries in Databricks SQL or build Power BI/Tableau dashboards—correlating genomic variants with clinical outcomes or tracking assay success rates across sequencing runs.
- Data Engineers and Security Teams: Need to centralize access control in Databricks Unity Catalog, eliminate credential leaks, and enforce unified governance across environments.
Without WEKA OpenSharing, there are two ways to get those Delta tables into Databricks, and neither is viable. Firstly, users can copy the results into cloud object storage, which can violate strict data locality policies and leaves a duplicate dataset to keep in sync. Second, users can hand the analytics team an S3 key, but a key that reaches the results directory typically exposes the petabytes of raw sequencing data sitting in adjacent directories.
WEKA OpenSharing bridges this gap by letting NeuralMesh publish only those lightweight Delta tables directly to Databricks as a native Unity Catalog share. This means cross-functional teams get immediate, governed access to live results—while petabytes of raw sequence data remain securely stored on NeuralMesh. Teams can use that governed data across analytics and AI workloads on the Databricks Data + AI Platform while maintaining control over where the underlying data is stored.
How it works
The WEKA OpenSharing package functions purely as a lightweight control plane:
- Register: A Databricks workspace administrator imports an OpenSharing credential file (containing an endpoint and a bearer token) into Databricks to mount the dataset as a native share inside Unity Catalog.
- Ask: When a user executes a query, Unity Catalog calls the WEKA OpenSharing package for the table’s schema and the specific list of active Parquet files needed to satisfy the query.
- Sign: The WEKA OpenSharing package generates short-lived, pre-signed URLs granting temporary, read-only access to those files.
- Fetch: Databricks compute pulls those files directly from the NeuralMesh S3 gateway. The NeuralMesh server itself never carries or proxies the table data.
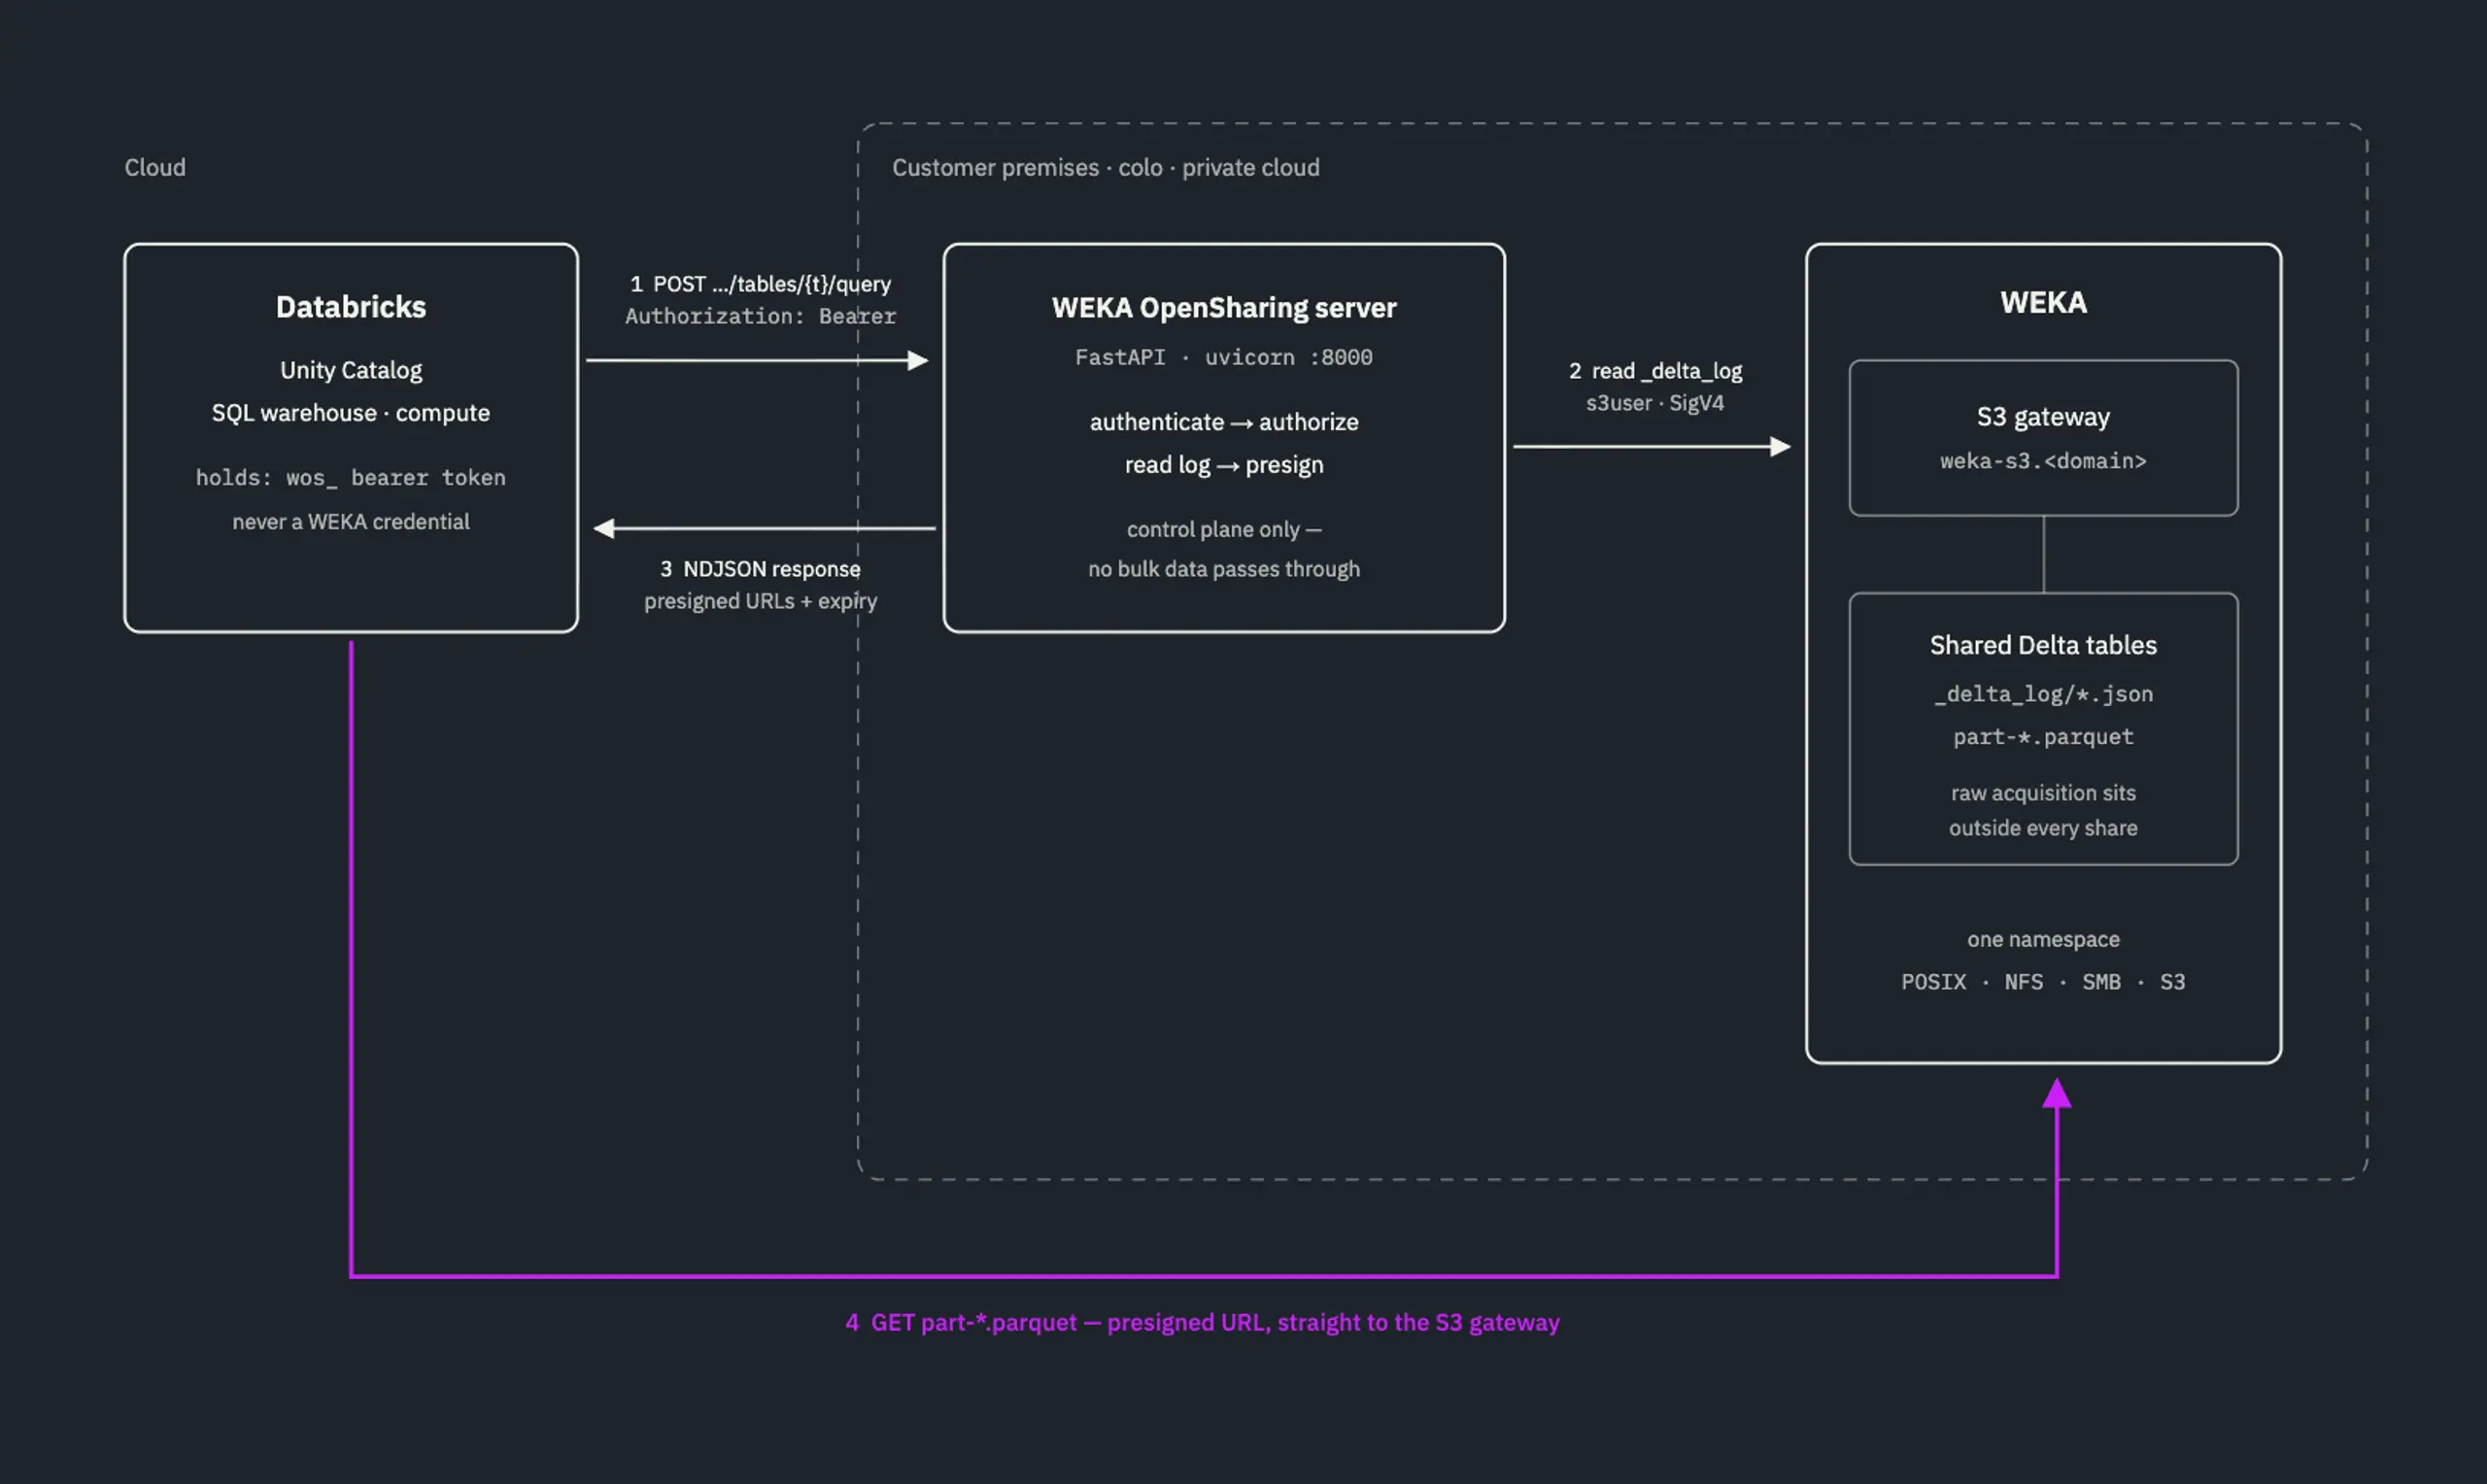
Because the protocol uses S3 presigned URLs to stream data over HTTP from on-premises WEKA NeuralMesh deployments to cloud Databricks, query throughput is WAN-bound, not storage-bound.
What it enables
Before WEKA OpenSharing, teams could connect Databricks to NeuralMesh via a raw S3 endpoint (s3a://). While functional for basic reads, that approach introduced significant governance bottlenecks and security trade-offs. WEKA OpenSharing changes what’s possible by bringing this data into the same open, governed environment organizations use for data and AI workloads:
S3 access alone (s3a://) | With WEKA OpenSharing | |
|---|---|---|
Connection | Cluster reads NeuralMesh directly over s3a:// | Shares mount natively as Unity Catalog objects |
Credentials | Long-lived NeuralMesh access/secret keys stored in cluster Spark configs | Databricks holds a scoped bearer token, never a NeuralMesh key |
Addressing | Unstructured s3a:// paths passed manually between notebooks | Standard 3-level naming (catalog.schema.table) |
Provisioning | Admins manually distribute NeuralMesh keys and edit cluster configs per team | Browser UI auto-discovers tables, builds shares, and generates recipient credentials |
Access Control | Key-level access (holder sees everything the bucket policy permits) | Group-level Unity Catalog permissions (GRANT SELECT) |
Reach | Classic Spark clusters only (excludes Serverless SQL and BI tools) | All query surfaces: Serverless SQL, Notebooks, SQL Editor, CLI, APIs, and BI tools |
This architecture unlocks three core capabilities
- Native Unity Catalog governance. Once mounted in Databricks, WEKA OpenSharing shares appear as native catalogs governed by standard Unity Catalog SQL privileges (
GRANT SELECT). This lets security teams extend existing Unity Catalog governance policies and group permissions directly to WEKA datasets, with zero custom IAM roles or storage-level keys to manage. - Full Serverless and BI compatibility. Because WEKA OpenSharing integrates at the catalog layer, datasets are immediately available across every Databricks query surface — including Serverless SQL Warehouses, Catalog Explorer, notebooks, REST APIs, and external BI tools (Power BI, Tableau, Looker) that query through Databricks.
- Shares built in a browser. A browser UI automates share creation: scanning the WEKA namespace for Delta tables (eliminating manual S3 path mapping), generating pre-formatted Databricks credentials, validating configurations, and automatically hot-reloading the server.
Together, these capabilities support Databricks’ broader OpenSharing vision: an open protocol for securely sharing data and AI assets across clouds and vendors, while giving enterprises the context, control, and choice they need for their data and AI workloads.
What’s next
Our collaboration with Databricks is ongoing as we continue working together on deeper, native capabilities for open, governed data and AI across hybrid environments.
Getting started
If you’re looking to run Databricks natively against data that lives on WEKA NeuralMesh, and learn how to set up OpenSharing in your environment, talk to our team about setting up OpenSharing in your environment.
Did this page meet your expectations?
What’s Next


Scale Production AI Faster with NeuralMesh
Your models aren't slow. Your data is. Fix AI bottlenecks with high-throughput infrastructure.