Beyond the Buzzword: An Economic Perspective on “Tokenomics”
“Token economics” gets tossed around in AI circles with increasing frequency—but rarely with much clarity. Depending on the conversation, it might refer to GPU-as-a-service costs, API billing reports, or some vague reference to AI scaling laws. It’s become a catchall for “this stuff costs money,” and a hand-wavy justification for why inference is getting expensive.
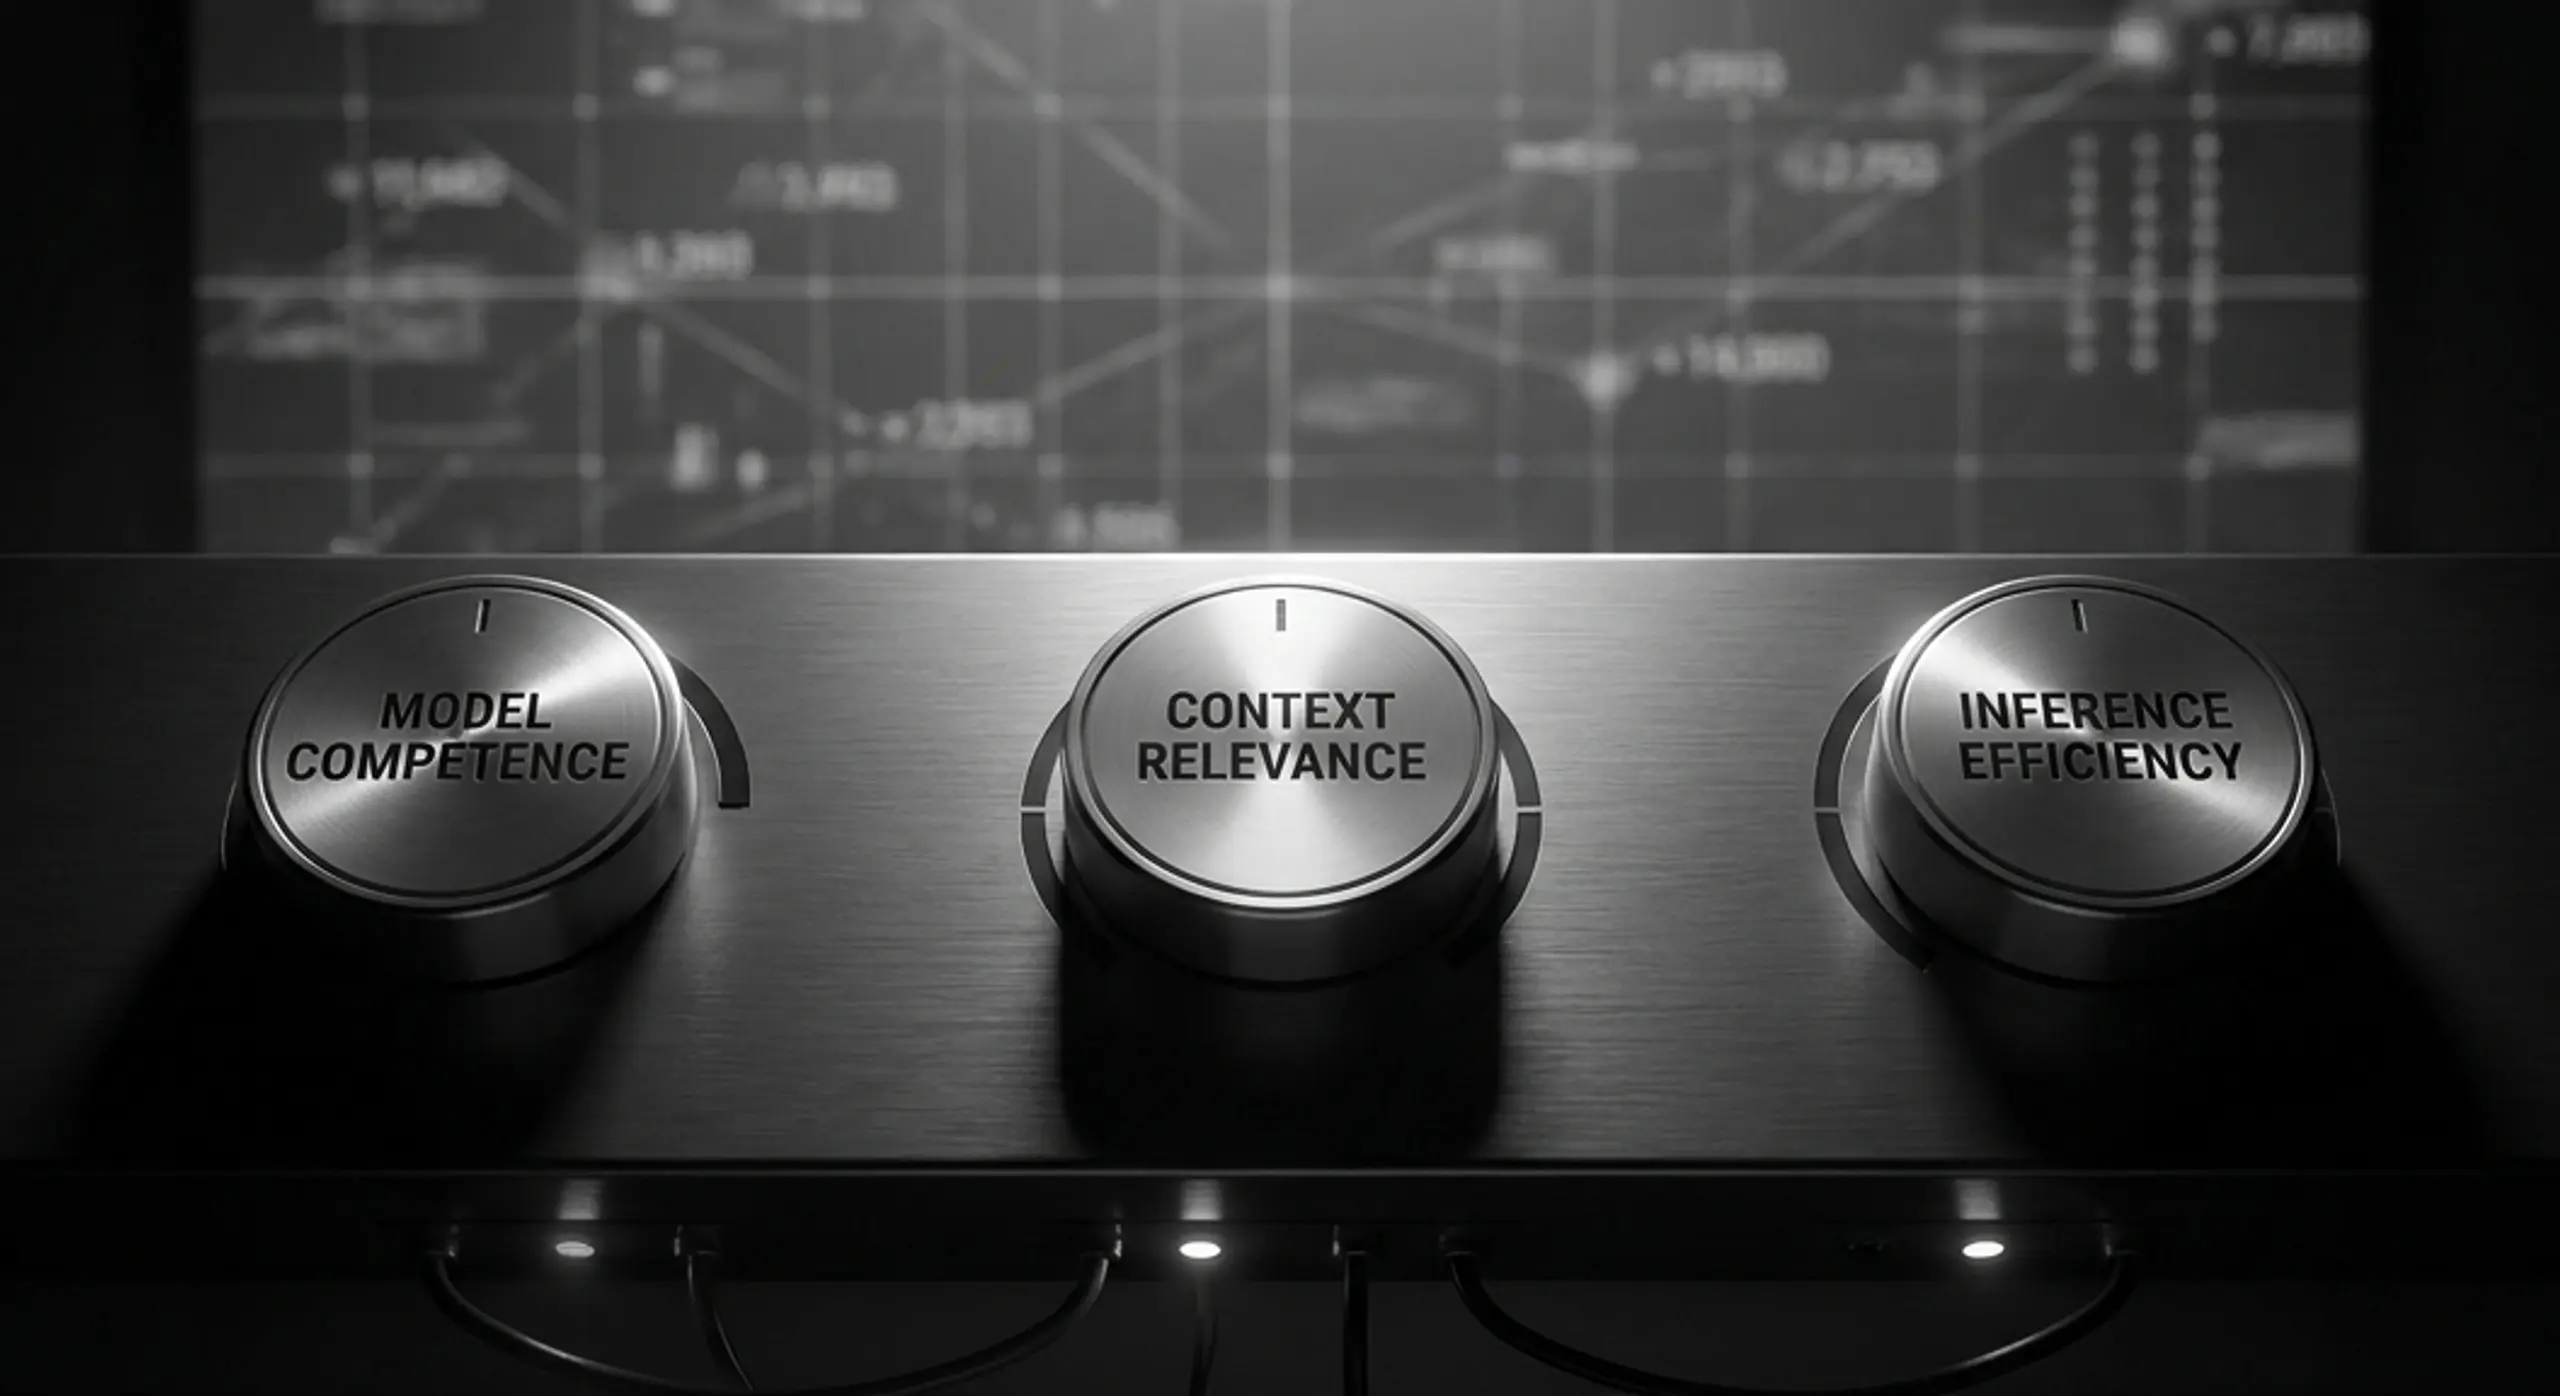
The way I think about it, there are three levers that drive token value: Model competence, context relevance, and inference efficiency. The real hurdle is aligning the knobs engineers can turn with the outcomes the business promises users and stakeholders. Organizations have been making multi-million-dollar decisions about AI workloads using metrics that don’t reflect real economic value. Some organizations with strong AI teams can benchmark the latency and throughput of their serving engine and trace it back to the architectural choices that made it possible. Others, with deep user analytics, can show how response time impacts retention or engagement. But very few can critically evaluate the whole picture—what model gets served, how it’s served, and what context it’s given—and connect those choices to real economic outcomes.
We’ve seen this story before. In the 1990s, networking researchers coined “good‑put” to distinguish raw link throughput from the subset of packets that arrive intact and matter to applications, reframing performance around delivered value rather than brute volume. AI inference is undergoing the same shift today: we’re moving from bragging about tokens‑per‑second to asking how many of those tokens actually advance user goals—linking model competence, prompt relevance, and serving efficiency to real economic impact. Throughput tells you how many tokens you emit; good‑put tells you how many move the needle toward executing on service level objectives (SLOs).
Holding price and resource allocation constant, how can we improve our serving system? How might changes to a serving approach, like switching to a larger model, impact your overall good-put? To better understand how to evaluate changes like this, let’s see how model competence, context relevance, and inference efficiency work together in real-world AI workloads.
1. Model Competence: How Well the Model Understands Language
Model competence encompasses all optimizations done before inference time—the model’s size, architecture, what it was trained on, and the techniques used to fine-tune its behavior. It’s what determines how well the model understands the world—and whether its answers feel sharp, relevant, and coherent.
Comprehensive evaluation suites gauge a model’s intrinsic capabilities by subjecting it to a broad battery of tasks: they test factual recall across academic and professional disciplines, scrutinize the coherence and persuasiveness of its free‑form explanations in head‑to‑head human preference trials, and step through multi‑stage reasoning challenges that reveal whether the logic chain remains sound from premise to conclusion.
Here’s how different aspects of the model’s architecture and training can shape the real-world value of each generated token:
- Capacity and architecture (parameters, depth, attention design).
Larger models raise the ceiling on semantic richness per token, but once past the “right size” extra parameters mostly increase latency, so marginal utility per token flattens. - Training‑data scale and quality.
A broader, cleaner corpus expands the knowledge frontier; each emitted token is more likely to be specific and correct. - Fine‑tuning & alignment.
Retraining on enterprise‑specific content equips the model with your domain language, policies, and objectives, so its tokens arrive immediately relevant and compliant. - Chain‑of‑thought or multi‑step reasoning heads.
Adds intermediate reasoning steps that boost correctness density per answer—especially in math, code, or policy logic.
2. Context Relevance: Supplying the Evidence the Model Needs
Context relevance refers to the information the model sees at inference time—things like retrieved documents, tool outputs, or system prompts. The better that context is curated and delivered, the more grounded and accurate the response. Give the model the right evidence, and it’s far less likely to hallucinate or drift off track.
To measure context relevance, benchmarks track the share of retrieved context that actually matter to the question, the frequency with which the answer stays faithful to those facts (no hallucination), and whether any external tool calls—like calculators or code snippets—return the right results.
These are some of the popular techniques to boost the relevance and factual grounding of your model’s output:
- Retrieval Augmented Generation (RAG).
Higher precision inserts more relevant evidence; each generated token is more likely to be factually correct and sources of the information are known. - Prompt curation and formatting.
Removing boiler‑plate and deduplicating chunks raises information density per input token, which echoes into more meaningful output tokens. - Window length and sparsity mechanisms.
Longer contexts increase potential relevance, but attention cost and latency rise; utility per token grows only while added facts outweigh the delay. - Agentic tool use (calculator, code runner, web search, database query).
External calls replace speculative reasoning with verified facts, so subsequent tokens carry higher factual weight.
3. Inference Efficiency: Delivering Tokens on Time and at Scale
Inference efficiency refers to how well your system delivers tokens once the model is ready to generate. It covers everything from how GPUs are scheduled to how caching and parallelism are handled under the hood. Smooth execution here means tokens arrive faster, responses feel more fluid, and your infrastructure keeps up—no matter the load.
The metrics that matter in inference efficiency are time‑to‑first‑token (TTFT—how quickly the first token is served), inter‑token latency (ITL—how smoothly the tokens keep coming), and tokens‑per‑second (TPS—how much text you push out for every second, often measured per dollar or watt).
The optimizations in model inference are myriad and varied, but these are some of the key levers for making sure your infrastructure can sustain peak token goodput—ingesting and generating tokens smoothly even when traffic surges or workloads fluctuate.
- Parallelism strategy (tensor, pipeline, expert/MoE, emerging forms).
Different splits shift bandwidth load and synchronization overhead, altering tail latency and throughput. - Serving Architecture(Aggregated vs Disaggregated Serving).
Decoupling inference into prefill and decode, a technique known as Disaggregated Serving, allows you to match each phase to the most efficient hardware and the right amount of it. This allows for more control to maximize goodput based on variable workloads and variable SLOs. - KV cache management.
Moving cached keys and values to the right GPU at the right moment eliminates redundant compute, so tokens arrive sooner and batched serving is uninterrupted. - Dynamic scaling.
Elastic fleets that downshift during traffic troughs and upshift at peaks raise GPU utilization, giving you more flexibility to utilize available resources for other kinds of serving optimizations like model fine tuning. - Quantization at serve time.
Lower‑precision trims memory traffic and makes the forward pass more efficient; delivery is quicker while token semantics stay effectively unchanged (up to a point). - Batching, speculative decode, and other more complex optimizations.
A growing toolbox of advanced execution tricks keep pushing latency lower and throughput higher, but they also introduce complexity and a wealth of dependencies.
Value in Action
Now we have this framework, how can we use it to analyze and inform inference decisions? Let’s walk through an example.
You upgrade from Llama‑70B to Llama‑405B to chase higher accuracy. The heavier weights won’t fit on your current GPUs at full precision, so you quantize them down to INT4. You get a little bit less value from the larger model at this point, but that shrinks the weights and the KV‑cache enough to load into the VRAM you have available. Your model competence has improved now, but inference is still slower than the 70B baseline and your KV-cache is larger than it used to be.
To avoid out‑of‑memory errors as sessions pile up, you trim the per‑request context window. Latency stabilises, yet answer quality slips because the model no longer sees all the relevant evidence. You restore quality by raising the max context length again, then lower the batch size to stay within VRAM limits.
Final state: Answer quality is modestly better than with 70B, but TPS and ITL are lower and TTFT is higher. Whether the upgrade is worth it now hinges on your application: do the more accurate—but fewer and slower—tokens generate enough additional business value to outweigh the lost capacity and increased latency?
In a high-stakes financial modeling application—where even a small boost in accuracy can prevent million-dollar missteps—the tradeoff may be well worth it. Slower throughput and higher latency are acceptable if each output token carries significantly more predictive power and drives better decision-making.
But in a customer-facing chatbot designed to handle thousands of concurrent users, the equation flips. Here, speed, scale, and responsiveness are paramount. If users experience lag or timeout errors, you lose engagement—and potentially customers—regardless of marginal gains in answer quality.
It’s not about whether Llama‑405B is “better” than 70B, but whether it’s the better fit for the job you need done.
Conclusion
Optimizing real‑world token value is a balancing act: every tweak to the model, context, or serving stack nudges the other two. Yet it’s exactly these interlocking decisions that turn raw compute into tangible business impact. As more organizations begin to push their AI inference roll outs to scale these tradeoffs will become increasingly complex. The next leap in inference performance won’t come from hardware alone—it will come from coordinating model weights, retrieval pipelines, and cache locality at scale.
At WEKA we have a strong history of working with our partners to optimize exactly these kinds of distributed systems at scale. If your roadmap points toward larger contexts, heavier models, or stricter latency SLOs, let’s compare notes and put those insights to work.
Did this page meet your expectations?
What’s Next


Scale Production AI Faster with NeuralMesh
Your models aren't slow. Your data is. Fix AI bottlenecks with high-throughput infrastructure.